How should a small business measure outsourced IT performance?
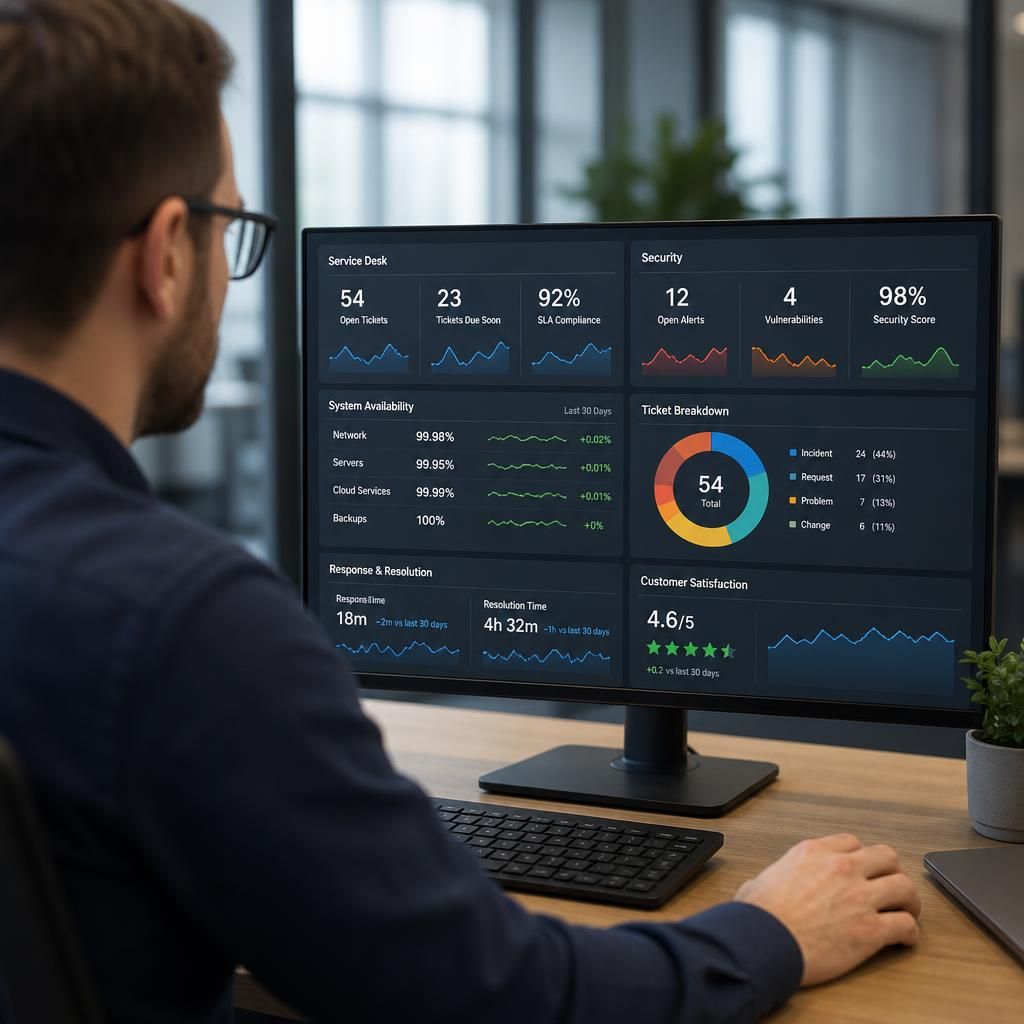
A small business should measure outsourced IT performance against agreed service, security and business-outcome indicators, rather than relying on the number of support tickets closed. Useful evidence includes trend data, issue resolution quality, system availability, security activity, user feedback and regular reviews against business priorities.
Small businesses should measure outsourced IT performance through a balanced scorecard that combines service data, risk reduction, operational reliability and business impact. The most useful assessment is not the volume of tickets closed; it is whether the provider is reducing disruption, resolving underlying causes, managing risk and supporting the organisation’s priorities.
Start with agreed definitions and a baseline
Performance cannot be assessed consistently unless the business and provider agree what is being measured. Before setting targets, record the current position where possible, including recurring faults, unresolved risks, important systems, known availability problems, backup arrangements and user pain points. This baseline makes it possible to distinguish genuine improvement from a change in reporting style.
Each measure should have a clear definition, data source, reporting period, owner and escalation route. For example, “resolved” should mean that the user’s issue is addressed and the service is functioning as expected, not simply that a ticket has been closed. Similarly, response time and resolution time should be treated as separate measures because a quick acknowledgement does not necessarily indicate effective support.
Use service desk measures carefully
Service desk data is useful for identifying patterns, but it should be interpreted rather than treated as a simple league table. Relevant measures can include:
- the number and type of requests and incidents;
- the age of open tickets and the number approaching an agreed service threshold;
- the proportion of issues resolved at the appropriate support level;
- the number of repeat incidents linked to the same underlying cause;
- tickets reopened because the original fix was incomplete;
- requests awaiting information, approval or action from the business; and
- the quality and usefulness of ticket notes and user communications.
Ticket volume alone can be misleading. A rise may indicate better reporting, a new system rollout or a previously hidden problem. A fall may mean that users have stopped reporting issues, workarounds are being used, or the provider is recording work differently. Look for trends alongside context and investigate material changes.
Measure resolution quality, not just speed
A provider can appear efficient while repeatedly applying temporary fixes. To test resolution quality, review whether incidents are fully resolved, whether root causes are recorded for recurring problems, and whether preventative actions are completed. A useful review separates:
- one-off user requests;
- repeat incidents caused by an unresolved technical or process issue;
- major incidents requiring structured investigation; and
- problems identified before they affect users.
For significant incidents, ask for a concise post-incident record covering the cause, effect, actions taken, lessons learned and any changes required. The purpose is not to assign blame. It is to establish whether the same failure is likely to happen again and whether the agreed corrective action has been completed.
Assess reliability against business requirements
System reliability should be measured in relation to the systems the organisation actually depends on. Consider whether important applications, connectivity, devices and cloud services are available when needed, and whether faults are concentrated around particular sites, users or services. Planned maintenance and unplanned disruption should be recorded separately so that the figures are not confused.
Availability data also needs to show the business effect of an interruption. A short problem affecting a non-critical tool may be less significant than a longer problem affecting order processing, production, customer records or access to essential files. The service review should therefore connect technical incidents with affected processes, users and lost working capability.
Track security performance as an ongoing control
Security should be measured by the effectiveness of controls and the evidence that they are being maintained. Depending on the agreed scope, a dashboard may include:
- security alerts investigated and their outcomes;
- critical updates and vulnerabilities identified, prioritised and remediated;
- endpoint, identity and access controls that are not operating as intended;
- user access changes following starters, leavers or role changes;
- backup jobs, failed backups and restoration tests;
- security awareness activity and reported suspicious events; and
- open security actions, their owners and their due dates.
These measures should show exposure and corrective action, not merely the number of alerts generated. A high alert count may reflect effective monitoring, while an apparently quiet environment may indicate limited visibility. The important questions are whether risks are prioritised, whether actions are completed, and whether evidence is available to support the conclusions.
Evaluate changes and preventative maintenance
Outsourced IT performance also depends on how well the provider manages change. Review whether changes are documented, approved by the right person, tested where appropriate and followed by a check that the intended result was achieved. Record failed changes, emergency changes and changes that caused incidents separately from routine successful work.
Preventative activity should be visible in the reporting. Examples include technology reviews, capacity checks, lifecycle planning, patch management, configuration reviews and testing of recovery procedures. These tasks may not generate support tickets, but they can be more valuable than simply responding to faults after they occur.
Include user and stakeholder feedback
Technical reports do not capture every aspect of service quality. Ask users and managers whether communication is clear, whether advice is understandable, whether issues are followed through, and whether the provider understands the effect of IT problems on their work. Feedback should be gathered consistently and reviewed alongside operational data rather than replacing it.
Complaints and positive comments should both be analysed for themes. A single poor experience may reveal a process weakness, while repeated favourable feedback about a particular service may show that the process is working well. Avoid relying on a single satisfaction score without examining the reasons behind it.
Measure alignment with business priorities
The provider should be assessed against the organisation’s current priorities, not only against technical tasks. For a growing business, this might involve preparing new users or locations, improving remote access, supporting a business application, replacing ageing equipment or strengthening protection around sensitive information. For a multi-site organisation, consistent configuration and dependable connectivity may be more important than isolated ticket statistics.
At each service review, compare completed work with the agreed technology plan. Identify what has changed in the business, which risks remain, what decisions are needed and whether planned improvements are still appropriate. This turns the review from a retrospective report into a management process.
Review cost and value in context
Cost should be reviewed against the scope and level of service provided, not considered in isolation. Check whether the agreed charges match the services delivered, whether additional work is recurring, and whether avoidable incidents or outdated equipment are creating extra expense. A lower invoice does not necessarily represent better value if it leaves important risks unmanaged or transfers substantial administration back to the business.
Value is easier to assess when the provider explains the reason for recommendations, the risk of delaying them and the expected operational effect. This gives the business a basis for prioritising investment without assuming that every proposed technical improvement is equally urgent.
Use a regular service review cycle
A practical review pack should show current results, movement since the previous review, exceptions, unresolved actions, emerging risks and decisions required from the business. Give each action an owner and due date, then check completion at the next review. Significant incidents, security concerns and business changes may require attention between scheduled reviews.
Finally, revisit the measures themselves. If a KPI encourages ticket closure at the expense of lasting resolution, it is poorly designed. If a report contains extensive data but does not support a decision, simplify it. Effective outsourced IT measurement produces evidence that helps the business decide what to fix, what to improve and what risk it is prepared to accept.
Outsourced IT performance should be measured against the responsibilities the provider can reasonably control. Separating provider actions from business dependencies makes KPI results fairer and shows where corrective action is actually needed.
For each measure, identify whether the outcome is:
- Provider-controlled, such as the quality of technical remediation, accuracy of documentation or completion of agreed maintenance;
- Shared, such as resolving an incident that depends on access, approval or information from both parties; or
- Business-controlled, such as approving a recommendation, replacing unsupported equipment or ensuring staff follow an agreed process.
This distinction prevents a service review from treating every unresolved issue as a provider failure. It also highlights delays that require a decision within the business. Where responsibility is shared, record the dependency, the person responsible for the next action and the effect of any delay. The result is a more useful assessment of outsourced IT performance than a single overall score.