How should an outsourced IT department measure service quality?
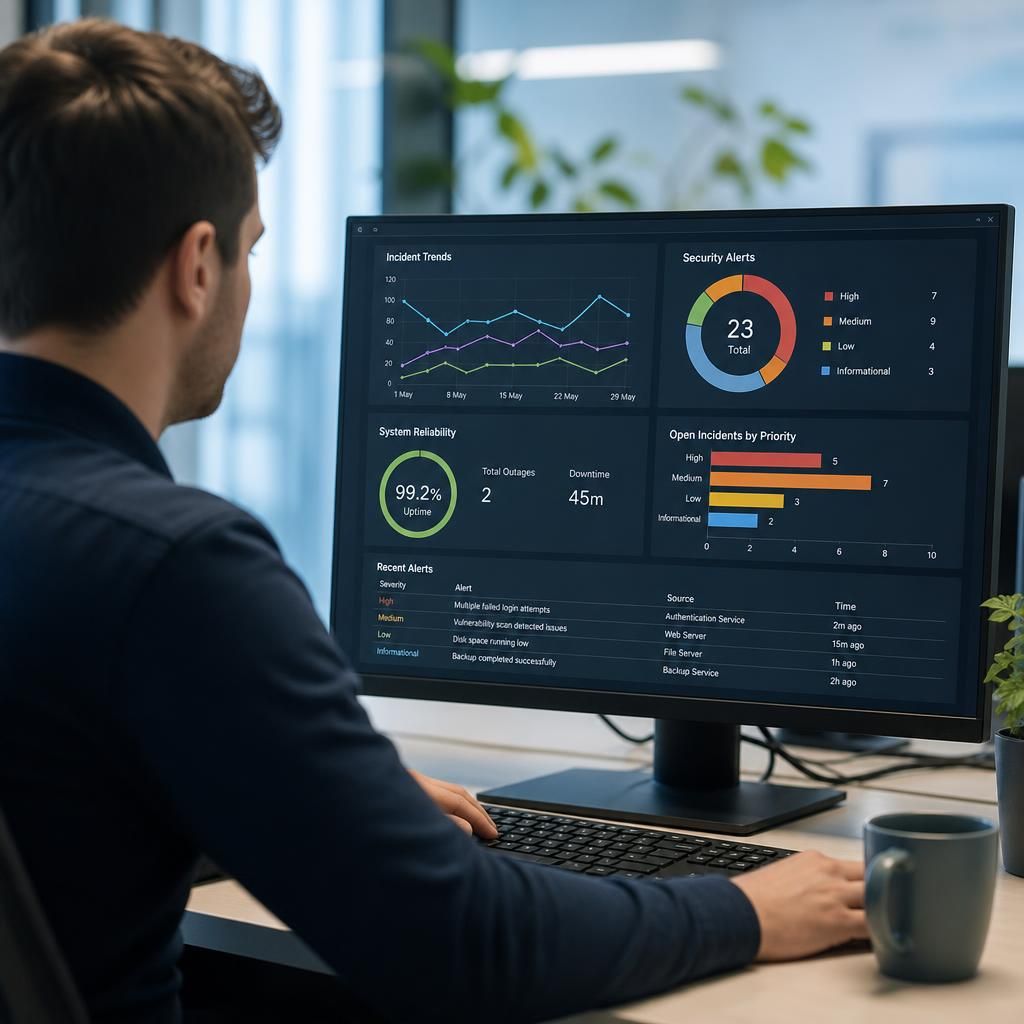
An outsourced IT department should measure service quality against agreed service levels and business outcomes, not just the number of support tickets closed. Useful measures include response and resolution performance, system reliability, security control effectiveness, recurring issue trends, user feedback and the provider’s contribution to business continuity and technology improvements.
Service quality should be measured through an agreed scorecard that combines operational performance, risk reduction, user experience and business impact. No single metric gives a reliable view of an outsourced IT department. A provider may close a large number of tickets while recurring faults remain, or meet response targets while important security weaknesses are not addressed. Effective measurement therefore considers both day-to-day delivery and whether the IT function is becoming more controlled, dependable and suitable for the organisation’s plans.
Start with clear service definitions
Before setting targets, the organisation and provider should define what each service measure means. For example, “response” might mean acknowledgement by a service desk, whereas “resolution” means that the user has a workable solution or an agreed temporary workaround. The definitions should also explain when the measurement clock starts, which requests are excluded, how user-caused delays are treated and how incidents affecting multiple people are recorded.
These details prevent reports from presenting technically accurate but misleading results. The service agreement should distinguish between incidents, service requests, changes, problems and security events, because each category requires different measures and priorities.
Assess performance against business priorities
Targets should reflect the effect of an issue on the organisation rather than treating every ticket identically. A failure affecting a core operational system, several sites or a customer-facing process should be assessed differently from a low-impact software request. Useful measures can include:
- the number and business impact of priority incidents;
- the time taken to restore an important service;
- the age and risk of unresolved tickets;
- the proportion of requests completed within the agreed service level;
- the number of incidents caused by a failed or unauthorised change; and
- the volume of work waiting for information, approval or access.
Priority rules should be agreed in advance. Otherwise, an organisation may see good results simply because issues are classified at a lower severity than their operational consequences justify.
Measure reliability, not just individual faults
Reliability is better understood through patterns over time than through isolated support records. The provider should report repeated outages, recurring faults, failed changes, capacity concerns and dependencies between systems. Mean time between failures can be useful where the underlying data is consistent, but it should be accompanied by the business effect of each failure and the corrective action being taken.
Where a problem keeps returning, the report should show whether a root-cause investigation has been completed, whether a permanent fix has been approved and whether the workaround remains acceptable. A declining ticket count is not necessarily an improvement if users have stopped reporting issues or if problems are being left unresolved.
Test the strength of security controls
Security quality should be assessed through evidence that controls are operating, rather than through general statements that the environment is secure. Relevant evidence may include:
- completion and outcome of security updates;
- coverage of endpoint protection and monitoring;
- review of privileged and inactive accounts;
- results from vulnerability assessments;
- completion of staff security training where this forms part of the service; and
- records of security incidents, investigations and lessons learned.
Reports should identify exceptions, their business risk, the person responsible for addressing them and the planned completion date. Security measures should not be reduced to the number of alerts generated, since a high alert volume may indicate effective detection, poor configuration or both.
Include user and stakeholder experience
Technical performance does not always reflect how well the service supports employees. Feedback should be collected in a consistent way after significant interactions or through periodic service reviews. Useful questions concern clarity of communication, understanding of the issue, quality of the solution and whether the user knows what will happen next.
Feedback should be analysed alongside ticket data. A low number of complaints may reflect low usage of the service desk, while repeated dissatisfaction with a particular process may indicate a training, documentation or service-design problem rather than an individual support issue.
Measure the provider’s management of change and improvement
An outsourced IT department should be assessed on how it prevents avoidable disruption and improves the environment. Measures may include the quality of change records, the proportion of changes that require rollback, completion of agreed improvement actions and progress against the technology roadmap.
Every improvement action should have a defined owner, rationale, dependency and status. This makes it possible to distinguish completed work from activity that has merely been discussed. It also shows whether the provider is dealing with underlying technical debt, outdated documentation, unsupported systems or weak processes.
Use reporting that can be verified
A useful service report should show the reporting period, the agreed target, the actual result, the trend, exceptions and the action required. It should be possible to trace important figures back to service desk records, monitoring systems, security tools or change documentation. Any change in measurement method should be explained, as changing the way tickets are categorised can make performance appear to improve without any operational change.
Data ownership and reporting responsibilities should be documented. The organisation should know which records it can access, how long relevant evidence is retained and how disputed results are reviewed. This is particularly important when the provider uses its own service management platform.
Review quality at governance meetings
Operational reports should feed into structured service reviews rather than being treated as an end in themselves. The review should examine unresolved risks, repeated incidents, security exceptions, upcoming business changes, capacity and progress against agreed actions. Senior stakeholders should focus on whether the service is supporting business objectives, while operational contacts can investigate individual tickets and technical causes.
Targets should be revisited when the organisation changes its systems, locations, regulatory obligations, working practices or dependence on technology. A measure that was appropriate for a smaller environment may not reflect the risks of a growing or multi-site organisation.
The most dependable assessment combines quantitative evidence with informed review. Service levels show whether agreed processes are being followed; trend and root-cause information show whether the environment is improving; security evidence shows whether risk is being controlled; and stakeholder feedback shows whether the service is usable. Together, these measures provide a more accurate basis for judging an outsourced IT department than ticket volume or a single headline score.
Outsourced IT service quality should also be measured by how the provider manages missed targets, not only by whether targets are achieved. A single delayed resolution may have a different significance from repeated failures affecting the same service, priority or business process.
Agree in advance how material service failures will be classified and escalated. The review should establish whether the cause was insufficient capacity, poor prioritisation, an unclear responsibility or a weakness in the service design. It should then record the corrective action, accountable owner and review point. Where the contract provides for formal remedies, these should be applied consistently rather than negotiated afresh after each incident.
A useful measure is therefore the pattern of missed commitments and the quality of the response that follows. Transparent explanations, effective corrective action and a reduction in repeat failures provide stronger evidence of service maturity than a headline compliance figure that conceals unresolved problems.