How should network resilience be tested?
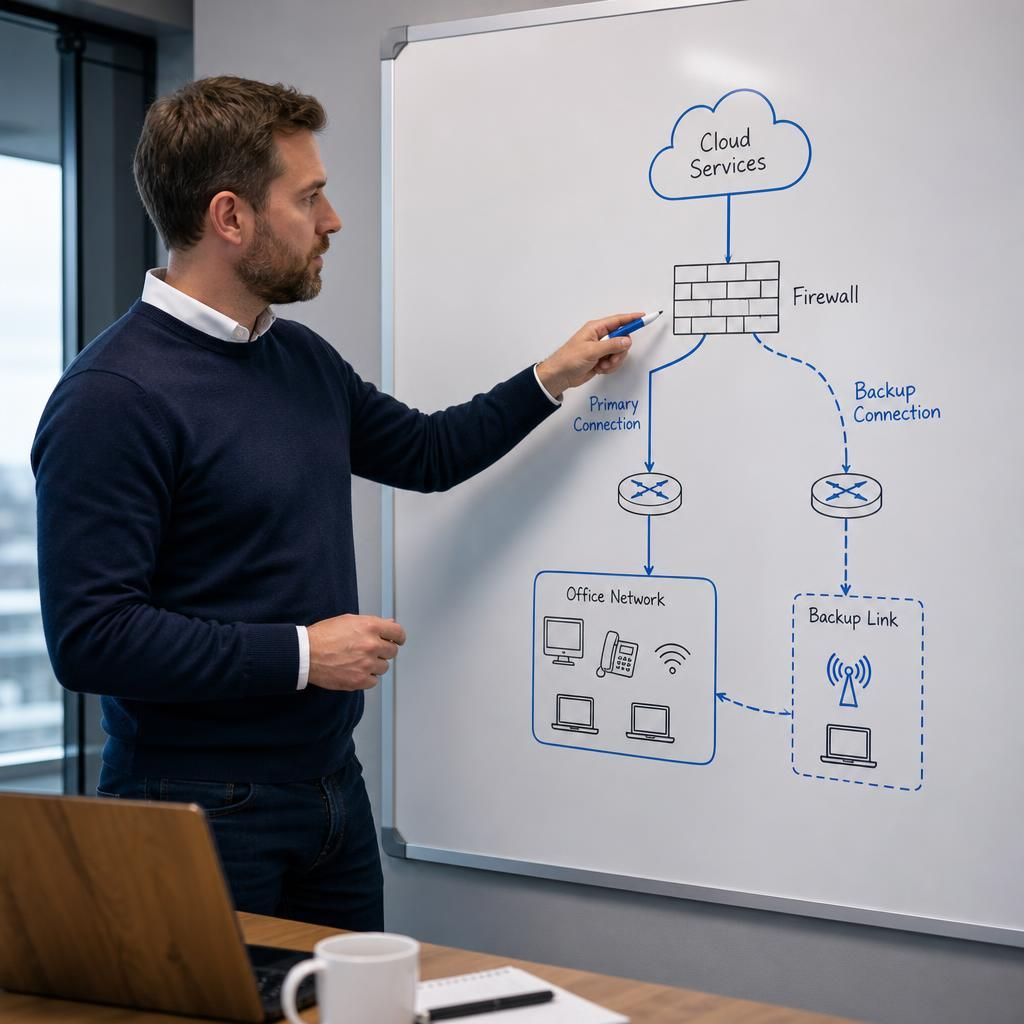
Network resilience should be tested by identifying critical services, simulating realistic failures and verifying that traffic, users and essential operations move to an alternative connection or system as intended. Tests should also check security controls, monitoring, recovery procedures and performance before, during and after failover.
Network resilience testing is a controlled assessment of whether network architecture, operating procedures and dependent services continue to function when a connection, device, power source, route or supporting system is impaired. A useful test produces evidence about continuity, degradation, restoration and the risks introduced while the network is operating in an abnormal state.
1. Define the scope and success criteria
Begin by documenting what the test is intended to prove. The scope might cover an entire office network, a site-to-site connection, wireless access, remote access, internet connectivity, voice services, cloud applications or communications between different locations. Avoid treating the network as a single service: resilience may be adequate for email but inadequate for access to a file server, a production system or an authentication service.
For each service, record measurable acceptance criteria before testing begins. These may include:
- which users or systems must remain usable;
- which functions may be temporarily unavailable;
- how much performance degradation is acceptable;
- which manual workarounds are permitted;
- how data integrity will be checked; and
- what conditions indicate that the test must be stopped.
Criteria should reflect business priorities rather than simply showing that a secondary link or device is present. A technically successful failover is not sufficient if users cannot authenticate, applications cannot reach their databases or important transactions cannot be completed.
2. Establish a known baseline
Capture the normal state before introducing a fault. Useful baseline information includes connection status, routing paths, latency, packet loss, throughput, firewall sessions, wireless coverage, server reachability, authentication and application performance. Record which alerts are normally generated and which monitoring tools are expected to show the change.
This baseline provides a comparison for the recovery test. It also helps distinguish a resilience problem from an existing capacity, configuration or application issue. The baseline should include the normal configuration of redundant equipment, routing preferences, access rules and automatic recovery settings, with suitable configuration backups retained.
3. Test realistic failure scenarios
A resilient design should be tested against the types of disruption it is intended to handle, not just a convenient equipment shutdown. Scenarios can include:
- loss of the primary internet circuit;
- failure of a network switch, router, firewall or wireless controller;
- interruption to a power supply or network cabinet;
- loss of a site-to-site connection;
- failure of a dynamic routing path;
- DNS or DHCP unavailability;
- loss of an authentication or directory service;
- high packet loss, excessive latency or an unstable circuit; and
- incorrect or malicious changes to routing, access or firewall configuration.
Where possible, test both complete failure and degraded operation. A link that is fully disconnected may trigger a clean failover, whereas a damaged circuit that remains intermittently available can cause unstable routing, repeated session drops or inconsistent user access.
4. Use controlled and safe test methods
Tests should be authorised, documented and scheduled around the risks of the environment. A change record should state the affected systems, test steps, responsible person, expected result, rollback action and communication arrangements. Take current configuration backups and confirm that administrative access remains available through an independent path where practical.
Start with the least disruptive method that provides meaningful evidence. This may involve disabling a specific route, isolating a test device, applying a controlled link impairment or using a representative test segment. Avoid disconnecting critical infrastructure without confirming the effect on users, safety systems, manufacturing equipment and other connected services.
Each test needs a clear abort condition. Unexpected effects such as widespread authentication failure, unsafe machine behaviour, uncontrolled traffic loops or loss of management access should trigger rollback rather than an attempt to continue for the sake of completing the exercise.
5. Check technical behaviour during the fault
Observe the network from more than one viewpoint. Infrastructure logs and monitoring show what the equipment believes is happening, while user devices and application tests show the practical effect. Check whether:
- the intended route or connection becomes active;
- traffic avoids the failed component rather than circulating through it;
- firewall, NAT and access-control policies still apply correctly;
- DNS, DHCP and authentication remain available or use an approved alternative;
- existing sessions behave as expected;
- new connections can be established;
- bandwidth and latency remain suitable for priority services; and
- alerts identify the fault without creating an unmanageable volume of duplicate notifications.
Record the difference between automatic and manual actions. Automatic routing changes may preserve connectivity but still require a person to restart a service, alter a policy or redirect users. That distinction belongs in the recovery procedure.
6. Validate the business services that depend on the network
Infrastructure status alone does not demonstrate resilience. Use representative transactions to confirm that important services remain useful. Depending on the organisation, this may involve signing in, opening a cloud application, accessing a shared resource, processing a test order, connecting to another site or making a test call.
Tests should include different user groups and locations where the design supports them. A local user may have access while a remote worker, branch office or wireless device is unable to reach the same service. Record the user-visible symptoms, not just technical metrics, including prompts to sign in again, interrupted sessions, slow responses or functions that become read-only.
7. Include security and access-control checks
Failover must not create a less secure route. Confirm that alternative connections use the intended encryption, authentication, filtering and logging. Check that access permissions do not broaden when traffic takes a secondary path and that remote access remains limited to authorised users and devices.
Also test how monitoring, security alerts and audit records behave during the event. A resilient network that continues operating but stops recording relevant activity may create a security blind spot. Configuration changes made for the test should be removed or formally retained only when they have been reviewed and approved.
8. Test restoration and return to normal operation
Recovery is not complete when an alternative path becomes available. Restore the original condition in a controlled way and confirm whether traffic returns to the preferred route without unnecessary interruption. Check for stale routes, duplicate addresses, abandoned sessions, partial configuration changes and services that require manual intervention.
Repeat the business-service checks after restoration. Some faults appear only during the transition back, particularly where stateful firewalls, cached DNS information or application sessions are involved. Confirm that monitoring has returned to its normal state and that the original fault is not masked by the temporary configuration.
9. Record findings and improve the design
Document the scenario, date, scope, observed behaviour, user impact, timings recorded by the monitoring systems, manual actions, failed expectations and rollback results. Classify findings according to their cause, such as insufficient capacity, incorrect configuration, missing dependency, weak monitoring or an unclear procedure.
Turn each material finding into an owned action with a defined priority and review point. Retest after changes rather than assuming that a configuration update has solved the underlying issue. Network resilience should also be reassessed when there are major changes to sites, circuits, cloud services, applications, security controls or the organisation’s operating model.
How often should testing take place?
There is no universal testing interval. The appropriate frequency depends on the network’s complexity, the effect of disruption, the rate of change and the organisation’s recovery requirements. Test after significant infrastructure or application changes, following a serious incident, and as part of a planned operational programme. Smaller organisations can still apply the same principles by prioritising the connections, services and dependencies whose failure would have the greatest effect.
For organisations reviewing network resilience, the most valuable evidence is not a statement that redundancy exists. It is a current record showing how the network behaves under relevant faults, which services remain usable, which controls protect the alternative path and what people must do when automatic recovery is incomplete.
Network resilience testing should be staged so that individual failover mechanisms are verified before several dependencies are tested together. A backup connection may work correctly in isolation but fail when routing, authentication, security filtering and application traffic change at the same time.
A practical sequence is:
- Component test: verify that the alternative circuit, device, route or power source can assume its intended role.
- Service test: confirm that a defined business service continues to operate through that alternative arrangement.
- Dependency test: introduce a related failure, such as loss of name resolution or authentication, and check whether the service degrades in the expected way.
- Integrated test: combine relevant conditions to represent a realistic incident, while retaining a safe rollback point.
This staged approach makes it easier to identify the actual source of a failure. It also prevents a successful component test from being mistaken for proof that the complete network can support business operations during disruption.