
What evidence should an IT support provider provide during service reviews?
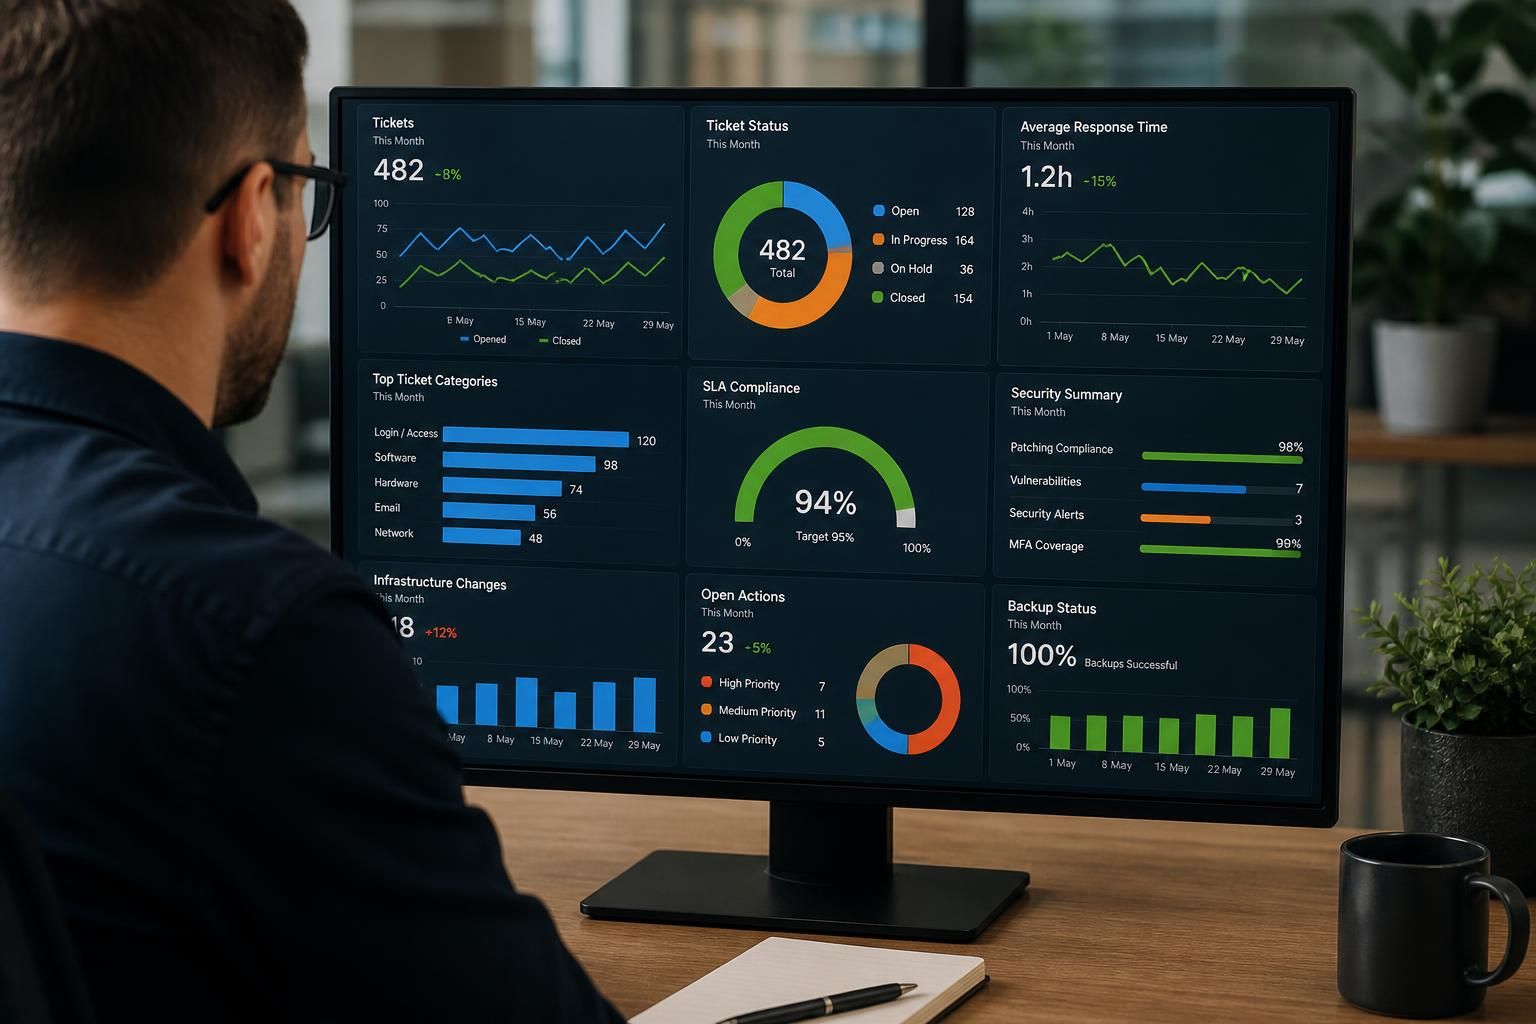
An IT support provider should provide a clear evidence pack covering service performance, ticket and incident trends, recurring faults, security updates, infrastructure changes and outstanding actions. The information should be accurate, understandable and linked to agreed service objectives, helping you assess risks, identify priorities and confirm whether recommendations have been completed.
An IT support provider should support its service review with verifiable records, clear measurements and documented decisions. The evidence should allow a business to compare actual service delivery with agreed expectations, understand the causes of problems and determine whether identified risks have been controlled.
Service-level evidence should show how the provider has performed against the measures defined in the contract or service description. This may include incident acknowledgement and resolution data, request completion, priority handling, escalation history and any excluded or delayed cases. Each measure should state its definition, reporting period and source. Without those details, a headline figure can be difficult to interpret; for example, a provider may measure elapsed time differently depending on whether time spent waiting for the customer is included.
The report should distinguish between the number of events and the effect those events had on the organisation. A high volume of low-impact requests may require a different response from a small number of incidents that prevented staff from accessing essential systems. Where possible, the provider should explain material exceptions rather than presenting an unexplained summary.
Ticket and incident records should contain enough information to test the reliability of the reporting. Useful supporting detail includes:
- the date and category of each case;
- the affected service, site or user group;
- the assigned priority and the reason for it;
- the actions taken, including escalations to other teams;
- the point at which service was restored or the request was completed;
- any customer dependency, supplier dependency or known constraint; and
- the final resolution or closure notes.
A review should not rely solely on closed-ticket counts. Sample cases can be examined to confirm that closure notes describe the actual remedy, that users were not asked to reopen a new ticket for the same issue and that temporary workarounds have not been recorded as permanent fixes.
Evidence of root-cause work is important when an incident has repeated or materially disrupted operations. A useful analysis records the timeline, technical cause, contributing conditions, immediate containment and corrective action. It should also identify who owns the action, what completion looks like and how the provider will confirm that the fault has not returned. If the cause remains uncertain, the report should say so and record the investigation still required rather than presenting an assumption as a finding.
Security evidence should demonstrate the operation of relevant controls, not merely state that security has been considered. Depending on the systems in scope, this can include patching status, vulnerability findings, endpoint protection coverage, privileged-access reviews, multi-factor authentication coverage, security alert handling and staff security training records. Sensitive technical information should be shared in an appropriate format, with restricted details separated from the main management report where necessary.
Backup evidence should cover more than whether a backup job was marked as successful. The review should show which systems and data are included, whether jobs have failed, how failures were handled and when restoration has been tested. It should also identify retention arrangements, dependencies and any systems that remain outside the backup scope. A successful restore test provides stronger evidence than a log showing that data was copied without error.
Change and configuration records should connect infrastructure changes to an approved request, business reason and implementation result. For significant changes, the evidence may include the risk assessment, approval, test result, implementation date, rollback approach and post-change checks. Configuration baselines, network diagrams and asset records should be updated when the environment changes. This helps establish whether the provider’s documentation reflects the systems that are actually being supported.
Asset and licence information can reveal risks that are not visible in incident statistics. A review may include the status and age of devices, operating system versions, warranty position, software licensing, unsupported technology and equipment approaching replacement. The useful question is not simply how many assets exist, but whether each important asset has an owner, a support position and a documented next step.
Action tracking should use a register rather than a narrative list. Each action should have:
- a precise description of the required outcome;
- a named owner;
- a priority based on business risk;
- a target date agreed with the business;
- the dependency or decision preventing progress, if applicable; and
- evidence confirming completion.
Completed actions should not be closed only because a recommendation was issued. The provider should identify the implementation record, test result, updated document or other artefact that demonstrates completion. If the business has chosen to accept a risk, that decision should be recorded with the relevant approver and reviewed when circumstances change.
Good evidence is traceable and consistent. Figures in the management summary should reconcile with the underlying ticketing, monitoring, security or asset systems. Definitions should remain consistent from one review to the next, or any change should be explained. Reports should also separate provider-controlled issues from customer decisions, third-party failures and known limitations in the available data.
Before a service review, the customer can ask the provider to supply the report in advance, identify the data sources used, explain exceptions and highlight decisions that require approval. During the meeting, focus on trends, risk, repeated causes and unresolved dependencies rather than reading every entry. The outcome should be a written record of agreed priorities, owners and next steps, giving both parties a reliable reference for the following review.
Service review evidence should be capable of independent challenge, rather than relying solely on the provider’s interpretation. For each significant conclusion, the review should identify the underlying record, the period covered, the systems or services included and any limitations affecting the finding.
A practical review can test a sample of reported results against source information, such as ticket records, monitoring data, change approvals or security logs. Differences should be explained and corrected where necessary. This process is particularly useful when a summary presents an improvement, a recurring issue as resolved or a risk as controlled.
The provider should also distinguish verified facts from professional judgement and proposed actions. That distinction allows attendees to question assumptions, request further evidence and make informed decisions without treating an untested recommendation as an established result.