
How is connectivity resilience assessed across critical business services?
Connectivity resilience is assessed by identifying critical business services, mapping their dependence on networks and internet connections, and evaluating how they would continue during an outage. The assessment covers connection redundancy, failover arrangements, recovery priorities, and testing to confirm that alternative paths work as intended.
Connectivity resilience is assessed by measuring how well each critical business service can withstand the loss, degradation or isolation of a network connection. The assessment combines business impact analysis with technical review, so it considers not only whether an alternative connection exists, but whether staff can still use the required applications, data and communication channels when part of the connectivity environment fails.
The first step is to establish which services are genuinely critical. This normally involves discussions with business owners rather than relying solely on an IT asset list. A service may be considered critical when its interruption would prevent essential operations, create a regulatory issue, stop customer or supplier communication, or leave staff unable to perform key duties. Typical examples include cloud business applications, order processing, payment systems, production systems, telephony, online customer services and access to shared files.
Each service should then be assessed against specific business requirements, including:
- Maximum tolerable downtime: how long the service could be unavailable before the effect becomes unacceptable.
- Acceptable performance degradation: whether a service remains usable with slower response times, reduced capacity or limited features.
- Required locations and users: whether the service is needed at one site, across several sites, or by remote workers.
- Operating dependencies: the network, internet access, authentication, DNS, cloud platforms, security controls and devices required to use the service.
- Data and transaction requirements: whether interrupted transactions can be resumed safely and whether users need continuous access to current information.
This produces a service-level view of resilience rather than treating the whole network as one system. For example, a business may have a resilient internet connection but still be unable to use a cloud application because identity services, DNS resolution or a security gateway is unavailable. Conversely, an application may remain online while the organisation lacks sufficient connectivity capacity for all users to access it.
Dependency analysis examines every component between the user and the service. This can include internal switching and wireless infrastructure, routers, firewalls, authentication systems, domain name resolution, internet circuits, cloud security services, hosting platforms and third-party suppliers. Dependencies should be recorded in both directions: the systems a business service needs, and the business services that would be affected by the loss of a particular component.
The assessment should look specifically for common points of failure. These may include a single carrier, shared ducting, one building entry point, one firewall, one power source, a central authentication platform or a security service used by multiple locations. Two connections are not necessarily independent if they use the same provider infrastructure, physical route, termination equipment or upstream service. Resilience therefore depends on genuine separation and suitable operating design, not simply on the number of contracts or ports in place.
Capacity is assessed alongside availability. A secondary connection may keep a service technically reachable but lack the bandwidth needed for normal operations. The review should compare expected demand with the capacity available during an incident, including traffic from cloud applications, voice, backups, security monitoring and remote access. It should also consider whether business-critical traffic can be prioritised when capacity is reduced. A connection that supports normal use but becomes congested during failover may provide limited practical resilience.
Technical resilience is often recorded using measurable service requirements. These can include:
- acceptable latency, packet loss and jitter for interactive applications and voice;
- the minimum bandwidth required for essential users and services;
- the time allowed to detect and switch from a failed path;
- the time required for systems, routes and user access to stabilise;
- the level of functionality that must remain available during degraded operation; and
- the conditions under which a service can return to its normal configuration.
These measures should be agreed with service owners. Network metrics alone do not show whether the business can operate. A connection can report as available while users cannot authenticate, a hosted application cannot be reached, voice quality is unacceptable, or transactions cannot be completed. Resilience assessment should therefore combine infrastructure monitoring with application checks and reports from the teams that use the services.
Failover design also needs operational assessment. This includes confirming who is authorised to make changes, how an incident is identified, what information is recorded, and how users are told to work during degraded service. Manual procedures may be appropriate for some systems, while others need automated route selection or application-level recovery. The assessment should identify any steps that depend on the failed connection itself, such as accessing cloud management portals, contacting an external support service or retrieving configuration information.
Testing provides evidence that the documented design reflects actual behaviour. A useful test does more than disconnect a cable: it verifies user access to priority applications, name resolution, authentication, telephony, security inspection, site-to-site traffic and any required remote connections. Results should record the observed interruption, performance during the test, services that failed unexpectedly and actions needed to improve the design. Tests should be controlled to avoid unnecessary disruption and repeated when major network, application or supplier changes occur.
Resilience should also be assessed over the full supplier chain. Contractual and service information can show whether providers offer defined fault reporting, maintenance notifications, service credits, escalation routes and technical details about connection diversity. These provisions do not replace technical independence, but they help an organisation understand how an incident will be managed and whether the service is suitable for its stated business requirements.
The final output is usually a resilience register or report. It should link each critical service to its dependencies, risks, required capacity, recovery approach, test evidence and outstanding actions. Risks can then be prioritised according to business impact rather than technical convenience. An organisation might choose to remove a single point of failure, increase capacity, change a dependency, improve monitoring, document a manual process or accept a risk formally where the cost of further resilience is not justified.
Because connectivity environments change, the assessment should be revisited after new sites, cloud services, security platforms, applications or working arrangements are introduced. Regular review ensures that resilience remains aligned with the services the business actually depends on, rather than the infrastructure that existed when the original design was created.
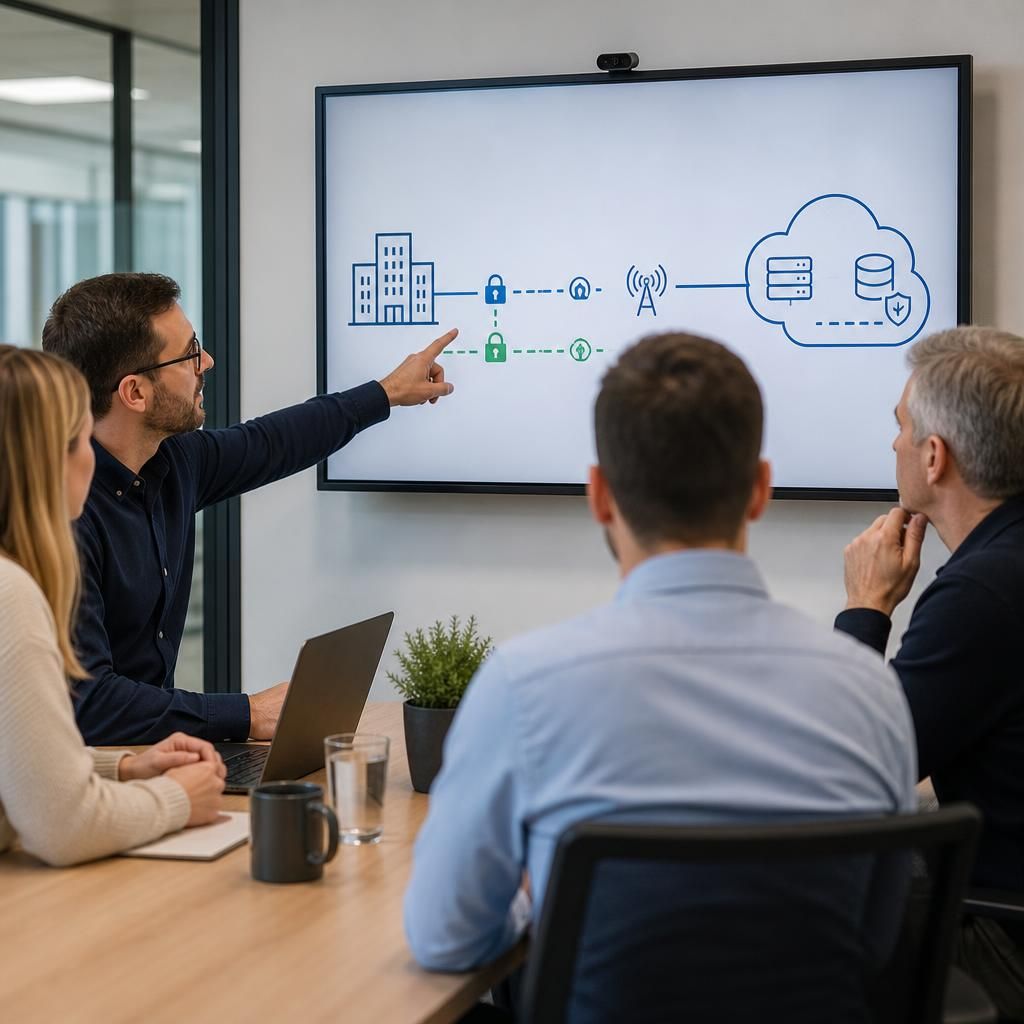
Connectivity resilience should also be assessed against security-related disruption, not only accidental circuit failures. A cyber incident may require a business to isolate a site, disable remote access, block specific services or restrict communication between systems. The assessment should establish which critical functions can continue under those controls without weakening containment measures.
This involves documenting secure administrative access, approved isolation procedures, alternative communication methods and the conditions for restoring connectivity. It should also identify whether essential services depend on the same identity, security or management systems that might be restricted during an incident. Treating cyber isolation as a resilience scenario gives the business a clearer view of how to maintain essential operations while protecting affected systems.