How are business-critical systems prioritised during cyber incident response?
During cyber incident response, business-critical systems are prioritised according to their impact on essential operations, customer services, safety, legal or regulatory obligations, and dependencies on other systems. Response teams typically contain the threat first, then restore the services that enable the most important business functions while preserving evidence and addressing security weaknesses before full reconnection.
Business-critical systems are prioritised by the consequences of their loss, the order in which services can be safely recovered, and the information needed to make sound decisions during the incident. A practical response process combines pre-agreed business priorities with current technical evidence, because an apparently important application may be unusable until its identity, network, database or authentication dependencies have also been restored.
Start with business services rather than individual devices. The first task is to identify the activities the organisation must continue or reinstate, such as processing orders, delivering client work, managing production, communicating with customers or meeting financial obligations. Systems are then mapped to those activities. This avoids giving every server or application the same priority and helps the response team focus on the services that support the organisation’s most significant operations.
Use defined priority tiers. Many organisations classify services into tiers such as critical, high, medium and low. A critical service may be one whose prolonged loss would stop a core operation or create serious contractual, safety or compliance consequences. High-priority services may support important work but have a viable manual workaround. Lower tiers can include systems that are useful but do not prevent essential activity from continuing. The labels matter less than having clear definitions that managers, technical staff and third-party providers interpret consistently.
Each service record should include its owner, users, supporting applications, data stores, authentication requirements, network connections and external providers. It should also record acceptable data loss and recovery expectations agreed with the business. These details turn a general priority list into a recovery sequence and reveal where restoring one service depends on another that might initially appear less important.
Assess the effect of the incident on each system. Priority can change according to what has actually happened. A system may be highly important but unsafe to reconnect because it shows signs of compromise, contains an active account takeover, or relies on a shared component that has not been trusted again. Conversely, a less prominent system may become urgent if it is needed to support investigation, communications, access control or the operation of a higher-priority service.
Incident teams therefore consider factors including:
- whether the system is still being used by an attacker;
- whether its data or configuration can be trusted;
- whether restoring it could spread malware or reintroduce unauthorised access;
- whether a clean backup or rebuild is available;
- whether dependent systems are ready to operate with it; and
- whether a temporary manual process can support the affected business activity.
Separate containment priorities from recovery priorities. The system that must be isolated first is not necessarily the system that should be restored first. For example, an exposed administrative account, remote access service or shared file location may require immediate restriction even if it is not a core business application. This distinction prevents the recovery process from reopening the route used in the incident or allowing an affected system to compromise clean systems.
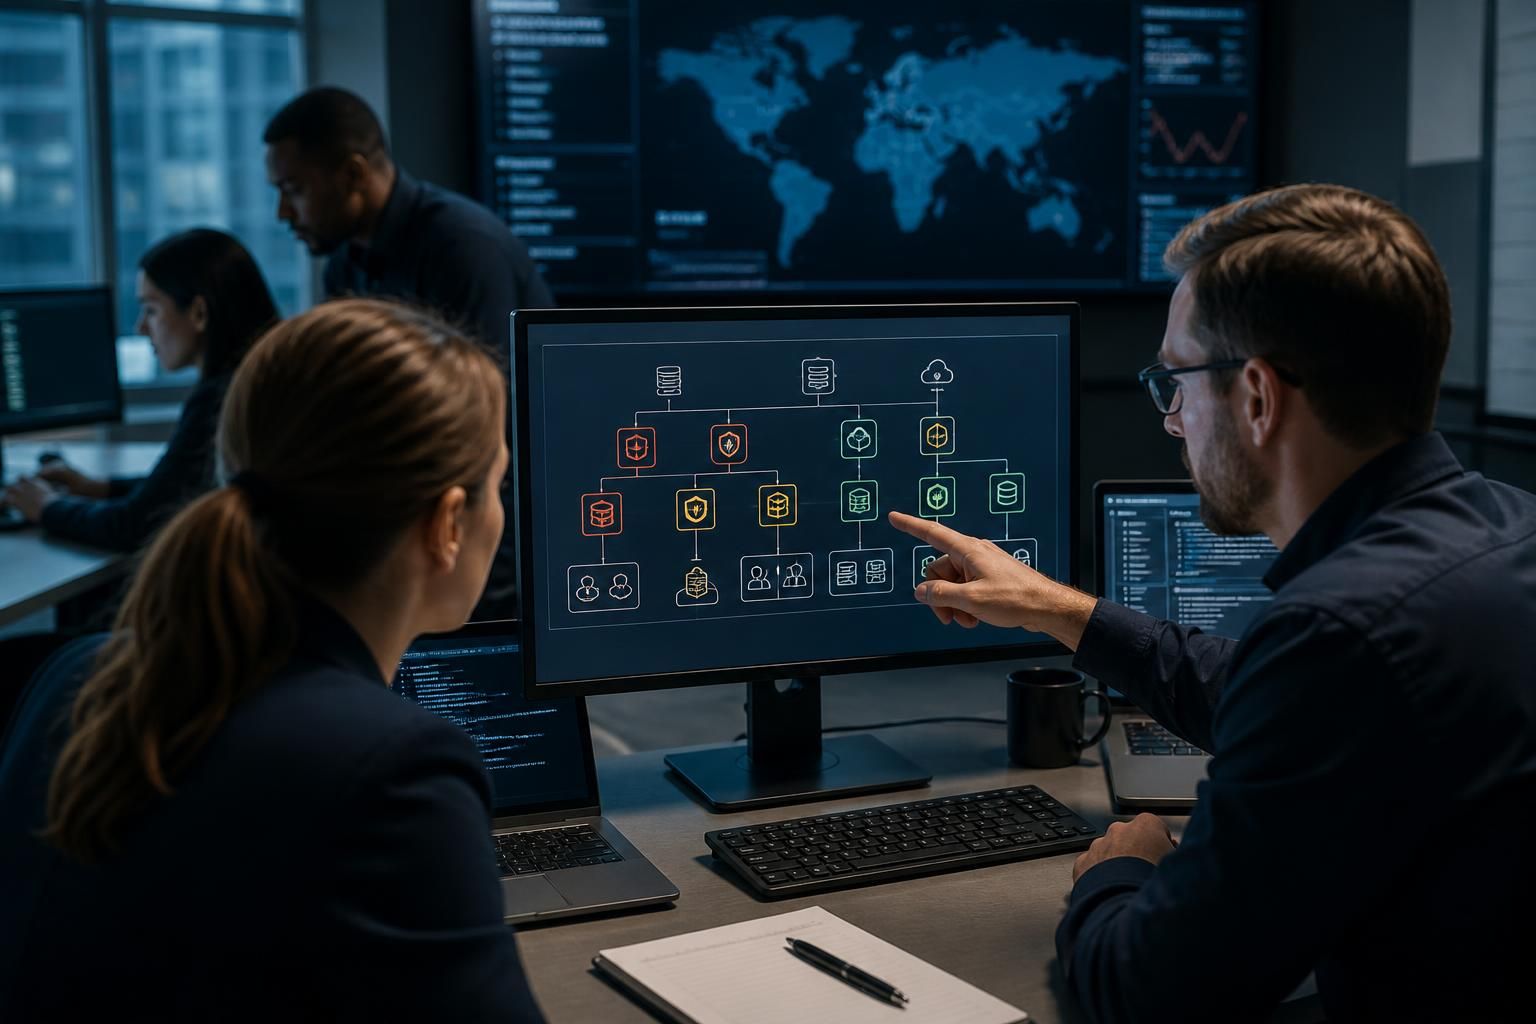
Restore in dependency order. Recovery usually begins with the foundations required by other services. These may include network segmentation, identity services, access controls, security monitoring, name resolution, storage and backup infrastructure. Business applications can then be brought back in a controlled sequence. Attempting to restore a visible customer-facing application before its supporting authentication or database services are secure can create further outages and obscure whether the application itself has been cleaned.
Recovery decisions should also account for data integrity. A recent backup is not automatically a safe backup: it may contain encrypted files, malicious changes or compromised credentials. Teams assess backup provenance, signs of tampering, restoration results and the point at which the recovered data can be reconciled with transactions recorded elsewhere. Where complete restoration is not yet possible, a limited service using verified data may be preferable to reconnecting the full environment.
Apply business-approved exceptions carefully. A senior business owner may decide that a lower-tier system should be restored early because it enables a temporary workaround, supports a contractual commitment or provides information needed for another priority. Such decisions should be recorded with the reason, risks, owner and review point. This creates an auditable basis for changing the sequence rather than allowing pressure during the incident to override security controls without consideration.
Prioritisation also governs communications and decision-making. System owners should know which services are affected, what users can safely do, which workarounds are authorised and what information must not be entered into an untrusted system. Technical teams need a single, current view of restoration status, dependencies, known risks and outstanding validation tasks. This reduces conflicting instructions and helps management understand the operational effect of each technical choice.
Validate each recovery stage before moving on. Technical availability is not the same as business readiness. After a system is restored, teams should check access permissions, critical workflows, integrations, data accuracy, logging, security controls and the absence of indicators that the compromise remains. The relevant service owner should confirm that the system performs the required function before it is returned to normal use. If validation fails, the system should move back into investigation or remediation rather than being treated as recovered.
The priority model should be prepared before an incident through business impact analysis, dependency mapping, backup testing and exercises involving both technical and operational staff. It should then be reviewed after major technology, supplier, premises or organisational changes. Lessons from the incident can reveal that a supposedly secondary service was essential, that a dependency was undocumented, or that a manual workaround was impractical.
For small and medium-sized organisations, a concise service catalogue with named owners, recovery dependencies, backup locations and agreed restoration criteria can provide a usable foundation. Managed IT and cyber security specialists can help document these relationships, test recovery assumptions and apply the prioritisation process during an investigation without treating every system as equally safe to reconnect.
Prioritisation during a cyber incident should reflect confidence in the available information as well as the apparent importance of each system. Early in an investigation, teams may not know whether an application, account or dependency has been affected. Treating an uncertain system as safe simply because it supports a critical function can create further compromise.
A practical approach is to give each proposed recovery action a confidence level and a clear condition for review. For example, a service may be considered operationally urgent but unsuitable for reconnection until its administrator accounts, logs and supporting infrastructure have been examined. This separates the business need to restore the service from the security evidence required to justify doing so.
Incident leaders should record the assumptions behind each priority decision, the evidence available at the time and the event that would cause the decision to change. This creates a defensible rationale when information develops quickly and helps different teams make consistent choices. Priorities can then be revised as investigation findings, user reports and restoration tests provide a clearer picture of the affected environment.