
What happens if an offsite backup job fails?
If an offsite backup job fails, the intended copy of new or changed data is not transferred, creating a gap in the recovery point and potentially leaving recent files unavailable if the primary system is lost. The failure should be investigated from the backup logs, corrected and rerun, with the resulting backup verified before it is treated as reliable.
An offsite backup job failure means the backup system has not completed the planned transfer or has not produced a usable copy at the destination. The correct response is to establish what data is affected, contain any continuing failure, restore protection through a successful replacement job, and confirm that the retained copy can actually be recovered.
What a failure may mean
Not every alert has the same significance. A job may fail before reading any data, stop part-way through a transfer, complete the transfer but fail during verification, or report success while excluding files because of permissions, configuration rules or connectivity problems. A warning can therefore be as important as a hard failure if it shows that particular systems, folders or databases were omitted.
The effect depends on the backup design. A failed full backup may affect the ability to restore an entire system, while a failed incremental or differential job may make later recovery points unusable because they depend on an earlier copy. A failure affecting only one endpoint has a narrower scope than a failure affecting the backup server, repository, network route or shared credentials.
Common causes of failure
- Loss of connectivity between the production environment and the offsite repository.
- Expired credentials, changed permissions or an account that has been disabled.
- Insufficient capacity at the destination or local storage used to stage backup data.
- Corrupted source files, database errors or problems with the backup agent.
- Incorrect schedules, retention rules, exclusions or recently changed system configurations.
- Encryption, certificate or key-management errors that prevent processing or access to the backup.
- Resource contention, such as heavy production workloads, locked files or an overloaded backup server.
- Security controls blocking the transfer or identifying the backup traffic as suspicious.
Recurring failures should not be treated as isolated technical incidents. They may indicate that the backup design no longer reflects the organisation’s systems, that monitoring is incomplete, or that a dependency has changed without the backup configuration being updated.
What should happen immediately?
- Confirm the alert. Check the job status, affected workload, time of failure and whether the message relates to the entire job or only selected items. Correlate the alert with repository activity and system changes rather than relying on a notification alone.
- Define the exposure. Identify the last known usable recovery point for each affected system and determine which files, applications or transactions may not be represented. Record whether the issue affects one device, one site or the wider backup service.
- Protect the source data. Avoid deleting, overwriting or reconfiguring the only available copies while troubleshooting. If a system is suspected of compromise, preserve relevant evidence and follow the organisation’s incident response process before making changes.
- Resolve the underlying fault. Correct the specific cause, such as restoring connectivity, renewing an authorised credential, freeing capacity or repairing a backup agent. Repeating a job without addressing the cause can create repeated failures or incomplete copies.
- Run the appropriate recovery job. Depending on the backup method, this may require a retry, a new full backup or a new baseline followed by incremental backups. The sequence must leave a coherent chain of recovery points.
- Validate the result. Check that the destination contains the expected systems and data, that the backup is readable, and that its encryption and retention settings are intact. A successful transfer message alone does not prove that the organisation can restore what it needs.
How to assess the business risk
Risk is determined by more than the existence of a recent backup. Consider the age of the last verified recovery point, the importance of the affected system, the volume of changed data, the availability of alternative copies and the time required to rebuild the service. A failed backup for a non-critical archive is different from a failed backup for a database that supports daily operations.
Compare the identified recovery point with the system’s recovery point objective. If the available copy is older than the permitted data-loss window, the business is outside its intended protection level until a suitable copy is created. Also consider the recovery time objective: a backup may exist, but restoring it may take too long if the required credentials, application installers, configuration files or recovery procedures are missing.
When a restore is needed
If data has been lost or a system is unavailable, do not assume that the newest backup is automatically the best choice. Select a recovery point that is both usable and appropriate to the incident. For example, a copy created after corruption or ransomware activity may preserve the problem, whereas an earlier clean copy may be safer.
Where practical, restore to an isolated test location first. Check file integrity, application behaviour, database consistency, user access and dependencies such as identity services or network shares. For a major outage, prioritise systems according to business impact and documented recovery procedures rather than restoring in an arbitrary order.
How to prevent repeat failures
- Monitor job outcomes, warnings, exclusions, repository capacity and the age of the last usable recovery point.
- Send alerts to an owned process, with clear responsibility for investigating and closing them.
- Review backup scope whenever applications, devices, offices or cloud services are added or retired.
- Use separate administrative access and protect backup infrastructure from unauthorised alteration.
- Test file, application and full-system restores at a frequency appropriate to the business risk.
- Document dependencies, recovery priorities, encryption-key access and the steps required to rebuild the backup service.
- Review repeated failures for trends rather than simply clearing each individual alert.
A useful backup review should therefore ask three separate questions: did the job run, did it capture the intended data, and can the organisation recover that data in a practical way? Monitoring, documented ownership and restore testing are needed to answer all three. Managed IT support can help businesses around Stourbridge and neighbouring areas turn those checks into a consistent process, while keeping the backup arrangement aligned with their systems and recovery requirements.
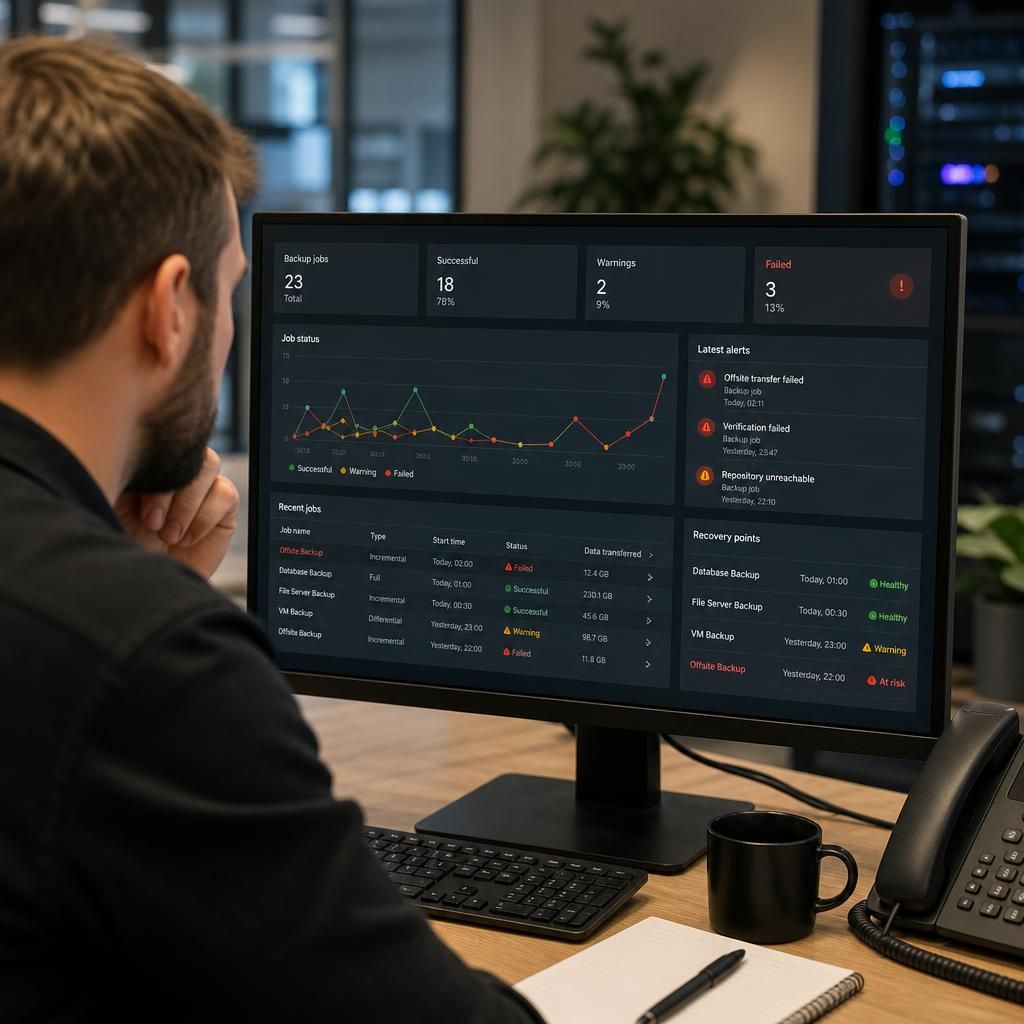
An offsite backup job should remain a protection exception until a later, usable recovery point has been created and the affected backup chain has been confirmed. Clearing the alert or seeing a successful retry does not necessarily remove the original exposure, particularly where the failed job depended on earlier incremental data.
Record the exception against the affected workload, including the last recovery point that has been tested, the data created since then and any temporary protection being used. This gives technical and business stakeholders a clear view of what could be recovered if the source system failed before the backup arrangement was fully restored.
Once the fault has been corrected, compare the new recovery point with the organisation’s recovery requirements and retain evidence of the checks performed. This creates an auditable distinction between an alert that has been acknowledged and a backup failure that has genuinely been resolved.
Review Your Offsite Backup Protection
Ask S2 Technology Group to review your offsite backup monitoring, recovery-point records and restore evidence, then identify any unresolved protection gaps. This provides a practical basis for strengthening backup arrangements before a failed job becomes a wider business interruption.