
How do virtual IT solutions support disaster recovery?
Virtual IT solutions support disaster recovery by hosting systems in managed environments, protecting data with resilient backups and enabling authorised users to access essential applications from an alternative location. Recovery plans can also define how systems are restored, prioritised and tested, helping businesses resume critical operations after hardware failure, cyber incidents or site disruption.
Virtual IT solutions support disaster recovery by making the recovery of applications, data, user access and infrastructure a coordinated process rather than a rebuild of one physical office. Systems can be designed with documented dependencies, recoverable configurations and alternative hosting arrangements, reducing reliance on equipment at the affected premises.
A useful disaster recovery design starts by identifying which services the organisation must restore first. Core identity services, line-of-business applications, file access, communications and security controls may have different priorities. Documenting these relationships helps prevent a recovered application from being unusable because its database, authentication service or network connection has not also been restored.
Recovery objectives provide a practical basis for planning. The recovery time objective defines how long a service can remain unavailable before its disruption becomes unacceptable. The recovery point objective defines how much recent data the organisation can afford to lose. These objectives should be set for individual workloads rather than applied uniformly, because a financial system, shared document store and non-essential archive may have different operational requirements.
Virtual environments can support these objectives through several technical controls:
- Replicated workloads: Virtual machines and application components can be copied to a separate infrastructure location, allowing a prepared system to be brought online without rebuilding every element manually.
- Point-in-time recovery: Multiple recovery points can help restore data to a state before corruption, accidental deletion or a malicious change was introduced.
- Separated backup copies: Keeping backup data logically or physically separate from production systems reduces the risk that one compromised administrator account or security incident affects both.
- Configuration capture: Virtual machine settings, network rules and application dependencies can be documented or retained as recoverable configuration, making the recovery process more repeatable.
- Access control: Recovery environments should use named accounts, strong authentication and restricted administrative permissions so that emergency access does not create an avoidable security weakness.
Backup alone is not a complete recovery strategy. A backup may be intact but still unusable if encryption keys are unavailable, applications are licensed to a failed server, databases were not captured consistently, or users cannot authenticate. A sound plan therefore records the credentials, licences, certificates, integrations and configuration details needed to re-establish the service. It should also identify who can approve recovery actions and who is responsible for communicating the status of each system.
Cyber incidents require particular care. Restoring an infected system can reintroduce the original threat, so recovery procedures may include isolating affected workloads, checking backup points for signs of compromise, rebuilding clean systems and reviewing privileged access before reconnecting users. Security monitoring, endpoint protection and firewall policies should remain part of the recovery design rather than being treated as optional additions after systems are restored.
Connectivity is another important dependency. Users may be unable to reach recovered applications if the primary site, internet connection, virtual private network or name-resolution service is unavailable. Disaster recovery planning should therefore consider alternative routes to essential services, remote access controls and the order in which network and identity components are brought back. Access should be limited to the people and devices that need it, particularly while normal security boundaries are being re-established.
Testing shows whether documented procedures work in practice. A useful test can begin with a review of recovery documentation and progress to restoring selected files, starting a complete workload in an isolated environment, or simulating the loss of a site. The test should record the actual restoration steps, dependencies, access problems and data gaps. Findings then need to be converted into changes to the design or procedure; a test that produces no review or update provides limited assurance.
Disaster recovery should also be reviewed when the virtual environment changes. New applications, altered retention rules, staff changes, migrations and changes to network architecture can make an old recovery plan inaccurate. Regular reviews should confirm that critical workloads are included, recovery priorities remain appropriate, backup copies can be accessed, and responsible personnel understand their roles.
For a small or medium-sized organisation without a full in-house IT team, a managed IT provider can help map dependencies, assess recovery requirements, configure virtual infrastructure and coordinate testing. The important measure is not simply whether systems are virtualised, but whether the organisation can restore the right services, with trustworthy data and controlled access, in a defined order after a disruptive event.
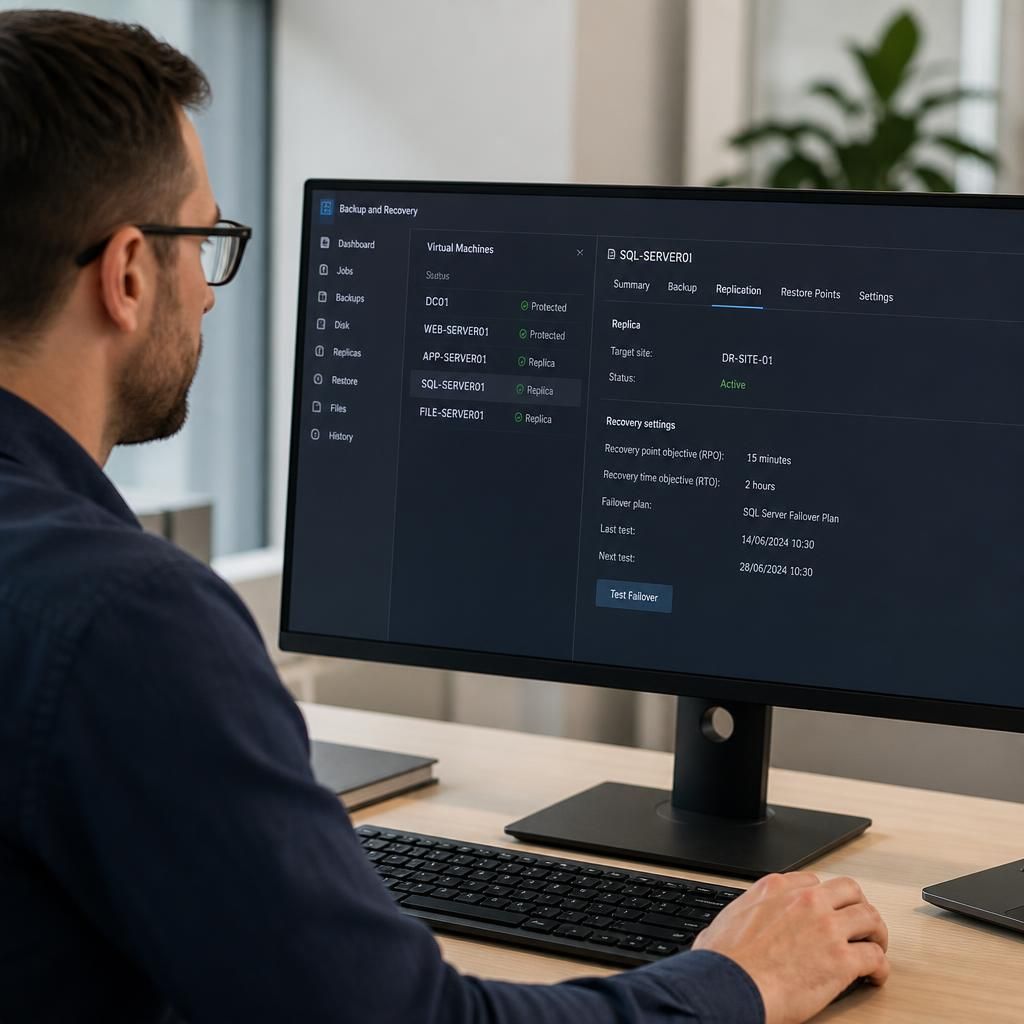
Virtual IT solutions support disaster recovery more effectively when backups preserve application consistency, not just individual files or virtual machine snapshots. An application-consistent recovery point captures related data in a usable state, reducing the risk that a restored system contains incomplete transactions or mismatched database records.
This is particularly important for systems that write to several files or databases at the same time. Recovery procedures may need to coordinate database transactions, application services and supporting data before creating a recovery point. Transaction logs can also help bring a database to a known state, provided they are protected and retained in line with the organisation’s recovery requirements.
When assessing a virtual disaster recovery design, businesses should ask whether each critical application has an appropriate recovery method, how data consistency is verified, and whether the restored system can be checked before users reconnect. These controls help distinguish a technically available backup from a recovery point that the business can actually use.