How does IT service management support problem management?
IT service management supports problem management by identifying the underlying causes of incidents, analysing recurring faults and coordinating permanent corrective actions. This reduces repeat disruptions, improves service reliability and helps organisations address risks before they affect critical operations.
IT service management supports problem management by providing the structure, information and governance needed to investigate the causes of service issues and control the work that follows. It connects incident records, technical analysis, change control, knowledge management and service reporting so that problem work is treated as a managed operational process rather than an isolated troubleshooting exercise.
Problem management is distinct from incident management. Incident management focuses on restoring a service or reducing the immediate effect on users. Problem management examines why incidents occurred, whether similar events share a common cause, and what action is appropriate to prevent, contain or better manage the underlying issue. A problem may therefore be opened after one serious incident, several related incidents, or the identification of a weakness before it has caused a disruption.
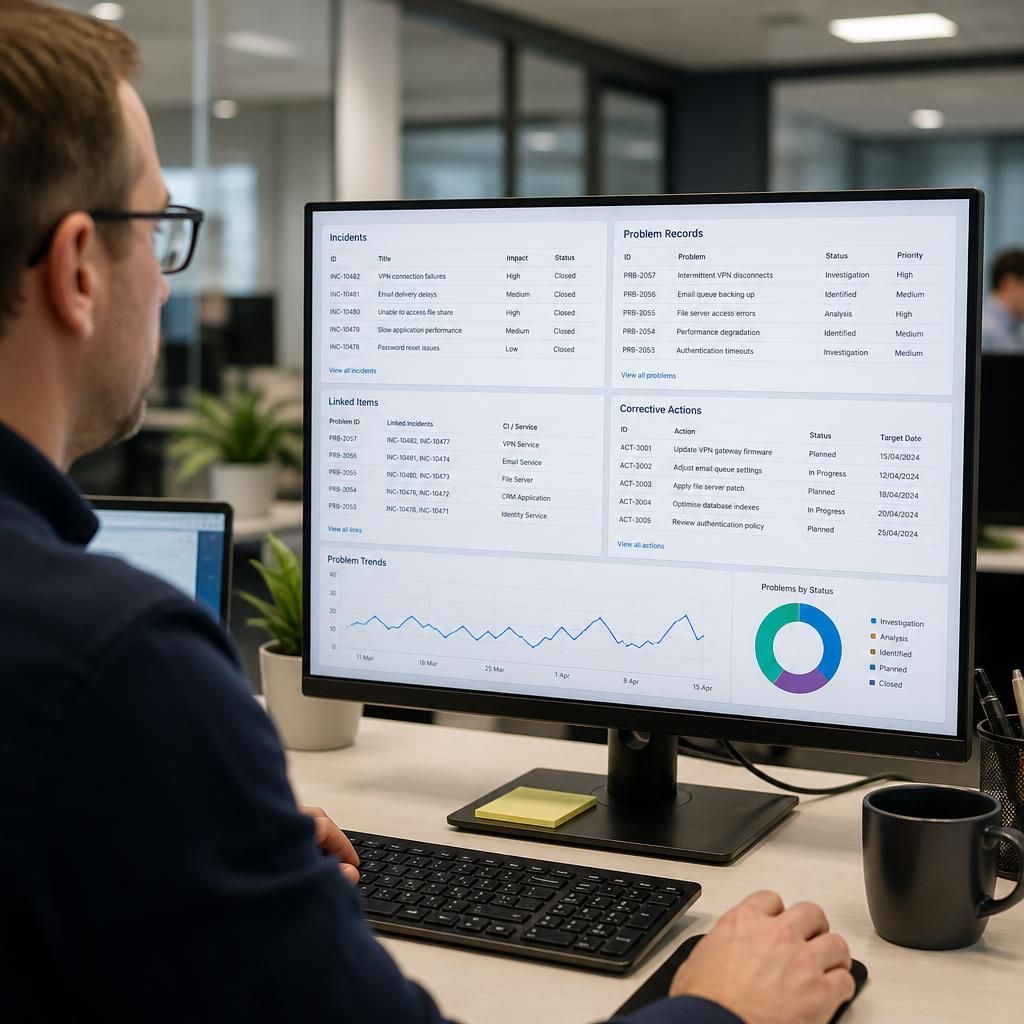
IT service management establishes a controlled problem lifecycle, which commonly includes:
- Detection: identifying potential problems through incident trends, monitoring information, technical alerts, security events, supplier reports or service reviews.
- Logging: recording the problem with a clear description, affected services, relevant configuration items, business impact and links to associated incidents.
- Assessment: evaluating the scope, urgency, risk and likely business consequences so investigation effort is directed appropriately.
- Investigation: applying structured analysis to test possible causes and distinguish evidence from assumptions.
- Resolution planning: defining corrective actions, owners, dependencies, resources and risks.
- Control and closure: confirming that agreed actions have been implemented, updating operational records and documenting any residual risk or workaround.
Accurate service records make this process more effective. An IT service management platform can link incidents to users, locations, devices, applications, suppliers, changes and service-level information. This allows analysts to identify patterns that may be missed when tickets are reviewed separately. Useful records include the time and nature of each event, error messages, affected components, recent changes, attempted fixes and the conditions under which the issue occurred.
Root-cause analysis should be proportionate to the problem. Simple techniques such as timeline analysis, fault-tree analysis and the “five whys” can help with straightforward technical failures. More complex issues may require evidence from multiple teams, dependency mapping, event correlation or controlled testing. The objective is not to assign blame; it is to establish a defensible explanation and choose an action that addresses the risk without introducing a greater one.
Problem management also provides a way to manage known errors. A known error is a problem that has been analysed sufficiently for its cause or characteristics to be understood, even if a permanent correction is not yet available. IT service management can record an approved workaround, the conditions in which it should be used, any limitations, and the criteria for escalation. This helps the service desk handle future incidents consistently while technical teams continue with further work.
Corrective action must connect with change management. A software update, configuration adjustment, hardware replacement, architecture change or security control may be needed to address a problem. IT service management ensures that the proposed change is assessed for impact, tested where appropriate, approved by the right authority, scheduled with relevant stakeholders and reviewed afterwards. This prevents an attempted fix from creating an additional service interruption or weakening security controls.
Problem management can contribute directly to cyber security and resilience. Repeated authentication failures, unusual account behaviour, exposed systems, incomplete patching or recurring endpoint alerts may indicate a control weakness rather than ordinary user support issues. Linking problem records with security investigations helps organisations assess whether the event is isolated, identify affected dependencies and assign remediation through an accountable process. The same discipline can be applied to single points of failure, capacity constraints and weaknesses in backup or recovery arrangements.
Governance keeps problem work visible and accountable. Regular reviews should consider open problems, ageing actions, unresolved workarounds, business services affected, ownership, technical dependencies and accepted risks. Reporting should focus on useful decisions rather than simply counting records. For example, management may need to know which services have the greatest exposure, which actions depend on a supplier, and whether a proposed correction requires investment or a planned change window.
For a small or growing organisation without a full in-house IT function, a managed IT services provider can apply these practices as part of its ongoing service management approach. The important outcome is a repeatable method for turning operational evidence into prioritised technical action, with decisions recorded clearly enough for service desk staff, engineers, managers and suppliers to work from the same information.
Problem management supports continual improvement by turning confirmed causes and recurring weaknesses into changes to the way services are designed, monitored and supported. Its value is not limited to correcting one technical fault; it also helps prevent the same class of issue from appearing elsewhere in the environment.
Findings from a problem investigation can lead to clearer service requirements, improved monitoring rules, revised support procedures, stronger recovery arrangements or additional technical safeguards. For example, if an investigation identifies an overlooked dependency, the organisation can update service documentation, include that dependency in future testing and ensure its failure is detected earlier.
This creates a feedback loop between day-to-day support and service improvement. Incident information highlights where users are being affected, problem management establishes what needs to change, and service owners can then confirm whether the improvement has reduced the original risk. The result is a more informed basis for planning infrastructure work and technology investment.