How does an IT helpdesk handle recurring technical issues?
An IT helpdesk handles recurring technical issues by reviewing ticket history, identifying patterns and investigating the underlying cause rather than repeatedly applying temporary fixes. It then implements a lasting solution, documents the resolution and monitors for further occurrences to reduce disruption and support a more reliable, secure IT environment.
An IT helpdesk handles recurring technical issues through a structured problem-management process. Instead of treating every occurrence as an isolated support request, it connects related incidents, establishes how the fault presents itself, assesses its business impact and controls the underlying risk. This allows the helpdesk to distinguish between a genuine recurring fault, separate issues with similar symptoms and a problem caused by user behaviour, configuration or an external dependency.
The process normally begins by defining what is recurring. Relevant details include which users or devices are affected, the applications or services involved, the circumstances in which the fault appears and whether the issue follows a consistent pattern. For example, repeated failures may be limited to one device configuration, a particular office, a specific user group or a process that depends on an unreliable connection. Clear definition prevents technicians from applying a broad change when the fault has a narrower cause.
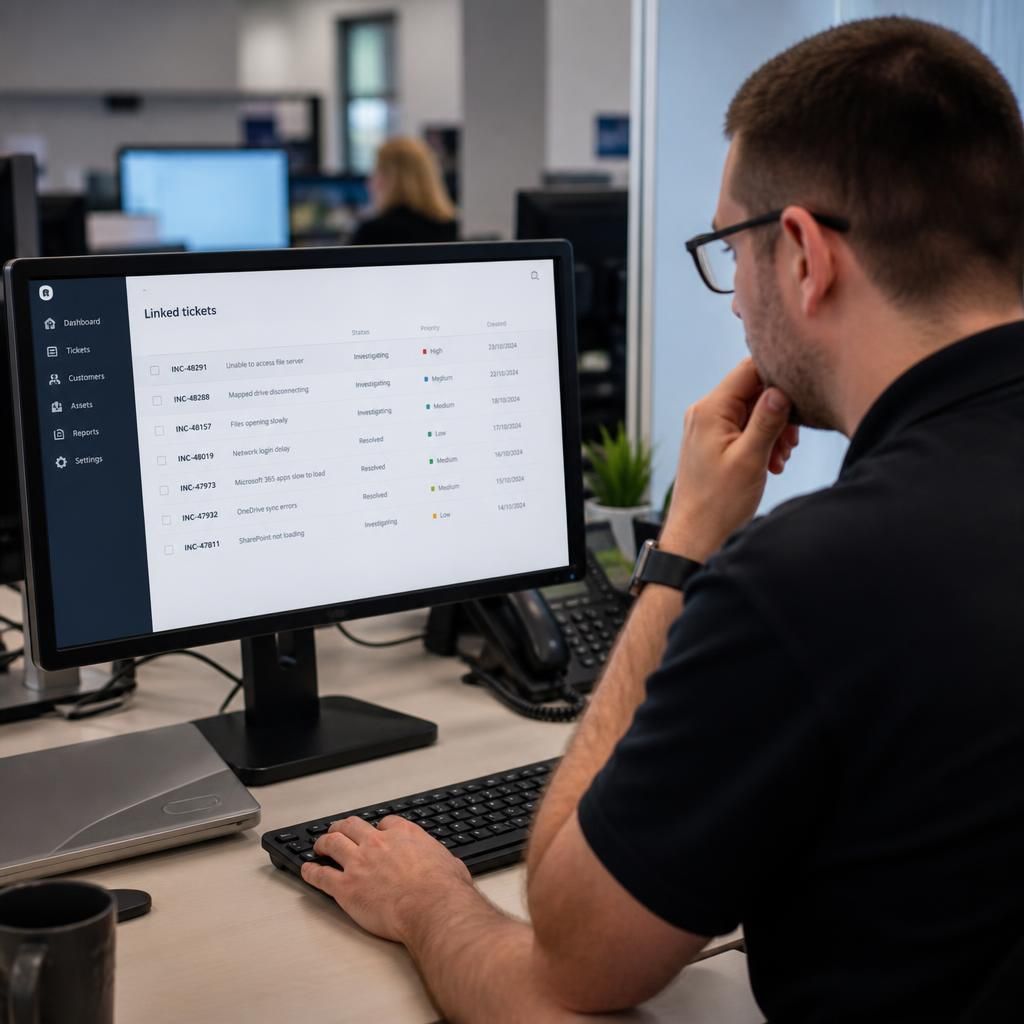
- Incident correlation: Support records are linked when they share symptoms, affected systems, error messages, timings or environmental conditions.
- Impact assessment: The helpdesk considers the number of users affected, the importance of the service and the operational consequences of further failures.
- Technical investigation: Technicians review logs, configuration settings, system dependencies, recent changes and device or account condition.
- Cause validation: A suspected cause is tested against the available evidence rather than accepted solely because it appears plausible.
- Controlled remediation: Any change is planned, assessed for risk and applied in a way that limits the possibility of creating a wider fault.
Evidence collection is important because recurring issues are often intermittent. A user may report that an application “keeps crashing”, but that description does not identify whether the cause is an outdated component, insufficient permissions, corrupted local data, a network dependency or a fault within the application itself. The helpdesk may therefore request exact error messages, timestamps, screenshots, affected asset details and information about what happened immediately before the failure. Technical logs and configuration comparisons can then be used to test each possibility.
Where the cause cannot be removed immediately, the helpdesk may create a known-error record. This records the symptoms, affected services, confirmed limitations, approved workaround and conditions requiring escalation. A known-error record prevents technicians from restarting the investigation from the beginning each time the issue returns. It also gives users and support staff consistent guidance while a permanent correction is being prepared.
Workarounds should be treated as controlled operational measures, not as evidence that the issue has been resolved. A workaround might restore access, redirect a process or isolate an affected device, but it can introduce administrative effort, security risk or additional failure points. The helpdesk should record who is affected, what the workaround changes and when it should no longer be used. If the workaround involves weakening a security control, sharing credentials or bypassing normal approval, it should not be adopted simply for convenience.
Recurring technical issues also require change control. Before modifying a server, network configuration, cloud setting, application or endpoint policy, the helpdesk should define the intended result, identify dependencies, prepare a rollback plan and consider whether the change could affect other services. Changes should be tested where practical and scheduled with the relevant business owners. After implementation, the original fault and any unintended effects should be checked against the conditions that caused the recurrence.
Communication is another part of effective handling. Users need to know whether an issue is being investigated, whether a temporary measure is available and whether they must provide further information. Internal stakeholders may also need to understand the operational risk, affected services and decisions required from the business. Clear communication reduces duplicate reports and helps staff avoid inconsistent self-help actions that could obscure the evidence.
Once the technical work is complete, the helpdesk should update the support record with the confirmed cause, corrective action, affected assets, relevant configuration details and any preventative guidance. This information can be used to improve troubleshooting scripts, internal documentation, user guidance and onboarding material. It also helps identify whether the same fault is appearing in another part of the organisation.
Useful measures include the number of related incidents, repeat contacts for the same issue, time spent on workarounds, affected services and whether the fault returns after the corrective change. These measures should be interpreted with context: a rise in recorded incidents may reflect better reporting rather than poorer technology. The purpose is to identify operational risk and improve the support process, not merely to close individual tickets.
For a small or medium-sized organisation without a dedicated problem-management function, these activities can be incorporated into normal IT helpdesk support. The essential requirements are consistent records, evidence-based diagnosis, controlled changes, documented workarounds and clear ownership until the recurring fault has been properly addressed.
Recurring technical issues can indicate configuration drift across an organisation rather than a fault in one device or account. An IT helpdesk can compare affected and unaffected systems against the approved baseline, including software versions, security settings, device policies and network configuration. This helps establish whether the issue is being introduced by inconsistent builds or unmanaged changes.
Where drift is confirmed, the corrective action should match the scope of the cause. A single device may need repair, while a shared configuration issue may require a controlled update across a defined group of systems. Exceptions should be recorded so that legitimate differences are not removed accidentally. The findings can also inform device standards, asset reviews and future change assessments, reducing the likelihood that the same condition is recreated.