How does managed backup monitor failed or incomplete backup jobs?
Managed backup monitors each job’s completion status, checks for errors or missing data, and flags failed or incomplete runs rather than treating them as successful. The issue can then be investigated through backup logs, with corrective action such as rerunning the job, resolving the underlying fault or adjusting its configuration.
Managed backup detects a failed or incomplete job by comparing the expected result with the evidence produced during the run. It records whether the job started, which data sources were processed, whether the backup target received the data, and whether the resulting restore point passed the service’s validation rules. A run is therefore not treated as successful simply because it began or transferred some files.
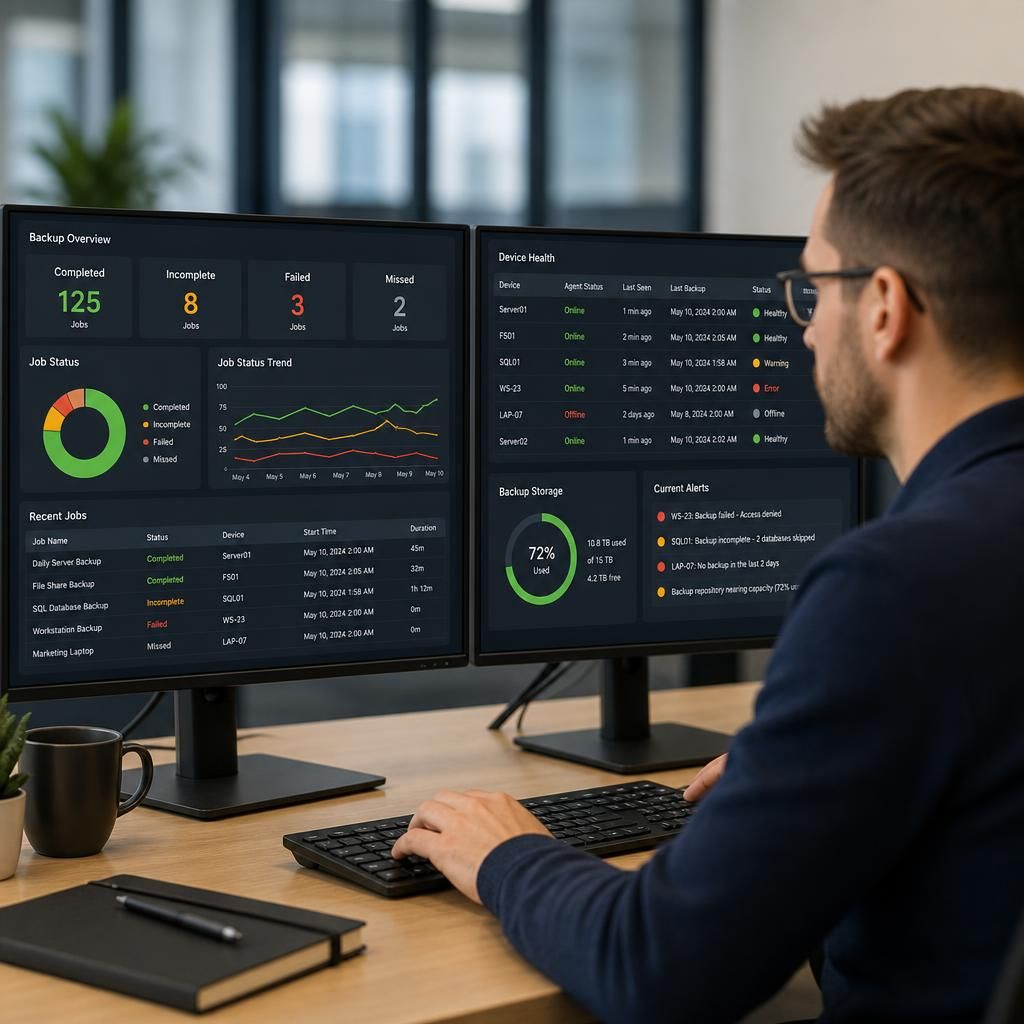
Monitoring normally evaluates several distinct outcomes:
- Successful: the scheduled sources were processed and the backup completed in accordance with policy.
- Partially complete: the job finished but one or more systems, files, databases or data sets were excluded, skipped or interrupted.
- Failed: the job could not produce the expected backup, perhaps because of a connectivity, authentication, storage or application error.
- Missed: the expected job did not start, which can indicate a disabled schedule, an unavailable device or a problem with the backup agent.
This distinction matters because a partial job can leave a business with a usable restore point while still creating an unprotected gap. Monitoring should identify what was not backed up, rather than reducing every outcome to a simple pass or fail.
Backup systems generate operational information during each run. A managed service reviews this information for issues such as unavailable devices, expired credentials, insufficient repository capacity, interrupted network connections, locked files, unsupported workloads, application errors and jobs that exceed their permitted run window. It can also compare the volume or scope of data processed with the normal pattern, helping to highlight an unexpectedly small backup even where the software reports completion.
Alerts are generally based on the seriousness and persistence of the issue. A single transient interruption may be handled differently from a repeated failure, an absent backup for a critical server or a repository approaching capacity. Alerting may include the affected workload, the time of the last usable backup, the nature of the fault and the action required. Consolidating related alerts prevents repeated notifications for the same underlying problem while preserving an audit trail of each event.
Some faults can be addressed through controlled automation. For example, the service may retry a failed operation where the cause appears temporary, restart an agent or reschedule a job after a dependency becomes available. Automation should not repeatedly retry a persistent fault without review, because that can hide an ageing backup and consume additional storage or network resources. Repeated failures normally require investigation of the source system, credentials, network path, backup configuration or destination.
When a job is incomplete, remediation starts by identifying the missing scope and determining whether an earlier restore point still meets the organisation’s recovery requirements. The operator may then correct an exclusion, reconnect the affected device, renew access permissions, resolve an application issue, increase available capacity or adjust the backup window. The job is rerun and its resulting restore point is checked rather than assuming that the corrective change worked.
Effective monitoring also tracks trends, not just individual incidents. Useful measures include the age of the newest usable restore point, recurring failures by workload, repeated partial coverage, repository utilisation and the number of jobs requiring manual intervention. Trend information can reveal a growing data set, an unreliable connection or a configuration that no longer matches the organisation’s systems.
For a business using managed backup, the important question is not merely whether an alert was generated. The service should show which data is currently protected, which jobs need attention, what corrective action was taken and whether the next completed run restored the expected level of coverage. This provides a clearer basis for ongoing IT management and helps ensure that backup exceptions are dealt with before they become a recovery problem.
Managed backup should monitor the backup agent as well as the individual jobs it runs. An agent that has stopped communicating may prevent a job from being created, leaving no normal completion record to assess. Separate checks can therefore look for a current agent connection, valid configuration and recent communication from each protected device.
This is particularly important for laptops, remote systems and servers that are not continuously connected to the backup environment. If an agent is removed, disabled or running an outdated configuration, the monitoring record should show that change as a protection issue. Reviewing agent health alongside job results helps distinguish a failed backup operation from a wider loss of visibility and ensures that the systems expected to be protected remain represented in the managed backup service.