How do IT support services prioritise competing user requests?
IT support services prioritise competing user requests by assessing business impact, urgency, security risk, the number of people affected and any dependencies between systems. Incidents that threaten critical operations or data security are handled before lower-impact individual issues, with requests categorised and their priority reviewed as circumstances change.
IT support services prioritise competing requests through a documented triage process that turns different types of demand into consistent priorities. The process considers the effect on business operations, the consequences of delay, the users and systems involved, security implications, and the work already required to restore or provide the service. This helps the support team allocate effort according to business need rather than simply handling requests in the order they arrive.
The first step is to classify the request. A user may be reporting an incident, asking for a standard service, or requesting a change. An incident is an unplanned disruption, such as an inability to access a key application. A service request may be a new user account, software installation or permission change. A change request could involve modifying a network, device configuration or business system. Treating these categories separately prevents routine administration from competing directly with an outage or security concern.
Support teams then establish the practical impact. Useful questions include:
- Is a critical business process stopped, degraded or still available?
- How many people, teams, locations or customers are affected?
- Can staff use a safe workaround, or are they unable to continue?
- Is the issue affecting a shared platform or only one device?
- Will delaying the work create financial, legal, contractual or operational consequences?
- Does the request involve suspected compromise, data exposure or an unsafe configuration?
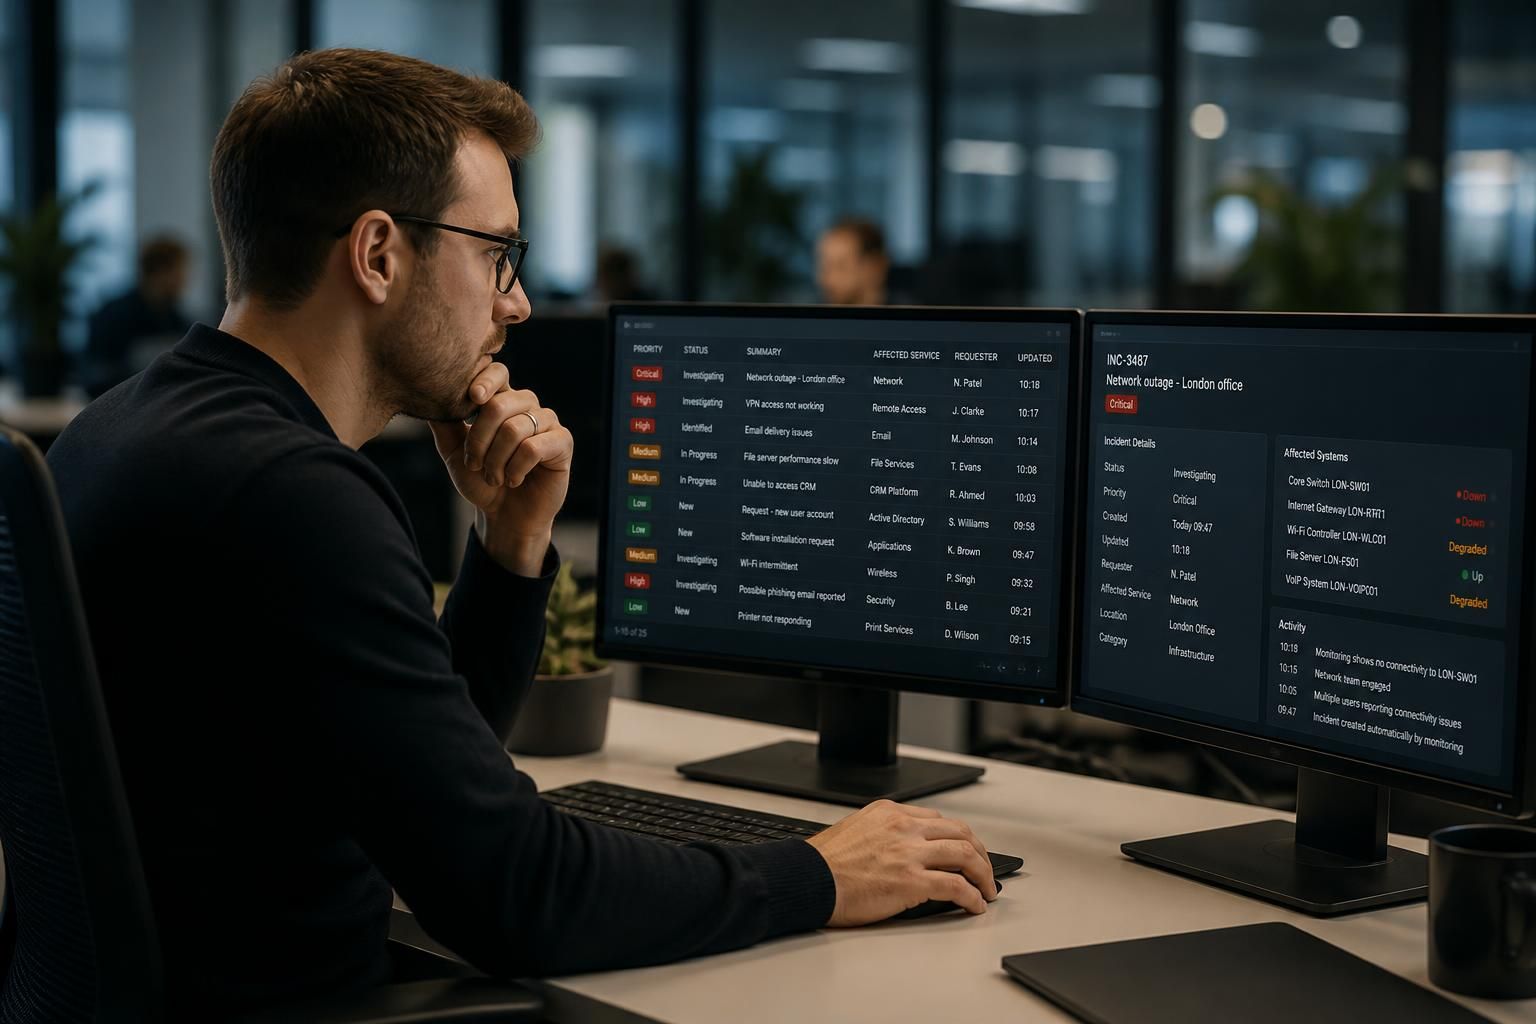
The answers are normally recorded in the service desk system, alongside the category, affected service, requester and relevant business owner. This gives technicians enough context to assess the request consistently and creates an audit trail for later review.
Priority is usually determined by impact and urgency together. A problem affecting one person may still be important if that person is responsible for a critical process, while a larger issue may have a lower priority if an effective workaround is available. Conversely, a request with a broad impact may need immediate attention even where no individual user has described it as urgent. Priority should therefore reflect the business situation, not the wording used in the ticket or the seniority of the person submitting it.
Many providers use priority levels with defined criteria, such as critical, high, medium and low. These levels should describe the circumstances rather than merely attach a label. For example, a suspected ransomware event, loss of access to a core operational system or failure of a major network connection would normally require a different response from a request to install an optional application. The exact categories and escalation rules should be agreed with the organisation so that they match its operating model and risk tolerance.
Security can change the order of work. A device displaying signs of malware, an unexpected privileged-account change or evidence of unauthorised access may take precedence over ordinary user support. The objective is not only to restore the affected user but also to contain the risk, preserve relevant evidence and prevent the issue spreading. Security-related prioritisation should be handled carefully, because disconnecting equipment, resetting credentials or blocking access can itself affect business operations.
Dependencies are also considered before work begins. A request may depend on another team, a supplier, a network service, an identity platform or an approved change. Resolving a visible symptom without addressing the dependency can create repeat incidents or disrupt another service. The support team may therefore group related tickets, assign an owner to the underlying problem and keep associated user requests linked to it. This avoids several technicians investigating the same fault independently and makes the wider effect easier to track.
Good prioritisation is not a one-time decision. Circumstances can change as more information becomes available. An isolated fault may become a wider service interruption, a workaround may stop functioning, or a security concern may be ruled out after investigation. The priority should be reviewed when the scope, risk or business impact changes, with the reason for the change recorded. Requests that remain blocked should also be reassessed rather than left indefinitely in the queue.
Communication is part of the prioritisation process. Users should be told that their request has been logged, what information is needed, whether it is linked to a wider issue and when its status will be reviewed under the organisation’s agreed service arrangements. Where several requests compete for the same technical resource, the support provider should explain the operational reason for the order without disclosing confidential information about other users or systems. This makes the process more transparent and reduces duplicate tickets and repeated escalation.
Managers should periodically review prioritisation records for patterns such as repeated emergency work, frequent misclassification, unresolved dependencies or requests that are routinely escalated outside the agreed process. Those findings can identify weaknesses in documentation, access controls, infrastructure or user training. In this way, prioritisation is not just a method for organising a queue; it also supplies evidence for improving the underlying IT service.
A managed IT support provider can formalise these rules through a service desk workflow, agreed priority definitions, escalation paths and regular reporting. The most useful arrangement is one where the provider understands which systems and processes matter most to the organisation, while the business retains clear ownership of risk and operational decisions.
One practical way to manage competing requests is to separate interruption handling from planned fulfilment. Incidents that require investigation can be worked through the support queue, while routine tasks such as equipment preparation, software deployment or account administration are scheduled into agreed work periods. This prevents planned activities from being repeatedly abandoned whenever a new ticket arrives.
The schedule should also account for operational risk. Changes affecting shared systems may be grouped into a suitable maintenance window, whereas low-risk tasks can be completed without waiting for broader coordination. Requests that cannot be safely completed in the current conditions should remain visible with a clear reason and next action, rather than being treated as overdue or silently removed from the queue.
This approach gives users a more accurate view of how work is organised. It also helps managers distinguish genuine service pressure from poor scheduling, excessive avoidable interruptions or a lack of technical capacity. Those distinctions are useful when reviewing the support arrangement and deciding whether processes, systems or resourcing need to change.