
How does cloud backup handle failed backup jobs?
Cloud backup platforms detect failed jobs, record the cause, and usually retry them according to configured policies, while alerting administrators when intervention is needed. S2 Technology Group can review failure notifications, investigate issues such as connectivity or access errors, and adjust the backup configuration so important data is not left unprotected.
A failed cloud backup job should leave the last verified recovery point intact while clearly separating it from the incomplete run. The platform should prevent a partial or corrupted backup from being presented as a valid restore point, preserve earlier copies according to the retention policy, and record which data was not successfully protected.
Handling depends on the type of failure. A temporary interruption may allow the job to continue from its last confirmed checkpoint rather than sending the entire dataset again. If the backup process cannot resume safely, it should abandon the incomplete copy and begin a clean or controlled follow-up run. This avoids treating a file that was only partly transferred as recoverable.
Common causes include:
- Loss of connectivity between the protected system and the cloud service
- Insufficient storage capacity or a quota being reached
- Changed permissions, expired credentials or a disabled service account
- Files being locked while an application is writing to them
- Unsupported file types, damaged source data or configuration errors
- Resource constraints on the device, server or virtual environment running the backup
The important distinction is between a job that fails completely and one that completes with exceptions. A complete failure may leave the previous recovery point as the only usable copy. A job with exceptions may protect most data while omitting particular files, databases or application components. Both conditions require investigation because a backup report showing overall completion does not necessarily mean that every required item can be restored.
Business-critical applications may need application-aware protection rather than a simple copy of open files. For example, a database backup must preserve a consistent transaction state, while a virtual machine backup must capture the configuration and storage needed to start it again. If a job fails during this process, the platform should retain the last consistent application recovery point and identify the affected workload separately from ordinary file-level data.
Secure failure handling also depends on access controls. A failed job caused by invalid credentials should not be resolved by weakening permissions or storing passwords in an unprotected script. The account used for backup should have only the access it needs, with credentials managed securely and changes recorded. Where backup data is encrypted, recovery procedures must also account for the authorised key or secret required to read the protected copy.
After the underlying issue is corrected, the follow-up job should be checked for scope, not merely for a successful status. Useful checks include:
- Confirming that the previously missing systems, folders or applications are included
- Reviewing whether the job created a new usable recovery point
- Checking that the copied data is complete and consistent
- Verifying that retention and deletion rules have not removed the only suitable earlier copy
- Recording the cause, corrective action and result for future review
Regular restore testing is the practical way to confirm that recovery points remain useful after a failed job. A test can involve restoring selected files, recovering an application component or validating a complete system recovery process in an isolated environment. The test should confirm both data integrity and the supporting information needed to rebuild the service, such as configuration, permissions and dependencies.
For a small or growing organisation, the most reliable process combines cloud backup software with defined ownership of failure review, suitable escalation rules and periodic configuration checks. S2 Technology Group can help assess failed-job records, identify recurring configuration or infrastructure issues, and review whether the resulting recovery points cover the systems the business depends on.
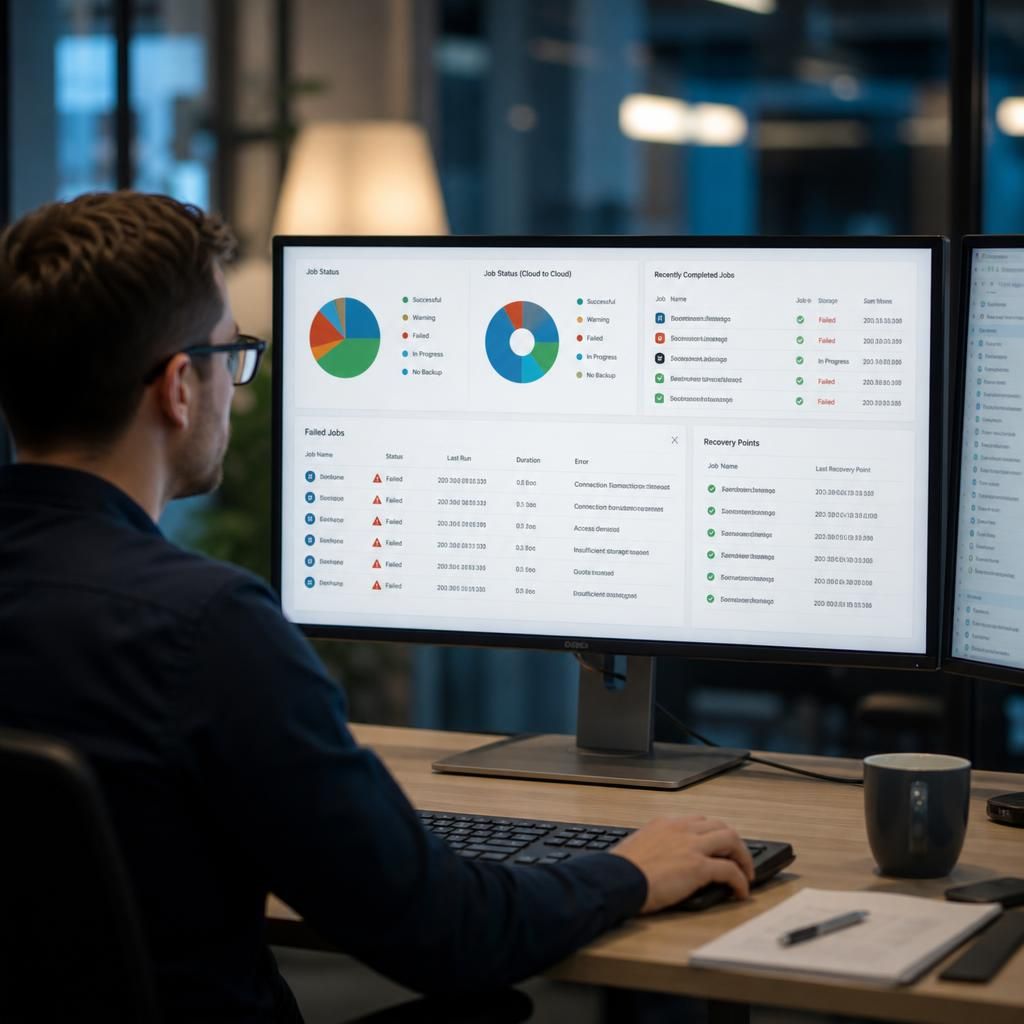
A retry policy controls what happens after a cloud backup job fails temporarily. The platform may wait before trying again, limit the number of attempts and raise an alert when the failure persists. This prevents a recurring fault from being hidden by endless retries and gives administrators a clear point at which investigation is required.
Retry behaviour should also account for the workload being protected. Repeating an interrupted file transfer is different from rerunning an application-consistent database operation, where the backup process must avoid creating an incomplete or conflicting copy. Backup reports should therefore show each attempt, its outcome and the final protection status, so the organisation can distinguish a successful recovery point from a sequence of unsuccessful retries.