
How are planned connectivity changes controlled?
Planned connectivity changes are controlled through a documented change process that records the proposed work, assesses its business and security impact, and obtains approval before implementation. The process should define testing, communications, implementation steps, monitoring and a rollback plan so disruption and risk can be managed if the change does not perform as expected.
Planned connectivity changes are controlled safely by treating each change as a governed operational decision rather than a purely technical task. The control framework should show why the change is needed, which services and sites could be affected, who is accountable for each decision, and what evidence confirms that the new arrangement is operating correctly.
Start with a complete change record. The record should identify the affected circuits, locations, network devices, cloud services, security controls and business applications. It should also state whether the work involves a configuration adjustment, a carrier change, new equipment, a routing amendment, a firewall rule or a change to resilience. Recording these dependencies prevents a local-looking change from being assessed in isolation when it could affect remote users, voice services, hosted systems or connections between sites.
The requested outcome should be expressed in measurable operational terms. For example, the objective might be to introduce a secondary connection, alter traffic routing, support a new site or accommodate a cloud service. The record should define the intended end state and the conditions that must be met before the change can be closed. This gives the technical team and the business the same basis for judging whether the work has achieved its purpose.
Apply proportionate risk classification. Not every connectivity change needs the same level of scrutiny. A minor amendment to a non-critical segment may require a simpler approval route than a change affecting internet access, inter-site routing, remote access or security boundaries. Risk assessment should consider:
- the number of users, sites and services within scope;
- the possibility of loss of connectivity or degraded performance;
- the effect on security, access controls and traffic inspection;
- dependencies on carriers, hosting providers or other third parties;
- the availability of a tested alternative path or manual workaround;
- the difficulty of restoring the previous configuration; and
- the business impact if the change is unsuccessful.
A clear classification helps determine the appropriate technical review and business authorisation. It also prevents routine work from being delayed by unnecessary bureaucracy while ensuring that high-impact changes receive sufficient scrutiny.
Define ownership before implementation. The person carrying out the work should be identifiable, but they should not be the only person responsible for the decision. A well-controlled change normally separates the roles of requester, technical implementer, approver and business owner where the level of risk justifies it. Responsibilities should include confirming prerequisites, coordinating suppliers, authorising access, communicating status and accepting the completed result.
This is particularly important where connectivity is delivered through several parties. The organisation should know which provider is changing the service, which party controls the edge equipment, who can approve configuration changes and who is responsible for validating the business impact. Supplier actions should be linked to the same change record rather than managed through disconnected email conversations.
Use controlled configuration information. Engineers should work from an approved and current record of the network design, device configurations, addressing, routing relationships and security policies. The configuration being used should be identifiable, with revisions retained so that unauthorised or unexplained differences can be investigated. Access to make changes should be restricted to appropriately authorised personnel, and privileged activity should be attributable to an individual account rather than a shared login.
Before work begins, relevant prerequisites should be checked. These may include current device backups, available management access, compatible firmware or configuration syntax, confirmed circuit status, supplier readiness and sufficient capacity on the target service. Dependencies should be verified rather than assumed. A change that depends on a new circuit, an updated route advertisement or a firewall policy should not proceed until those conditions have been confirmed.
Separate planned changes from urgent restoration work. An emergency change may be necessary to restore a failed service or contain a security issue, but it should not become a way to bypass normal control for convenience. Emergency work should use a defined route with retrospective review, documentation and confirmation that any temporary configuration has either been formalised or removed. Planned connectivity improvements should remain within the normal governance process, even when a preferred implementation date is approaching.
Control the implementation environment. The approved change should match the work actually performed. If the scope, affected service or technical method changes materially, the work should be paused and reassessed rather than being extended informally. Maintenance activity should be coordinated so that conflicting work does not occur on the same devices, circuits or security controls at the same time. A change freeze or additional approval may be appropriate during periods when connectivity is especially important to business operations.
Validation should cover more than whether a device accepts a command. Technical checks can include circuit status, routing tables, latency, packet loss, throughput, failover behaviour, DNS resolution and access through required security controls. Business checks should confirm that representative users, sites and applications can perform their normal functions. The results should be recorded as evidence, including any deviations from the expected outcome.
Close the change only after review. Closure should confirm that the final configuration is documented, monitoring and support records reflect the new arrangement, supplier tickets are updated and any temporary access or settings have been removed. A post-change review is useful when the work was complex, produced unexpected results or involved several providers. It should examine whether the original risk assessment was accurate, whether dependencies were understood and whether future changes can be made more safely.
For small and medium-sized organisations without a full in-house network team, managed IT support can provide the governance as well as the technical work: maintaining network records, coordinating providers, reviewing proposed amendments and preserving an audit trail. S2 Technology Group supports businesses around Stourbridge, Kinver, Wordsley, Kingswinford, Kidderminster, Halesowen, Dudley and neighbouring areas with connectivity, infrastructure and security management that can form part of this wider control framework.
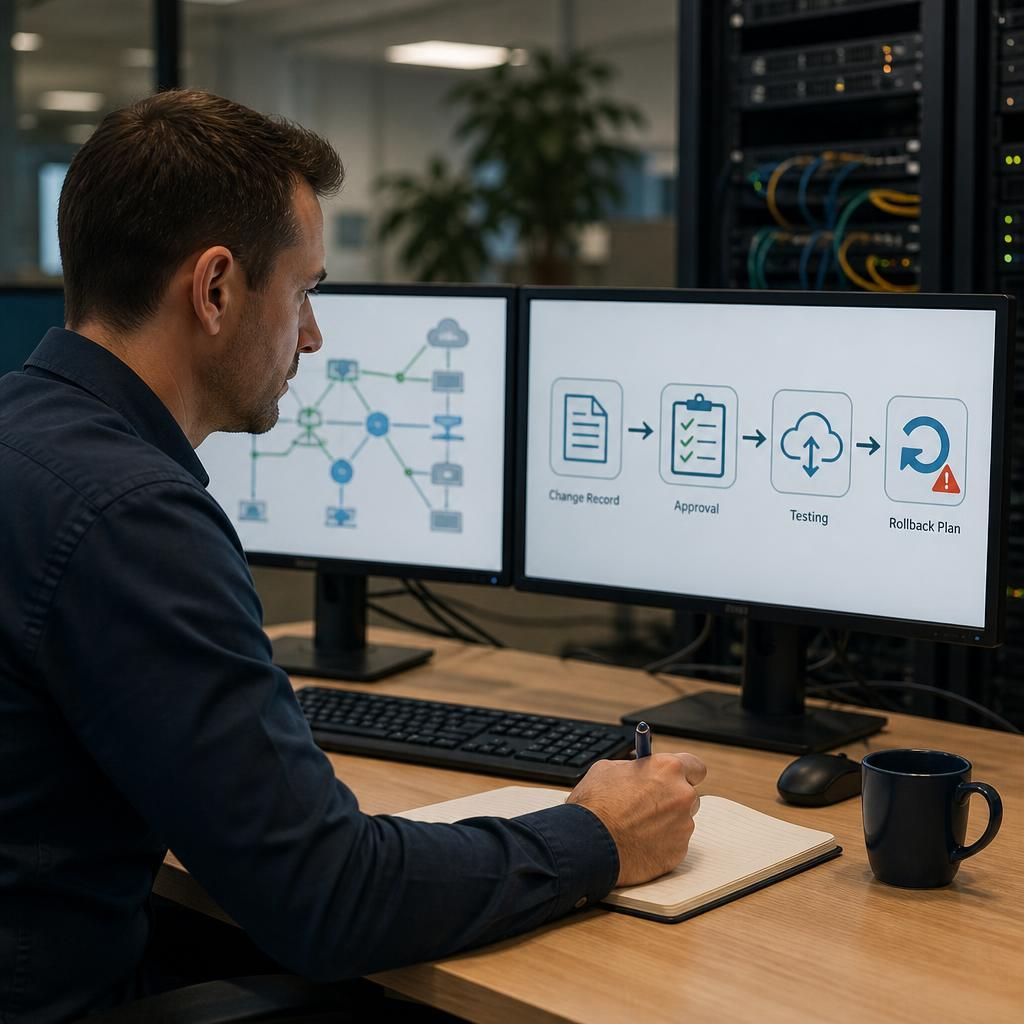
A rollback plan should describe how the previous connectivity arrangement will be restored if the change fails its acceptance criteria. It should identify the exact configuration, routing state, equipment or circuit settings to reinstate, along with the person authorised to trigger the rollback and the evidence needed to confirm that restoration is complete.
The plan should also account for dependencies created during implementation. For example, reverting a route may require associated firewall rules, authentication settings or monitoring thresholds to be restored as well. Configuration backups should be taken before work begins, and the rollback method should be reviewed for practicality rather than treated as an assumption. After restoration, representative services and users should be checked before the change is marked unsuccessful and closed for investigation.