
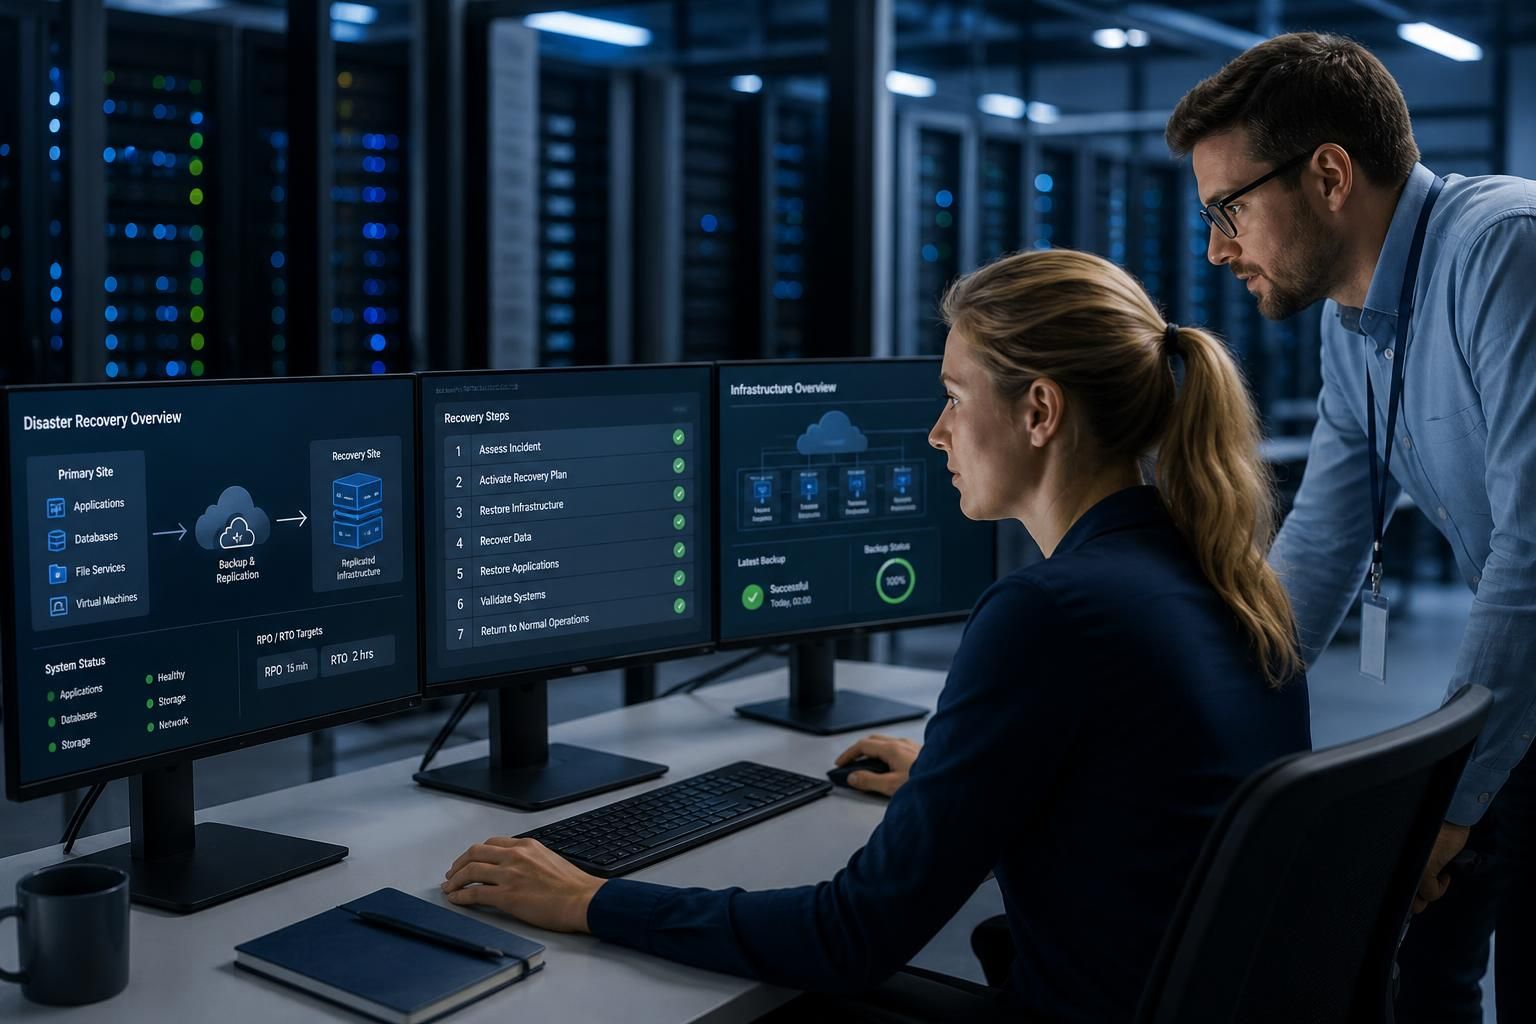
What disaster recovery arrangements does IaaS include?
IaaS disaster recovery arrangements typically include data backup, replication, recovery procedures and, where configured, failover to alternative infrastructure if a primary system becomes unavailable. The exact scope should define backup frequency, retention, recovery objectives, testing responsibilities and which applications, systems and data are covered.
IaaS disaster recovery is a planned combination of resilient infrastructure, recovery controls and documented actions used to restore business systems after a serious disruption. IaaS does not automatically provide complete disaster recovery: the arrangement must specify how infrastructure dependencies, applications, access, communications and business data will be recovered, and which responsibilities remain with the customer.
Recovery architecture may include separate infrastructure or availability zones, redundant storage, alternative network paths and the ability to recreate servers from approved configurations. These measures reduce dependence on a single host, device or site. They are different from a backup, which preserves information for restoration but does not necessarily provide a ready-to-run operating environment.
Recovery orchestration defines the order in which systems are brought back. A typical sequence might start with identity services, networking and security controls, followed by databases, application servers, file services and user access. Dependencies should be documented because restoring an application without its database, authentication service or network configuration may not make it usable.
Recovery documentation normally includes technical runbooks, system inventories, configuration records, application dependencies and escalation contacts. It should explain who authorises a recovery, who performs each technical step, how progress is recorded and how users are informed. Documentation needs controlled ownership so that it remains accurate when infrastructure or applications change.
Data protection arrangements should address more than whether a copy exists. Important considerations include separation from the production environment, protection against unauthorised alteration or deletion, encryption, access controls and the ability to verify that copies can be read. Retention rules should reflect legal, contractual and operational requirements rather than relying on a default setting.
Testing and review are essential parts of the arrangement. A recovery exercise can identify missing credentials, unsupported software, incorrect dependencies, insufficient capacity or gaps in the runbook before a real incident occurs. Testing may range from reviewing procedures and restoring selected files to rebuilding complete services in an isolated environment. Results should be documented, with corrective actions assigned and followed through.
Business continuity boundaries also need to be clear. IaaS can provide the infrastructure platform, but the customer may still need to manage application licensing, software configuration, data classification, user permissions, endpoint access and the business decision to invoke recovery. Third-party applications, on-premises equipment, internet connectivity and external suppliers may require separate continuity arrangements.
Recovery planning should distinguish between a temporary service interruption, a security incident and a site-level loss. For example, a failed virtual machine may require a different response from corrupted data or a suspected ransomware event. In a security incident, restoring immediately from an unverified copy could reintroduce the threat, so investigation, isolation and validation form part of the recovery process.
When assessing an IaaS disaster recovery arrangement, ask for clear answers to the following:
- Which infrastructure, applications, databases and data are included?
- Where are recovery copies or alternative resources located, and are they logically separated from production?
- How are recovery dependencies and configuration changes captured?
- What capacity is available for restored services?
- How are recovery procedures tested, evidenced and updated?
- Which actions belong to the IaaS provider and which must be completed by the business?
- How are security incidents handled before restoration?
- What happens to the recovery arrangements if the service contract or provider relationship ends?
A suitable arrangement therefore combines infrastructure resilience with recoverable data, tested procedures, clear ownership and an agreed method for validating restored services. The detail should be recorded in the service description and supporting recovery documentation, rather than inferred from the fact that systems are hosted through IaaS.
An IaaS disaster recovery arrangement should define recovery time objectives (RTOs) and recovery point objectives (RPOs) for each important service. The RTO states how long a system may remain unavailable before it must be restored, while the RPO states how much recent data the business can afford to lose, measured by the point from which data can be recovered.
These objectives help determine the appropriate recovery design. A critical business application may require replicated infrastructure and frequent recovery points, whereas a lower-priority archive may be restored from a retained backup. The arrangement should record the agreed objectives by workload, explain how they will be measured, and identify any technical or capacity limits that could prevent them being achieved. This prevents a general claim of “disaster recovery” from being mistaken for the same recovery standard across every system.
Review Your IaaS Disaster Recovery Arrangements
Review your current IaaS disaster recovery arrangement against your operational requirements, responsibilities and documented recovery process. S2 Technology Group can help you assess whether the arrangement provides suitable coverage for your business.