
How will IT service management prioritise incidents affecting critical business services?
IT service management prioritises incidents affecting critical business services by assessing their business impact, urgency, affected users, dependencies and risk of further disruption. Incidents with the greatest potential effect on essential operations are assigned the highest priority, escalated through defined procedures and monitored until service is restored.
IT service management prioritises incidents affecting critical business services through a documented, business-led priority model. The model connects each incident to the service it threatens, assesses the consequences of disruption, and applies consistent rules for classification, escalation, communication and review. This prevents the loudest request or the first issue reported from automatically receiving precedence over an incident with greater operational significance.
Start with a clear definition of critical services. An organisation should identify the services that support essential activities, such as order processing, production, customer access, financial operations, communications or access to regulated information. Each service should have an accountable owner, agreed service requirements and a record of the technology components on which it depends. Without this service mapping, the service desk may only see an isolated device or application fault and underestimate its wider business effect.
The service catalogue and configuration information should therefore show relationships between business services, applications, infrastructure, networks, suppliers and user groups. A failure in one shared dependency may affect several services at once. Recognising that relationship allows the incident to be treated as a broader service disruption rather than as a collection of unrelated support tickets.
Use defined priority criteria rather than personal judgement alone. A practical assessment considers:
- the business service affected and whether it is classified as critical;
- the number and type of users or sites affected;
- whether essential business activities are stopped, degraded or merely inconvenienced;
- the operational, financial, legal, regulatory, safety or reputational consequences of continued disruption;
- whether a time-sensitive business event, such as a production run, filing deadline or customer commitment, is at risk;
- whether the incident is spreading or could cause further service failures; and
- whether a safe workaround is available and practical for the affected users.
These criteria are normally combined in a priority matrix. For example, a complete outage of a critical service affecting several sites would fall into the highest category, while a minor fault affecting one user with a straightforward workaround would fall into a lower category. The exact labels may be P1, P2, P3 and P4, or another agreed scale; the important point is that every category has an unambiguous definition and a clear handling procedure.
Business impact should normally carry more weight than technical complexity. A technically difficult fault is not automatically the most important incident. Conversely, a seemingly simple access failure may deserve urgent attention if it prevents a key team from carrying out an essential activity. Priority should describe the consequence to the organisation, while technical severity describes the nature or difficulty of the fault. Recording both gives service teams enough information to allocate the right expertise without confusing engineering effort with business importance.
Incidents should be assigned to an accountable owner as soon as they are classified. The owner coordinates investigation, keeps the record accurate, brings in the required resolver groups and ensures that agreed updates are provided to relevant stakeholders. A major incident process may be invoked for the highest-impact cases, with a co-ordinator managing the response while technical specialists investigate. Separating co-ordination from technical diagnosis helps maintain oversight when several teams, suppliers or business representatives are involved.
Escalation rules should cover both functional and hierarchical escalation. Functional escalation passes the incident to a team with the necessary technical expertise. Hierarchical escalation involves service management, senior business owners or suppliers when the business impact requires additional authority, resource or decision-making. The rules should state who can change the priority, who approves emergency actions and when external parties must be engaged.
Priority is not fixed for the entire incident. The service desk should reassess it when the affected user population changes, a workaround fails, a dependency is found, the business situation develops or the potential consequences increase. A lower-priority incident can become critical if several related reports indicate a wider outage. Equally, a high-priority incident may be reclassified after a stable workaround restores an essential function. Every change should include the reason, the person authorising it and the time of the decision.
Communication should reflect the priority and the audience. Business stakeholders need to know which service is affected, what activities are at risk, what workaround is available, what decisions are required and when the next update will be provided. Technical teams need diagnostic information, recent changes, affected components, error details and relevant dependencies. Updates should distinguish confirmed facts from working assumptions so that inaccurate explanations do not spread during a developing incident.
Incident records should preserve the evidence needed for operational control and later learning. A complete record normally includes the initial report, classification rationale, affected service, business impact, timeline, actions taken, escalation decisions, communications, workaround and restoration details. If the incident reveals an underlying defect, recurring failure or inadequate capacity, it should be linked to problem management for root-cause investigation rather than simply closed after service returns.
After a major or repeated incident, a review should examine whether the service catalogue, dependency information, priority matrix, monitoring, support procedures and continuity arrangements were adequate. The purpose is not only to document what happened, but to identify changes that could reduce the likelihood or effect of recurrence. This may result in improved knowledge articles, revised escalation paths, resilience work, supplier actions or updates to business impact assessments.
For small and medium-sized organisations, a proportionate process is usually more effective than a complex framework that staff cannot apply consistently. S2 Technology Group can help organisations around Stourbridge, Kinver, Wordsley, Kingswinford, Kidderminster, Halesowen, Dudley and neighbouring areas define critical services, document dependencies and establish incident management procedures that reflect their operational priorities.
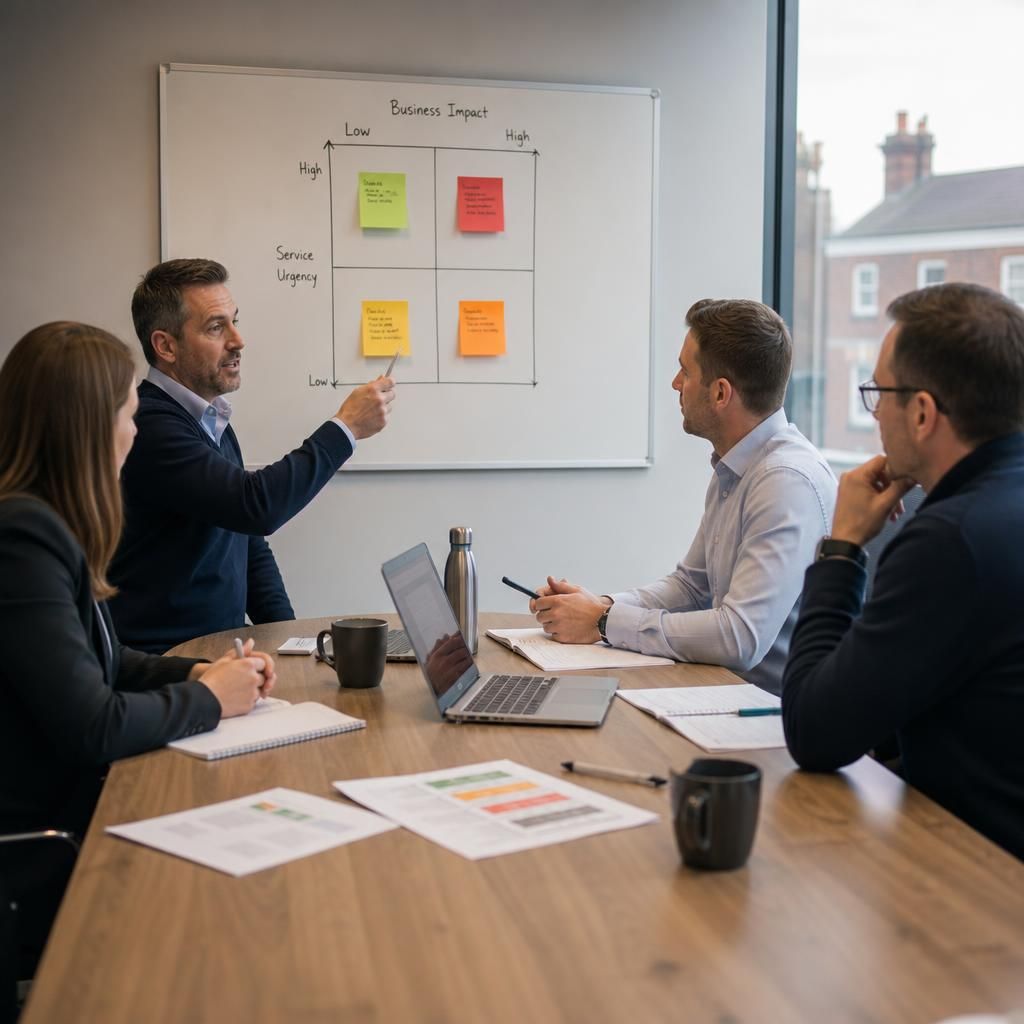
Scenario testing validates whether an incident-priority model produces the intended business outcome before the model is relied on during a live disruption. Service owners, service desk staff and technical teams can assess representative situations independently, then compare their decisions against the agreed priority criteria.
Testing should include partial outages, multiple-site failures, supplier incidents, failed workarounds and incidents occurring during time-sensitive operational activities. Differences in assessment often reveal unclear definitions, missing service dependencies or thresholds that are too subjective. Reviewing previous incidents can identify similar weaknesses, particularly where priority changed repeatedly or escalation happened later than intended. The organisation can then refine the matrix, update supporting guidance and record the approved version so that incident decisions remain consistent.
Discuss your IT service management priorities
Discuss your IT service management priorities with S2 Technology Group to identify where your current approach may need clarification or refinement. Bring your existing procedures or recent incident records so the discussion can focus on practical improvements.