
How often should offsite backups run to meet your recovery point objectives?
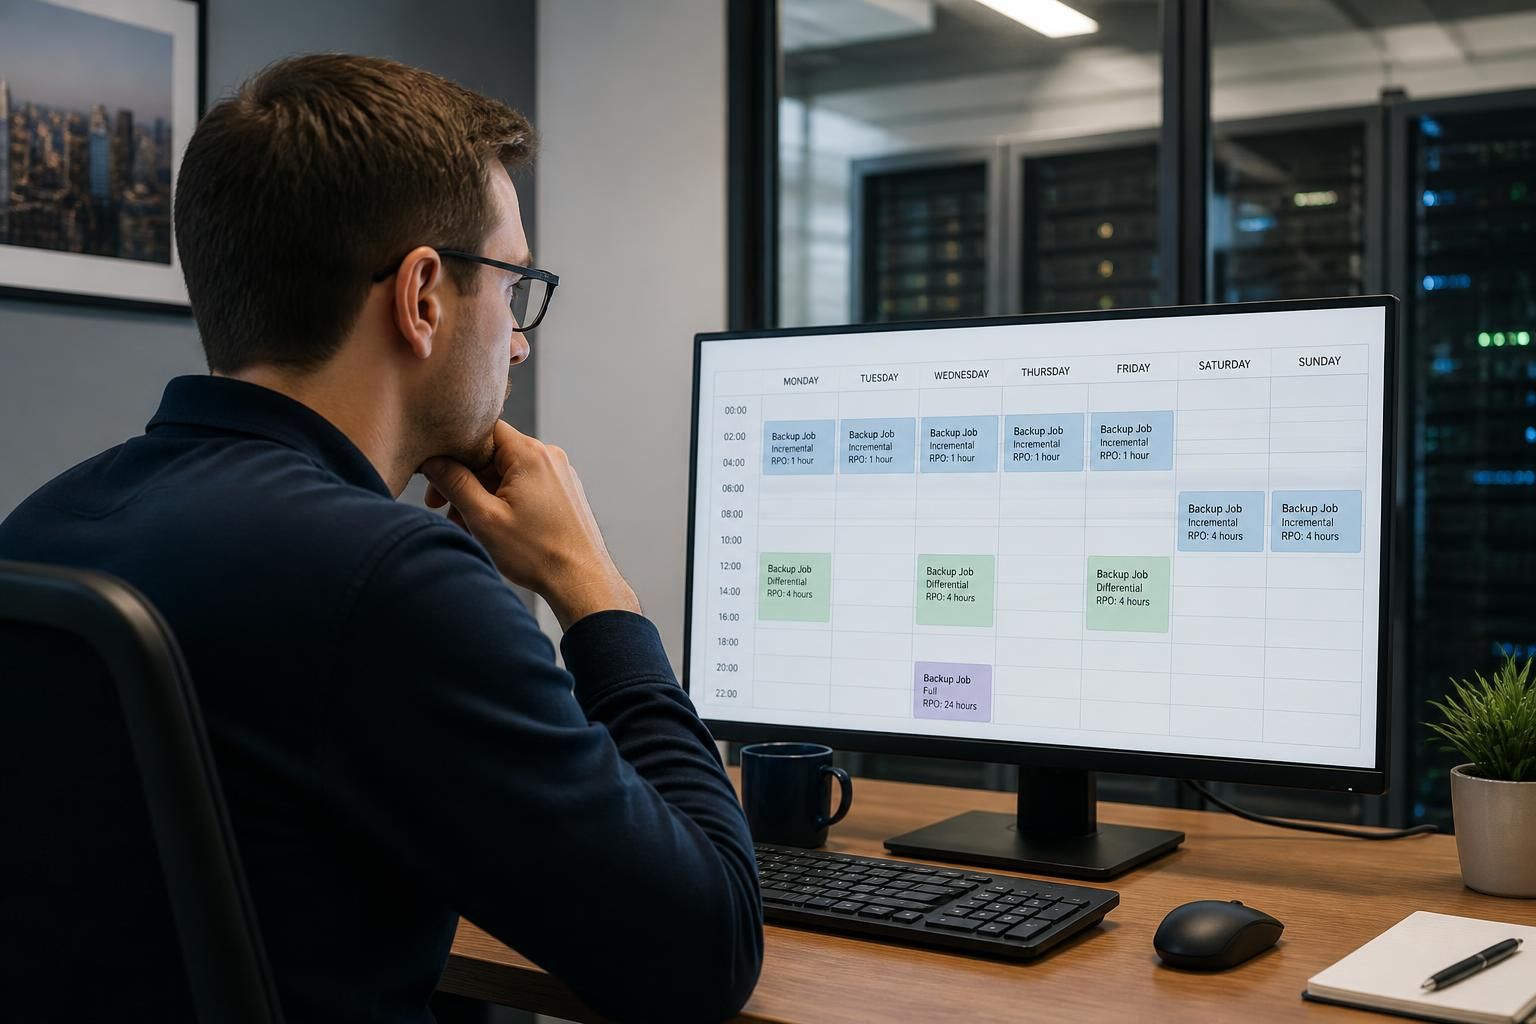
Offsite backups should run often enough that the maximum gap between successful backup copies does not exceed your recovery point objective (RPO). For example, an organisation with a four-hour RPO needs a schedule designed to preserve no more than four hours of recent data if recovery is required.
The appropriate offsite backup frequency is determined by how much data the organisation can afford to lose, rather than by a standard daily or weekly schedule. Set the schedule by workload: data that changes frequently or directly supports ongoing operations generally needs more frequent offsite protection than information that changes occasionally.
Begin by defining the recovery point objective for each important system or data set. The RPO should reflect the maximum acceptable loss of recent changes after an incident. It is not necessarily the same across the business. A transactional database, shared project files and operational records may require frequent protection, while archived documents may be suitable for a less frequent schedule. Applying one interval to every system can either leave critical data exposed or create unnecessary backup activity.
- Frequently changing data: consider frequent backup jobs, continuous data protection or replication where losing a large volume of recent transactions would be unacceptable.
- Standard business files: schedule backups often enough to capture the working day’s important changes in line with the agreed RPO.
- Infrequently changing or archival data: less frequent copies may be appropriate, provided the data remains available for the required retention period and its recovery importance has been assessed.
Backup frequency must also account for the difference between creating a backup and successfully storing an offsite copy. A local snapshot may complete while the transfer to the offsite location is still running, interrupted or waiting for available bandwidth. For RPO purposes, the relevant point is when a usable, recoverable copy has been created in the separate location, not when the job merely starts.
Schedules should therefore allow enough time for each job to finish before the next one begins. Large data sets, slow connections, encrypted transfers and periods of high business activity can extend the transfer window. Initial seeding may require a different approach from ongoing incremental backups because the first complete copy can be substantially larger. After that, changed-block or incremental methods can reduce the amount transferred, although their suitability depends on the backup platform and the applications being protected.
Do not assess frequency solely by looking at the amount of data changed. Application consistency is equally important. A file copy may capture individual documents, but a database or line-of-business application may need an application-aware backup so that related files, transaction logs and configuration information can be recovered together. If those components are protected on different schedules, the apparent backup interval may not represent a usable recovery point.
Business activity can vary by day, project stage or reporting cycle. A fixed schedule may be adequate during ordinary processing but insufficient during a major data import, financial close, product launch or other period when information changes rapidly. Where the technology supports it, schedules can be adjusted temporarily or supplemented with additional recovery points during these periods. The change should be documented so that staff understand which protection applies to exceptional workloads.
RPO is only one part of the recovery design. Recovery time objective (RTO) addresses how quickly a system must be restored, while backup frequency addresses how recent the restored data needs to be. More frequent backups do not automatically produce a fast recovery. Large backup chains, slow restore media, unavailable credentials or an unsuitable recovery environment can still delay restoration. The schedule should therefore be reviewed alongside restore methods, retention, storage capacity and the priority of each system.
A practical scheduling process includes the following steps:
- List the systems, applications and data sets that require protection.
- Record the business owner, acceptable data loss and required recovery order for each one.
- Choose a backup or replication method that can produce recoverable offsite copies at the required interval.
- Check that network capacity and storage performance can complete transfers within the available window.
- Configure monitoring for missed jobs, incomplete transfers, authentication failures and storage limits.
- Review reports and perform test restores to confirm that the stated recovery points can actually be used.
Monitoring is essential because a schedule on paper does not provide protection if jobs fail silently. Alerts should identify whether the failure affected the source backup, the offsite transfer, encryption or the integrity check. Repeated failures need investigation rather than simply being dismissed as isolated errors. A business may appear to have a frequent schedule while its last usable offsite copy is considerably older because recent jobs were unsuccessful.
Test restores should cover representative files and complete application recoveries where appropriate. Testing verifies that backup data is readable, that required credentials and encryption keys are available, and that the recovery point contains the information expected by the business. Results should be recorded and used to revise the schedule if the available recovery points do not match operational requirements.
Finally, reassess the schedule whenever there is a significant change to the business or its systems. New applications, remote offices, cloud services, larger data volumes and changes in working practices can alter both the amount of data created and the consequences of losing it. An offsite backup plan remains suitable only when its frequency, transfer process and restore capability continue to support the organisation’s current recovery point objectives.
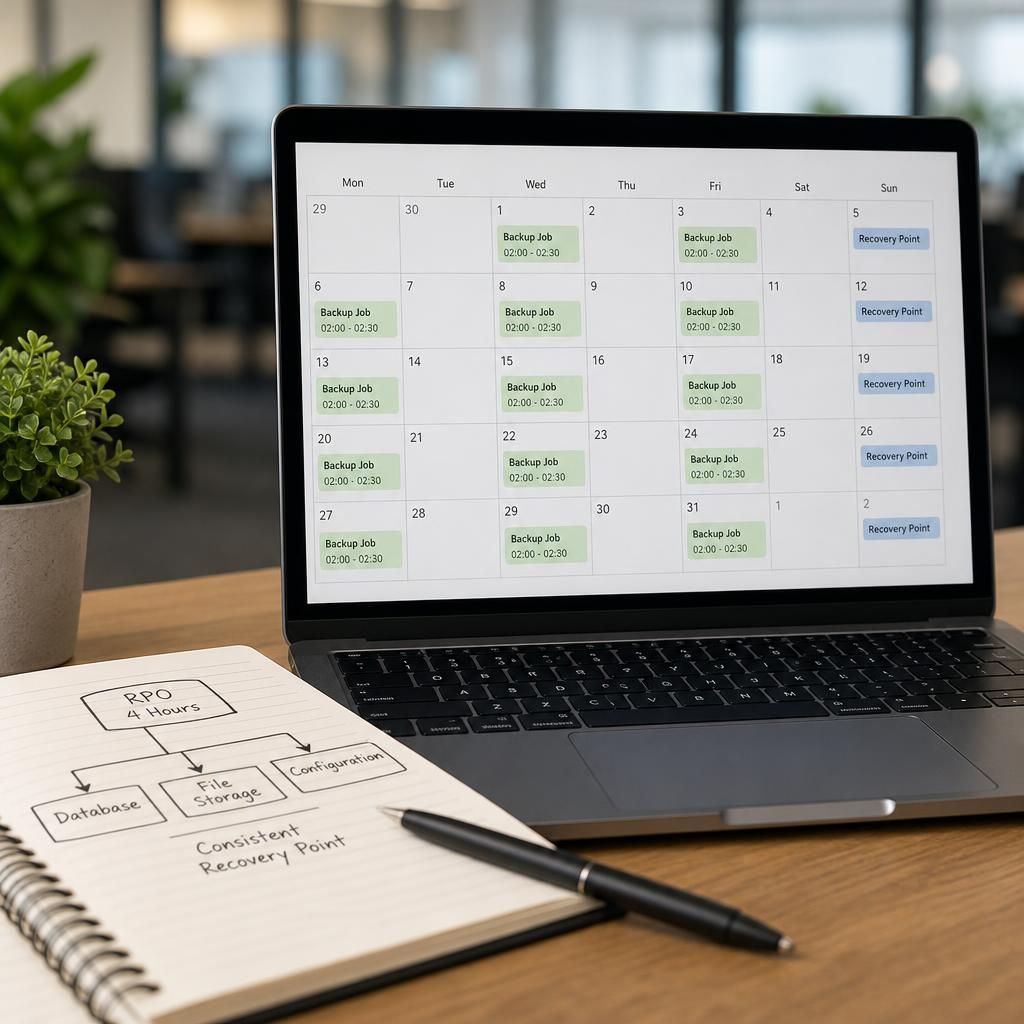
For systems that depend on one another, backup frequency should be planned around a shared recovery point rather than assessed separately. An order-processing system, for example, may rely on a database, file storage and configuration data. If each has a different latest usable copy, restoring them together could produce inconsistent results even when every individual backup schedule appears to meet its stated RPO.
Identify these dependencies before setting intervals, then coordinate backup or replication points where the platform supports it. The RPO for the connected group should reflect the component with the least tolerance for data loss, while restore testing should confirm that the systems can be recovered as a consistent set. This is especially important when several applications share records or rely on a common identity and configuration service.