How are persistent technical problems escalated through remote managed IT support?
Persistent technical problems are escalated through structured diagnosis, documented findings and referral to a more specialised level of IT support when the initial investigation cannot resolve the issue. The escalation includes the steps already taken, affected systems and business impact, helping the next technician focus on root-cause analysis and the appropriate corrective action.
Persistent technical problems are escalated when they remain unresolved after the agreed remote troubleshooting steps, recur after an apparent fix, or require access, expertise or authority beyond the initial support level. Escalation is a controlled transfer of responsibility rather than simply passing a ticket between technicians. The objective is to preserve the evidence gathered so far, limit disruption and involve the right technical resource without losing ownership of the issue.
Escalation usually begins with defined criteria. A support team may escalate when a fault affects a critical business service, involves multiple users or sites, presents a potential security risk, requires infrastructure-level changes, or cannot be reproduced reliably through remote checks. Repeated incidents with the same underlying symptoms may also be treated as a problem requiring deeper investigation, even if each individual occurrence can be temporarily resolved.
- Functional escalation: the issue moves to a technician with more advanced knowledge of the relevant operating system, network, cloud service, server or business application.
- Hierarchical escalation: a service manager or senior engineer becomes involved where the business impact, risk or required decision exceeds the authority of the initial support level.
- Third-party escalation: the provider coordinates with a software, connectivity or hosting supplier when the evidence indicates that the fault sits within an external service.
- Security escalation: suspected account compromise, malware, unauthorised access or data exposure is handled as a security matter, with containment and preservation of relevant evidence taking priority over routine troubleshooting.
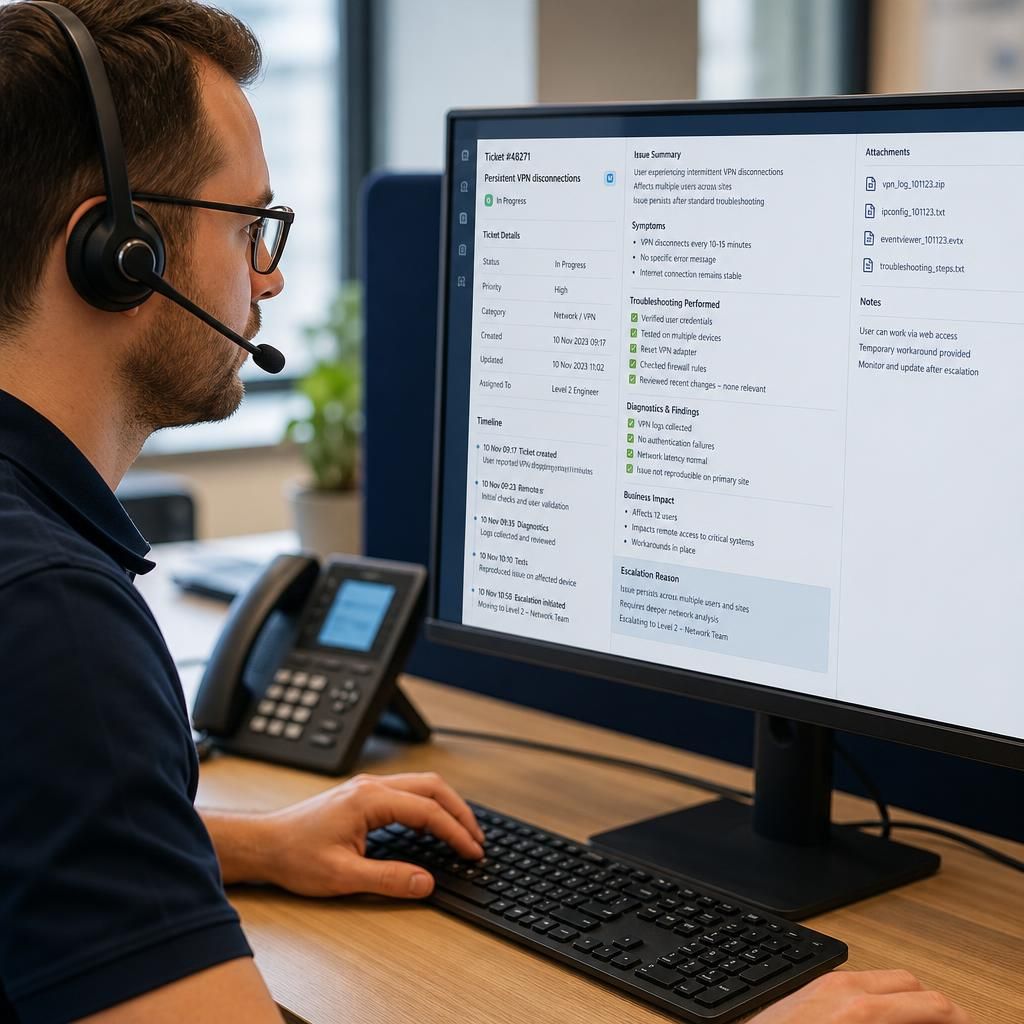
The handover should contain a usable technical record. This normally includes the original symptoms, affected users or devices, error messages, relevant timestamps, environmental changes, diagnostic results, logs where available, actions already attempted and the result of each action. It should also record any temporary workaround, business service affected and restrictions on making changes. A clear record prevents the next technician from repeating low-value checks and gives specialists a reliable starting point.
Business impact helps determine the order in which persistent issues are handled. A problem affecting a core system, several teams or an important operational process may receive greater priority than an isolated device fault, even when the technical symptoms appear similar. Priority should reflect the effect on confidentiality, integrity and availability, as well as the number of people affected. This assessment may change as new evidence emerges.
Remote escalation does not mean unlimited remote intervention. The next-level technician should confirm what can safely be examined or changed through the remote management platform and what requires user involvement, on-site access or a planned maintenance activity. Changes to firewall rules, identity systems, servers, network equipment or production applications should be authorised, documented and capable of being reversed where practical. If remote access cannot provide sufficient evidence, the escalation record should state what information is still needed rather than encouraging unstructured changes.
Where a workaround restores basic operation, the ticket should remain linked to the underlying problem until the permanent corrective action has been assessed. A workaround might involve moving a user to another system, restarting a service or applying a temporary configuration change. These steps can reduce disruption, but they do not necessarily remove the cause. Recording the limitation helps prevent a recurring fault from being incorrectly marked as resolved.
Effective escalation retains clear ownership. The person or team coordinating the incident should track the next action, outstanding dependency, required approval and current status. The business should be given an accurate explanation of what is known, what remains uncertain and whether the current measure is temporary. This is more useful than repeatedly reporting that an issue is being investigated, particularly when the technical cause is not yet confirmed.
For recurring or complex faults, the investigation may move from incident handling into problem management. This involves looking for patterns across tickets, devices, users, locations, changes and monitoring data. The investigation may identify a weak configuration, capacity constraint, unsupported component, software defect, process gap or dependency that was not visible during the original remote session. Corrective work can then be planned separately from the immediate restoration of service.
After the technical change, the issue should be validated against the original symptoms and the affected business process. Validation may include checking monitoring data, confirming that the user can complete the relevant task, reviewing whether related devices show the same behaviour and watching for recurrence. The record should then explain the cause, action taken, remaining risks and any recommended follow-up, such as a configuration standard, patch, access review, replacement or monitoring rule.
For a small or medium-sized organisation without extensive in-house IT expertise, this escalation structure provides access to progressively more specialised investigation without requiring every technical skill to be held internally. Remote managed IT support can therefore combine first-line assistance, infrastructure expertise, security judgement and supplier coordination while keeping the process documented and accountable.
A useful escalation record should explain not only what is failing, but why the issue requires a different level of support. The technician can document whether the problem is isolated to one endpoint, linked to a shared dependency, triggered by a recent change or outside the team’s authorised scope. This reasoning helps the next specialist begin with the most plausible investigation path rather than treating the escalation as an unstructured handover.
Comparing an affected system with a known-working example can strengthen that assessment. Differences in configuration, connectivity, permissions or application behaviour may show whether the fault is local or systemic. When the comparison does not identify a clear cause, recording that uncertainty is still valuable: it tells the receiving technician which explanations have been tested and which evidence is still needed before making a higher-risk change.