
What happens when a server backup repository runs out of space?
When a server backup repository runs out of space, new backup jobs may fail, stop part-way through or overwrite older recovery points, depending on the backup system’s retention settings. The immediate priorities are to identify what is consuming capacity, preserve required recovery points and expand, clean or redesign the repository without weakening protection.
A server backup repository that reaches its capacity limit can no longer maintain the planned set of backup data reliably. The result depends on the backup platform’s storage management rules: it may reject a job, retain only part of a backup chain, remove recovery points according to policy, or report apparent success while leaving fewer usable restore options than expected. The repository should therefore be treated as a capacity-managed system, not simply as a disk that can be filled until an alert appears.
What causes a repository to fill?
Capacity problems are often caused by a combination of normal growth and unexpected consumption. Common causes include:
- Increasing volumes of production data, such as databases, shared files, virtual machines and application records.
- Backup retention settings that preserve more daily, weekly or monthly recovery points than the available storage was designed to support.
- Large full backups being created after changes to the backup schedule, job configuration or protected workload.
- Stale backup files left behind after a server, virtual machine or backup job has been removed.
- Failed or interrupted jobs leaving temporary files, snapshots or incomplete backup chains.
- Replication, copy or archive tasks storing an additional version of the same data in the repository.
- Deduplication or compression performing less effectively as the data mix changes.
- Repository storage being consumed by logs, indexes, metadata or other files that are not included in ordinary backup-size estimates.
Capacity should be assessed from the repository’s actual usable space rather than its raw disk size. File-system overhead, reserved space, deduplication databases and safety thresholds can all reduce the amount available to backup jobs.
Why the backup chain matters
Many backup systems do not store every recovery point as an entirely separate full copy. Incremental or synthetic methods may depend on earlier full and incremental files. Deleting an apparently old file manually can therefore make later points unusable, even if those files remain visible in the storage location. A repository can also contain several related chains for the same workload, each with different retention requirements.
For this reason, capacity should be managed through the backup platform’s retention and cleanup functions wherever possible. If manual deletion is unavoidable, the dependencies between full backups, incremental files, synthetic points, indexes and replicated copies must be understood first.
What to check when space is low
- Confirm that the alert relates to the intended repository and not an underlying volume, mount point or datastore.
- Check usable capacity, reserved capacity and the threshold at which the backup application begins taking action.
- Review recent job history to identify failed, incomplete, unusually large or repeatedly retried jobs.
- Compare the current data footprint with previous backup runs to identify a sudden change.
- List protected workloads and verify that removed servers, obsolete jobs and abandoned chains are not still consuming space.
- Review retention, immutability, replication and archive rules before removing anything.
- Check whether the repository is also being used for non-backup files, temporary exports or unrelated system data.
- Confirm whether the repository has a separate metadata or index area that is close to its own limit.
Monitoring should distinguish between total capacity, currently available capacity, projected consumption and the amount of data that can safely be removed. A single free-space reading does not show whether the repository can accommodate the next full backup or whether a retention rule is about to delete a required recovery point.
Safe ways to restore capacity
The least disruptive approach is usually to use the backup system’s supported cleanup process. This may remove recovery points that have passed their retention period, consolidate chains or clear temporary data while maintaining the relationships needed for restoration. The policy should be reviewed before cleanup so that legal, contractual, operational and security requirements are not accidentally breached.
If retention is reduced, document which recovery points will no longer be available and obtain agreement from the data owner where appropriate. If an additional copy exists, verify that it is complete and independently restorable before treating it as a substitute. A replicated or archived copy is not automatically a usable backup simply because files appear at the destination.
Expanding the repository can provide more headroom, but it does not correct excessive retention, unexpected data growth or a poorly designed backup chain. Moving the repository to a larger storage platform may also require consideration of permissions, encryption keys, network bandwidth, performance, immutability controls and the backup application’s support requirements.
Risks of unmanaged capacity pressure
- New protection jobs may not complete, leaving recently changed data without a valid recovery point.
- A dependent incremental chain may become unusable if its required base files are removed.
- Automatic cleanup may remove older points that are still needed for operational, contractual or investigation purposes.
- Repeated retries can consume additional capacity and obscure the original cause of failure.
- A nearly full volume can affect repository performance and leave insufficient room for indexes, temporary files or restore operations.
- Administrators may resort to unrecorded manual deletion, making the actual retention state difficult to determine.
Capacity alerts should therefore be connected to job-status monitoring. A repository can have free space and still be unable to produce a valid backup if a chain is broken, an index is corrupt or the backup service cannot write to the destination.
How to prevent the problem recurring
Set capacity thresholds that allow time to investigate and act before the repository reaches a critical state. Forecast consumption using the growth of protected data, the actual size of recent backup sets, retention requirements, copy jobs and the storage efficiency being achieved. Reassess the forecast after major changes such as adding a server, migrating a database, enabling a new workload or changing the backup method.
Use separate capacity planning for primary backup storage, replicated copies and long-term archives. Define who can change retention settings, who approves deletion and how exceptions are recorded. Repository access should also be restricted because an administrator or compromised account with permission to delete backup data can turn a capacity incident into a broader recovery problem.
Finally, test representative restores after cleanup, expansion or migration. Check that recent points and older points within the required retention period can be located and recovered, and confirm that the backup reports reflect the repository’s real state. A repository is not adequately managed merely because it has available space; it must have sufficient, protected and demonstrably usable recovery points for the organisation’s recovery plan.
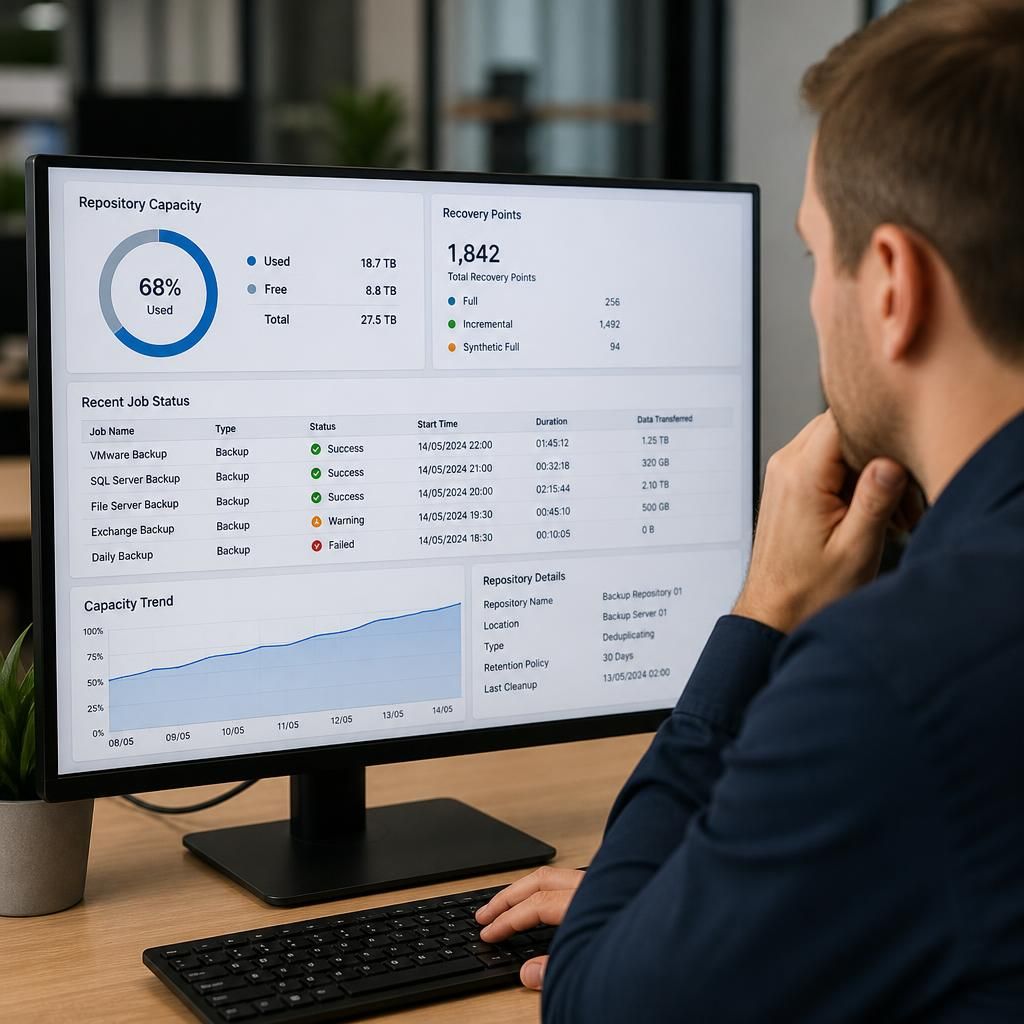
A server backup repository protected by immutability may continue consuming space even after a recovery point appears to have passed its operational usefulness. Retention locks can prevent deletion or modification until the protection period ends, so ordinary cleanup may not release capacity immediately.
Before changing the policy, identify which recovery points are immutable, when their retention periods expire and whether legal or contractual requirements apply. Do not attempt to bypass the protection mechanism or remove underlying files manually, as this can damage the backup set and undermine its evidential value. Capacity planning should allow for locked data, alongside normal retention, replication and archive requirements.