What controls should IT service management apply to technology changes?
IT service management should apply controls covering change assessment, risk and impact analysis, authorisation, testing, scheduling, implementation, rollback and documentation. These controls ensure each technology change is traceable, proportionate to its risk, and capable of being reversed if it threatens service continuity, security or compliance.
Effective IT service management controls for technology changes should govern who can propose, assess, approve, implement and review a change, while ensuring that business priorities, security requirements and service dependencies are considered together. The controls should be proportionate: a routine, low-impact change needs a simpler path than a change affecting identity systems, customer data, core applications or multiple sites.
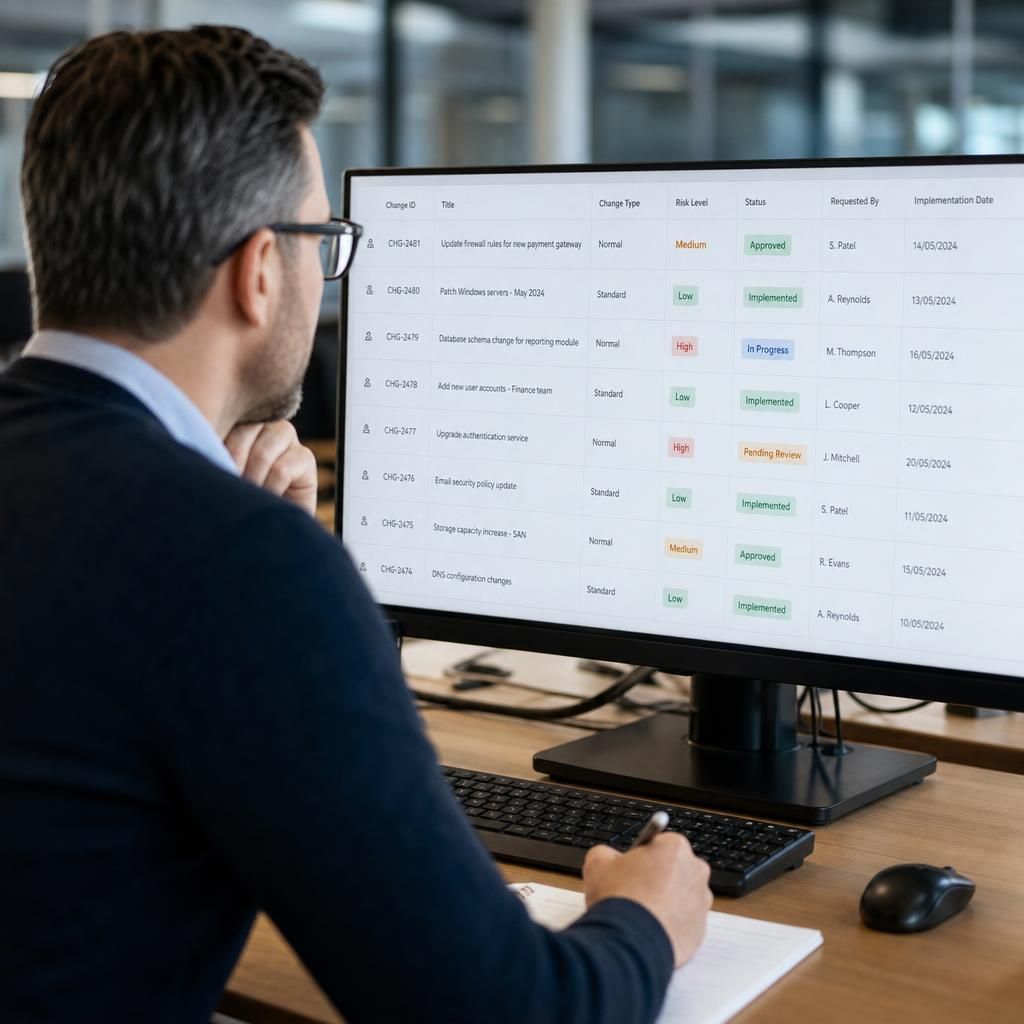
Define clear change categories. A documented classification helps the organisation apply the right level of governance. Common categories include:
- Standard changes: repeatable, low-risk activities with a proven procedure and pre-authorised approval conditions.
- Normal changes: changes requiring individual assessment because their risk, scope or technical approach varies.
- Emergency changes: urgent interventions needed to address a serious security issue, service failure or operational threat. These still require a recorded justification and retrospective review.
Standardisation should not become a way to bypass scrutiny. A standard change should be removed from that category if its scope, system dependency or risk profile has materially altered.
Set decision rights and separation of duties. The person requesting a change should not automatically be the person who approves and verifies it. A change policy should identify who may authorise different risk levels, when business-owner approval is needed, and which changes require security, compliance or senior operational input. For higher-risk work, separating approval, implementation and validation reduces the possibility of an error or unauthorised action passing unchecked.
Maintain a reliable configuration baseline. A change cannot be assessed properly if the organisation does not know what systems, applications, integrations and devices it operates. Configuration records should identify service owners, dependencies, versions, locations and relationships between components. The relevant records should be updated when the change is completed, so future incidents and changes are assessed against the current environment rather than outdated documentation.
Assess business and technical dependencies. The assessment should go beyond the component being altered. It should consider connected services, authentication, networking, data flows, suppliers, user groups and operational processes. It should also record the likely effect on confidentiality, integrity and availability, together with any legal, contractual or regulatory obligations. A technically small change can carry substantial business risk if it affects a shared dependency.
Use documented implementation procedures. A change record should contain enough detail for an appropriately skilled person to understand the intended result and follow the approved method. This normally includes prerequisites, dependencies, commands or configuration steps where relevant, validation checks, ownership and criteria for stopping the work. Procedures should be version-controlled so that the record shows which instructions were used.
Control access during implementation. Privileged access should be limited to authorised personnel and used through identifiable accounts wherever possible. Temporary access should have a defined purpose and expiry, while administrative activity should be logged. These measures connect the technical action to an accountable individual and support investigation if the result differs from the approved plan.
Protect data before making material changes. Where a change could affect data or system recoverability, the organisation should confirm that backups exist, are usable and cover the relevant systems. For critical platforms, recovery procedures should be understood rather than assumed. A backup that cannot be restored within the required business context does not provide dependable protection.
Coordinate related changes. A central change calendar can expose clashes between infrastructure work, application releases, supplier activity, business events and other operational commitments. Related changes should be grouped or sequenced where that reduces risk. Conversely, changes should not be combined merely to reduce administration if doing so would make fault isolation or recovery more difficult.
Communicate according to impact. Communication should identify the affected service, expected user effect, planned activity, responsible owner and route for reporting a problem. Technical teams, service owners, suppliers and affected business users may require different information. Communications should avoid implying that an activity is risk-free and should make any user action clear.
Use controlled release practices. For application and configuration work, changes should be promoted through appropriately separated environments where possible. Automated deployment can improve consistency, but automation itself needs access controls, code review, logging and a method for stopping or reversing a failed deployment. A release should not be considered controlled simply because a tool performed it.
Verify the result against defined acceptance criteria. Completion should mean more than the change being applied. The owner should confirm that the intended function works, monitoring is receiving expected data, security controls remain effective and dependent services continue to operate. Where practical, a service representative should confirm that the business outcome has been achieved.
Monitor for delayed effects. Some changes appear successful initially but create performance, security or data problems later. Post-change observation should therefore consider alerts, logs, capacity, user reports, transaction processing and related service indicators. The length and depth of this observation should reflect the change’s risk and the service’s importance.
Apply a formal exception process. A failed control or undocumented change should not be quietly corrected in the records. Exceptions should state what happened, why the normal process was not followed, what risk remains and who accepted it. Repeated exceptions may indicate that the process is impractical, poorly understood or being deliberately avoided, and should trigger corrective action.
Review outcomes and learn from them. A post-implementation review is particularly useful where a change caused an incident, required unplanned intervention, affected users, or differed materially from its approved plan. The review should examine the quality of the assessment, the accuracy of dependencies, the effectiveness of validation and any weakness in communication. Actions should have an owner and a due date, with completion tracked through service management governance.
Retain evidence for audit and improvement. Records should show the request, assessment, decision, implementation activity, validation, exceptions and review outcome. Retention requirements should reflect the organisation’s contractual, regulatory and security obligations. Regular sampling can test whether the process is being followed in practice, rather than relying on the existence of a policy alone.
For smaller organisations, these controls do not require a large committee or complex software. A defined change policy, a consistently maintained record, named decision-makers, an accurate configuration inventory and a repeatable review process can provide a sound foundation. The important principle is that governance scales with risk without removing accountability from routine work.
IT service management should control cumulative change risk, not only assess each request in isolation. Several individually low-risk changes can interact, affect the same dependency or create a pattern of instability across a service.
Change records should therefore support periodic review by service, system and change type. Repeated failures, incidents linked to similar changes, an unusual concentration of activity or a growing number of exceptions should trigger closer assessment before further work is approved. This gives decision-makers evidence to adjust approval requirements, revise standard procedures or pause a change pattern that is no longer behaving predictably.