
What happens when virtual IT performance degrades?
When virtual IT performance degrades, applications become slower or unreliable, users experience delays and productivity can fall. The issue is usually investigated by examining resource usage, connectivity, workloads, system configuration and underlying infrastructure before applying targeted corrective action.
Virtual IT performance degradation is a measurable loss of responsiveness, capacity or consistency within hosted applications, virtual machines, cloud services or the infrastructure supporting them. The appropriate response is to identify whether the constraint is compute, memory, storage, networking, configuration or an external dependency, then apply a targeted fix and verify that normal service has been restored.
Performance problems are not always caused by insufficient resources. A virtual machine may have adequate processor and memory allocation but still perform poorly because storage input/output is saturated, network latency has increased, a host is contending for resources, or an application is waiting for a database or another service. Treating every incident by simply adding capacity can increase cost without resolving the underlying issue.
Common indicators include:
- Applications taking longer to open, save or process transactions.
- Intermittent freezing, timeouts or failed connections.
- Slow logons, delayed file access or unreliable remote sessions.
- Performance that worsens at particular times, such as during backups, reporting, synchronisation or heavy transaction processing.
- One application or group of users being affected while other workloads remain responsive.
- Increasing queues, processor wait, memory pressure or storage latency in monitoring data.
The first step is to establish the scope and pattern of the degradation. IT staff should record which systems, users, locations and functions are affected, when the problem started and whether the issue is constant or intermittent. Comparing current measurements with an established performance baseline helps distinguish a genuine change from a workload that has always required more capacity than expected.
Investigation should cover the complete service chain. Relevant checks include virtual machine processor and memory utilisation, storage latency and free capacity, host contention, network throughput and latency, service dependencies, operating system events and application logs. It is also important to review recent changes, such as software updates, altered security policies, new users, data growth, configuration changes or scheduled jobs. A problem that appears to be a virtual infrastructure fault may originate in an inefficient query, a failing integration or a network path between the user and the application.
Time-based correlation is particularly useful. If performance falls whenever a backup, replication task or reporting process runs, the workload may be competing for storage or processing resources. If only one site is affected, the investigation should include local connectivity and routing. If all workloads on the same host show a similar pattern, the host, storage platform or shared network is more likely to be involved than an individual virtual machine.
Corrective action depends on the confirmed constraint. Possible measures include:
- Adjusting processor, memory or storage allocations where monitoring shows that the virtual machine is undersized.
- Reducing unnecessary background processes and correcting inefficient application or database behaviour.
- Rebalancing workloads across available hosts or storage resources where shared contention is present.
- Changing the timing or configuration of backups, synchronisation and scheduled processing jobs.
- Resolving network congestion, routing faults, packet loss or unsuitable connection settings.
- Removing obsolete snapshots and addressing storage capacity or performance limitations.
- Applying supported operating system, application or virtualisation updates where a known defect is contributing to the issue.
Changes should be made in a controlled order rather than several at once. After each material change, the affected workload should be tested against the original symptoms and the relevant monitoring data reviewed. This confirms whether the action solved the cause, merely masked it or introduced a new limitation. Any temporary workaround should be documented with a permanent remediation plan where necessary.
Prevention relies on capacity management and meaningful monitoring. Monitoring should track resource use, latency, availability, capacity trends and service dependencies rather than processor utilisation alone. Thresholds need to reflect the workload: a short processing spike may be normal, whereas sustained storage latency during core business activity may require investigation. Regular reviews can identify data growth, changing user demand and workloads that are approaching the limits of their current design.
Performance degradation can also expose weaknesses in the wider service design. If a single host, storage path, network connection or application dependency is critical to several workloads, its failure or saturation can have a disproportionate effect. Reviewing resilience, backup processes, access methods and recovery arrangements alongside performance findings helps ensure that the same issue does not create a larger operational disruption.
A managed IT provider such as S2 Technology Group can support this process by monitoring virtual environments, assessing capacity, investigating faults across infrastructure and applications, and recommending changes that match the organisation’s operational requirements. The objective is not simply to make a system faster temporarily, but to restore predictable performance and maintain an infrastructure that can be measured, managed and scaled appropriately.
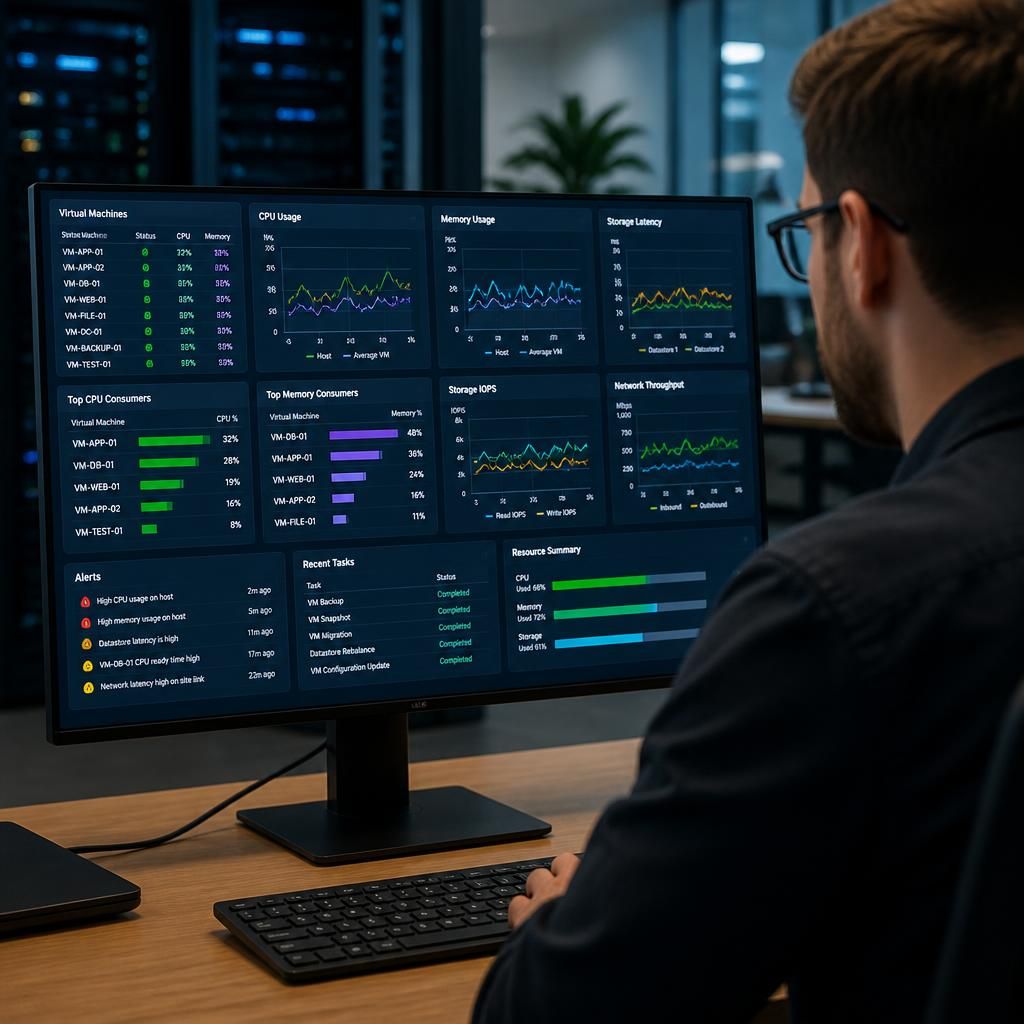
Virtual IT performance can degrade because the physical host is struggling to schedule resources between virtual machines, even when the affected machine’s allocated capacity appears adequate. This is known as host-level contention: several workloads compete for processor time, memory or storage access, causing delays that are not visible from the virtual machine’s own allocation figures.
For example, processor demand may leave a virtual machine waiting for its turn to run, while memory pressure can cause data to be moved between memory and storage. A separate workload performing intensive processing or storage activity may also create a noisy-neighbour effect, where one virtual machine affects others sharing the same host or storage platform.
Resolving this type of degradation requires host-level evidence rather than simply increasing the affected machine’s resources. Reviewing scheduling delays, memory pressure, storage queues and the activity of neighbouring workloads can show whether the virtual machine should be moved, rebalanced or given a different resource profile. This helps prevent additional capacity being assigned where the actual constraint exists elsewhere.