
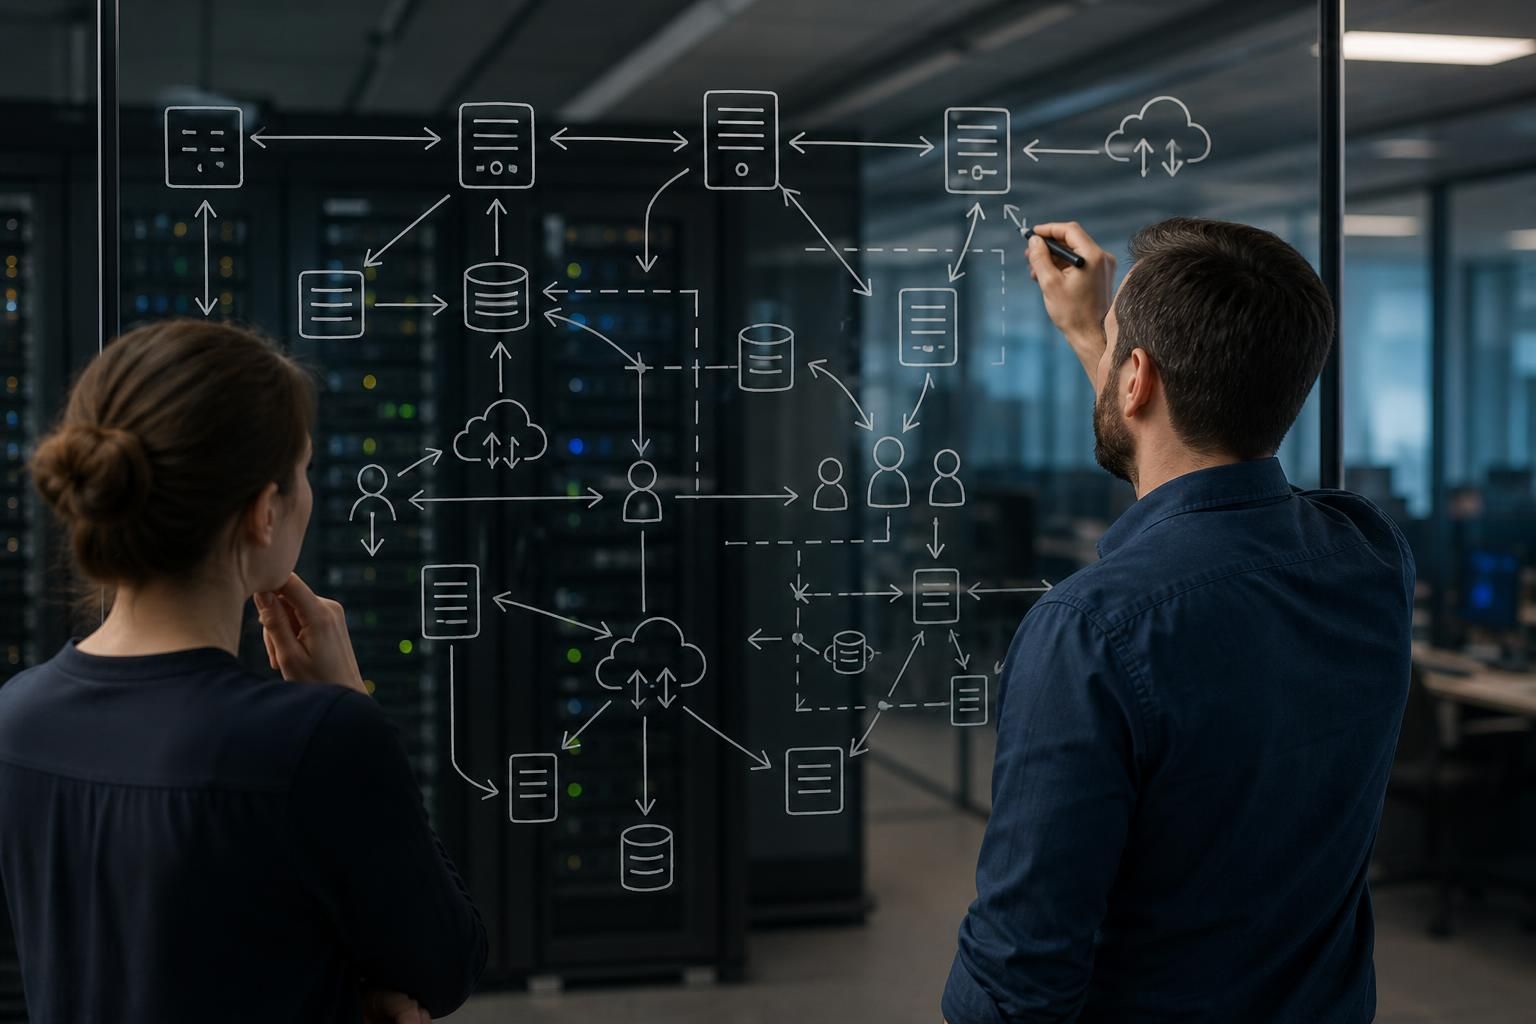
How does a managed IT services provider identify hidden dependencies?
A managed IT services provider identifies hidden dependencies by combining asset discovery, configuration reviews, network mapping, system logs and discussions with staff who understand day-to-day processes. It then tests how applications, devices, accounts, suppliers and data flows rely on one another, documenting single points of failure and dependencies that could affect continuity, security or planned changes.
Hidden dependencies are relationships between systems, devices, people, suppliers or processes that are necessary for a business service to function but are not clearly documented. A managed IT services provider identifies them by tracing how services operate in practice, validating those relationships with technical evidence and business users, and assessing what would happen if one component were unavailable, changed or compromised.
It starts with business services rather than isolated equipment. A server, application or network device has limited meaning on its own. The assessment first considers the services the organisation relies on, such as order processing, production control, document management, finance or access to shared data. Each service is then broken into its supporting elements: applications, databases, authentication, connectivity, endpoints, integrations, suppliers and the people responsible for key tasks.
This approach can reveal dependencies that an inventory alone would miss. For example, an application may appear to run on one server but also depend on a particular database account, a scheduled task, a file share, a certificate, a DNS record or an external data exchange. A process may depend on one employee knowing how to approve an access request or restore a failed service. These relationships are operational dependencies even when they are not represented in a technical diagram.
Configuration and identity relationships are examined in detail. Providers review how systems authenticate users, where privileged accounts are used, which services communicate with one another and how permissions are inherited. They look for shared credentials, service accounts tied to individual users, hard-coded addresses, manually maintained access groups and authentication systems that have no practical alternative. Such findings can indicate both resilience concerns and security weaknesses.
They also inspect the settings that connect components together. Examples include firewall rules, routing, virtual networks, backup jobs, synchronisation tasks, application connectors and certificate stores. A change to one setting may affect several services, particularly where older systems or bespoke integrations are involved. Recording these links helps distinguish a safe change from one that requires testing, approval or a rollback plan.
Dependency mapping is validated against real use. Documentation may be incomplete or describe an intended design rather than the current environment. A provider therefore compares diagrams and configuration records with monitoring data, event logs, support records and observed traffic. It may trace a transaction from a user device through the network to an application, database and external service. Interviews with staff then establish which steps are genuinely required and which workarounds are used when systems behave differently from the documented process.
Care is needed when interpreting technical evidence. An inactive-looking connection may be used only at month-end, while a service that appears central may have a redundant replacement. Reviewing activity over relevant business cycles and confirming findings with process owners reduces the risk of treating temporary or historic relationships as permanent dependencies.
External and physical dependencies are included. A business service may rely on an internet connection, telecommunications circuit, hosted platform, software supplier, payment service, outsourced process or third-party data feed. It may also depend on power distribution, environmental controls, a secure site, specialist hardware or access to a particular location. These dependencies need owners, contact routes, contract details and documented alternatives where continuity matters.
The assessment should distinguish between direct and indirect dependencies. A payroll system may directly require its database and authentication service, while indirectly relying on connectivity, a supplier’s interface and an administrator who can resolve failed imports. Indirect relationships are often overlooked because they sit outside the application owner’s immediate responsibility.
Each dependency is assessed for business impact and change risk. Useful questions include:
- Which business activities stop or degrade if this component fails?
- Is there a documented alternative, and has it been tested?
- How much data could be lost or become inconsistent?
- Which other services would be affected by a change?
- Who owns the component and who can authorise remedial work?
- Does the dependency create a security, compliance or supplier risk?
This produces more useful results than simply labelling items as critical or non-critical. A dependency can be low risk during normal operations but highly significant during a software upgrade, network fault, cyber incident or loss of a key administrator. Risk records should therefore capture the circumstances in which the dependency becomes important.
Findings are recorded in a form that supports decisions. Depending on the environment, this may include service maps, dependency registers, data-flow diagrams, ownership records, recovery prerequisites and change-impact notes. Each record should identify the relationship, evidence supporting it, responsible owner, consequence of failure, current control and any unresolved assumption. Unknowns should be marked for validation rather than presented as confirmed facts.
Finally, the provider prioritises remediation. Typical actions may include removing unnecessary links, separating shared accounts, adding resilience to a single component, updating unsupported integrations, documenting manual procedures, improving supplier information or testing recovery steps. The objective is not to eliminate every dependency; interconnected systems are unavoidable. The objective is to make important dependencies visible, owned, proportionate to risk and considered before failure or change exposes them.
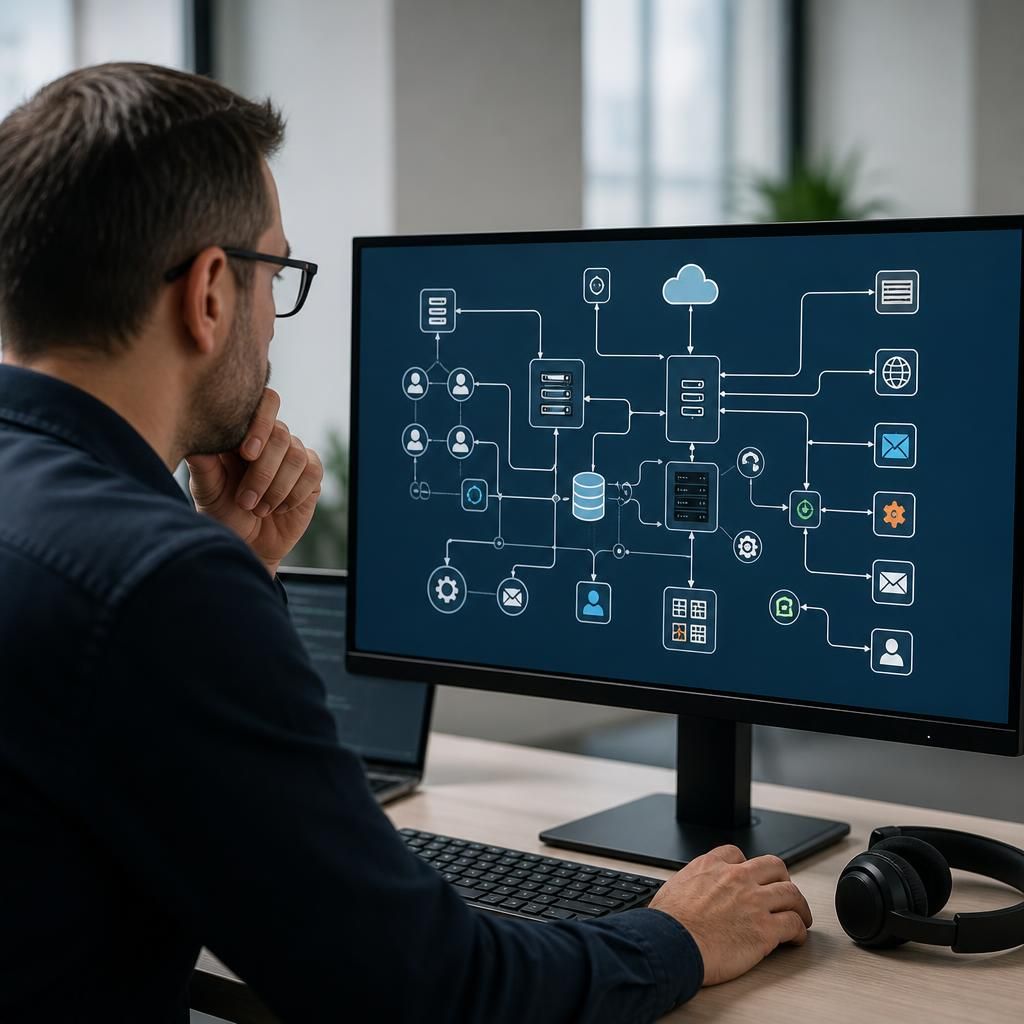
Some hidden dependencies are based on timing rather than a visible connection between systems. A managed IT services provider therefore examines job schedules, processing queues, synchronisation intervals and task order to identify situations where one activity must finish before another can begin.
This can reveal sequencing assumptions such as an overnight export needing to complete before a reporting process starts, or a synchronisation task needing to run before users access updated information. The provider compares timestamps and process requirements with the organisation’s working practices, then records the order, timing constraint and consequence of delay. This helps prevent changes that technically leave each component available but disrupt the sequence the business service depends on.