
What role does cloud backup play in business disaster recovery?
Cloud backup supports business disaster recovery by keeping recoverable copies of important data separate from the primary IT environment, so files can be restored after incidents such as hardware failure, accidental deletion, ransomware or site disruption. It forms one part of a complete recovery plan: restoring data does not, by itself, rebuild applications, systems, user access or business operations.
Cloud backup is the data-protection layer of a business disaster recovery plan. It preserves usable versions of business information in cloud storage and provides the recovery source needed when production data is unavailable, corrupted or no longer trustworthy. Its value depends not only on making copies, but also on retention, security, recoverability and how well the backup process fits the wider recovery plan.
Cloud backup contributes to disaster recovery in several important ways:
- It separates recovery data from day-to-day operations. A backup held in a suitably protected cloud environment is less dependent on the equipment, premises or storage used by the live system.
- It preserves earlier versions. Version history and retention policies can allow an organisation to recover a clean copy from before an error, corruption event or malicious change occurred.
- It supports recovery after loss of access to a site. If local infrastructure cannot be used, cloud-held data may remain available to an alternative recovery environment, subject to the organisation’s connectivity, applications and access arrangements.
- It makes recovery procedures more repeatable. Centrally managed policies can define what is protected, how long it is retained and which users or systems can initiate a restore.
Cloud backup should not be confused with file synchronisation, ordinary cloud storage or a replicated live system. Synchronisation can copy an unwanted deletion or encrypted file across locations. A replicated system may reproduce corruption almost immediately. A proper backup service maintains controlled recovery points and retention rules, giving the organisation a choice of versions rather than simply mirroring the current state.
The design of the backup determines how useful it will be during a disruption. A business should identify the data and workloads that are essential to its operations, including file servers, databases, virtual machines, application data, user accounts and cloud-based services where appropriate. It should then establish which recovery points are required and how long different data types must be retained. Critical transactional data may need more frequent protection than archival material, while legal, contractual or regulatory requirements may require longer retention.
Recovery point objectives and recovery time objectives connect cloud backup to operational planning. The recovery point objective defines how much recent data the organisation could afford to lose. The recovery time objective defines how long a system can remain unavailable. Backup frequency, retention, restore methods, network capacity and the order in which systems are recovered must all be consistent with those objectives. A backup that is technically sound may still be unsuitable if restoring it takes longer than the business can tolerate.
Recovery also involves more than returning files to storage. Applications may require databases, configuration files, encryption keys, licences, directory services and other dependencies. Users may need their permissions restored, and systems may need to be rebuilt before backed-up data can be used. A disaster recovery plan should therefore document the sequence for restoring core services, the people responsible for each step and the conditions for declaring systems ready for use.
Security controls are particularly important because backup repositories are attractive targets for attackers. Access should follow least-privilege principles, with administrative accounts protected by strong authentication and separated from ordinary user accounts. Data should be encrypted in transit and at rest, and backup credentials should not be stored in a way that allows a compromise of the production environment to expose every recovery copy. Immutability, write protection or an isolated recovery location can help prevent unauthorised alteration or deletion during a ransomware incident.
Retention alone does not prove that a backup can support recovery. Restore testing should be planned and documented rather than performed only after an incident. Tests can include restoring individual files, recovering application data, rebuilding a server and validating that users can access the restored service. Results should record what was tested, whether the data was complete, how long the process took and which corrective actions are needed. A successful backup job reports that data was copied; a successful recovery test demonstrates that the copy is usable.
Cloud backup introduces dependencies that should be considered in advance. These include internet connectivity, authentication services, encryption-key access, the backup provider’s platform and the organisation’s ability to reach the restored environment. If the primary network is unavailable, the plan may require an alternative connection or a separate recovery location. Large-scale restores may also need prioritisation so that essential systems are recovered before less critical data.
A practical cloud backup and disaster recovery arrangement should define:
- which systems, data and configurations are within scope;
- how frequently each workload is protected;
- which recovery points are retained and for how long;
- who can access, approve and perform restores;
- how backups are protected from alteration, deletion and ransomware;
- the order in which systems and dependencies are recovered;
- how recovery is tested and evidenced;
- how the plan addresses loss of the primary site, network or administrative accounts; and
- when the backup design and recovery procedures are reviewed after business or technology changes.
For small and medium-sized organisations, managed cloud backup can provide a structured way to apply these controls without requiring a large internal infrastructure team. The important question is not simply whether data is stored in the cloud, but whether the arrangement provides secure, identifiable and tested recovery points that support the organisation’s agreed disaster recovery objectives.
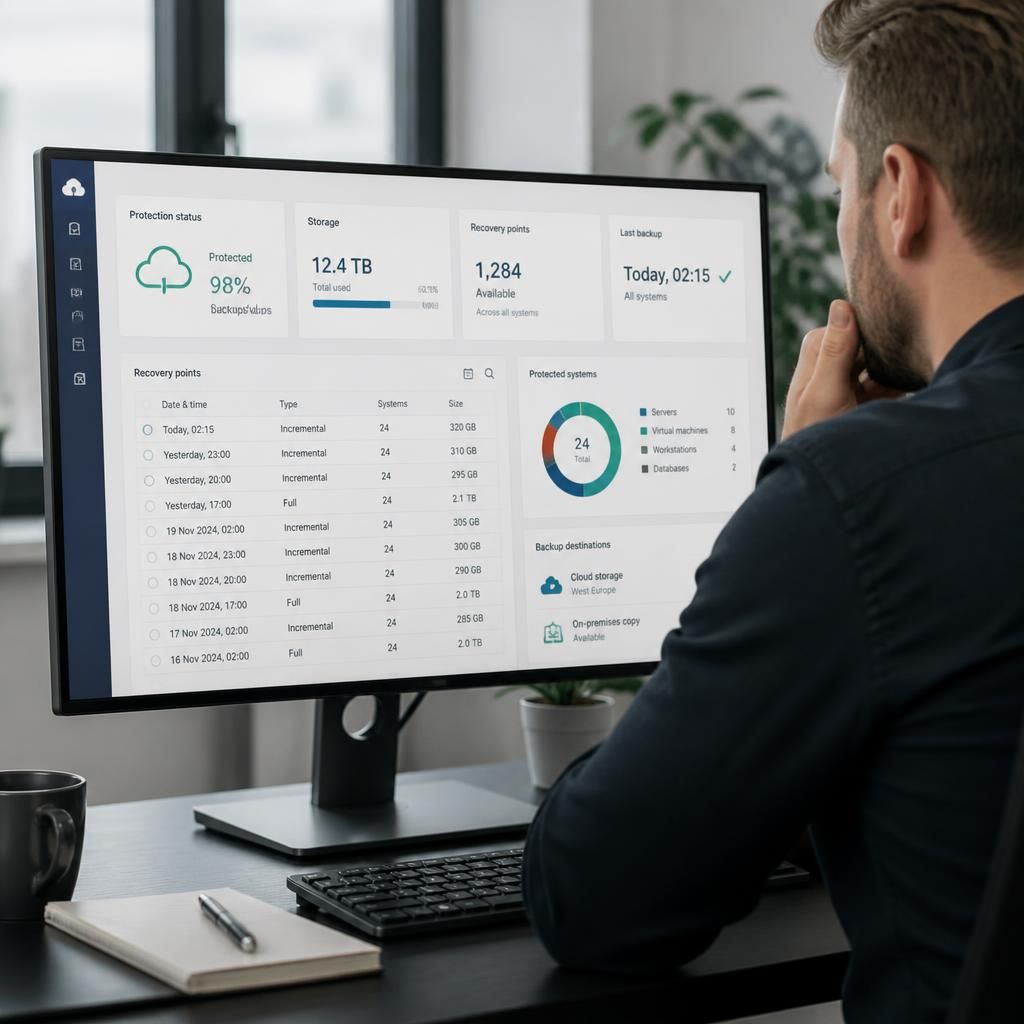
Cloud backup helps the recovery team choose a trustworthy point in time. The newest available copy is not always the correct one to use. If malware, unauthorised changes or a configuration error has been present for several days, restoring the latest version could reintroduce the problem. A recovery process should therefore compare recovery-point timestamps with security alerts, system logs and the point at which users first noticed the disruption.
This gives the disaster recovery team a basis for selecting a clean version while avoiding unnecessary loss of newer, unaffected data. The chosen copy can then be restored in a controlled environment and checked before it is returned to production. In this role, cloud backup provides more than storage: it gives the organisation a dated history from which recovery decisions can be made and evidenced.