
What should an offsite backup plan include?
An offsite backup plan should define which data is protected, how often backups run, where copies are stored, how long they are retained and who can access them. It should also cover encryption, protection against deletion or ransomware, backup monitoring, restore testing, recovery priorities and the responsibilities for reviewing and maintaining the plan.
An effective offsite backup plan is a documented recovery design that connects business requirements with the systems, data, people and procedures needed to restore operations. It should explain not only what is copied, but also what must be recovered first, which dependencies are involved, how recovery will be carried out and how the plan will be kept accurate as the organisation changes.
Start with a business impact assessment. Identify the activities that would be affected by data loss, such as order processing, financial administration, customer service, production or access to shared documents. Record the consequences of different outage scenarios and define the maximum tolerable disruption for each important service. This gives the backup plan a business basis rather than treating every file and application as equally important.
The assessment should also identify dependencies. An application may rely on a database, directory service, virtual machine, network configuration, licence information or specialist hardware. Restoring the application without these dependencies may not return it to a usable state. Documenting those relationships helps the recovery team follow a workable sequence instead of attempting isolated restores.
Define the technical scope precisely. An inventory should cover more than office documents. Depending on the organisation, it may need to include:
- Servers, virtual machines and critical workstations;
- Databases and application data;
- Shared drives, cloud-synchronised files and collaboration data;
- Device configurations, system images and infrastructure settings;
- Source records, financial information and operational files;
- Identity, access and configuration information required to rebuild services; and
- Data held at branches, remote sites or on equipment used away from the main office.
List deliberate exclusions as well as protected systems. Temporary files, caches and duplicated data may not need the same treatment as authoritative records. Exclusions should be agreed, documented and reviewed so that an assumption does not become an unnoticed gap.
Choose a recovery method for each workload. File-level recovery may be suitable for individual documents, while a server or database may require an application-aware restore. Application-aware protection records data in a state that the application can use consistently, reducing the risk of restoring files that appear complete but contain incomplete transactions. Where systems are virtualised or hosted in the cloud, the plan should state whether recovery means rebuilding the service, restoring a complete image or transferring data to another environment.
The plan should also describe how versions are selected. A recent copy may contain corruption or unwanted changes, whereas an older version may be needed to recover from a problem that was discovered later. Define how recovery staff identify a suitable restore point and how restored data is checked before it is returned to users.
Account for network and infrastructure constraints. Large restores can place substantial demand on internet links, storage systems and local networks. Estimate the volume of data that would need to be transferred and identify whether the recovery location has sufficient capacity, compatible systems and the necessary connectivity. Include a method for prioritising traffic or transferring particularly large datasets where normal network capacity would be unsuitable.
Recovery instructions should cover practical prerequisites, including administrator credentials, access to the backup console, licensing details, encryption key procedures, replacement equipment and contact details for relevant suppliers. Sensitive recovery information should not be left in an openly accessible document. Store it under controlled access and make sure authorised recovery personnel can obtain it when the usual identity systems are unavailable.
Assign recovery roles and decision points. A sound plan distinguishes between technical recovery and business approval. It should identify who can declare a recovery event, who decides whether a system is ready for use, who communicates with staff and customers, and who records decisions made during the incident. Include an escalation route for situations where a restore is incomplete, a backup is suspected of being compromised or the original environment cannot be used.
Use clear runbooks rather than relying on the memory of one administrator. A runbook might include the order of recovery, prerequisites, commands or console actions, validation checks and rollback steps. It should be understandable to another suitably authorised person, particularly where the organisation has a small IT team or depends on external technical support.
Test the plan under realistic conditions. A successful backup job does not prove that the business can recover. Tests should include individual files, complete services and scenarios involving damaged or unavailable primary infrastructure. Validate that restored applications open correctly, records are usable, permissions behave as expected and users can perform essential tasks. Record the result, any delay or error, and the corrective action required.
Testing should include the human process as well as the technology. Confirm that the relevant people can find the instructions, access the required credentials, make recovery decisions and communicate progress. Repeat tests after major changes, such as a new line-of-business application, office move, cloud migration, infrastructure replacement or change in staffing.
Set review triggers and keep evidence. The plan should have a named document owner, a revision history and a record of the systems and assumptions it covers. Review it when applications, data locations, network arrangements, suppliers or business processes change. Keep evidence of backup activity, restore tests, identified exceptions and remedial work so that management can see whether the plan remains fit for purpose.
For an SME, the finished document should be concise enough to use during a disruption but detailed enough to remove guesswork. A useful final check is whether someone with appropriate authority can identify the affected service, obtain the required access, restore its dependencies, validate the result and record the decision to return it to operation. If any of those steps depends on undocumented knowledge, the offsite backup plan is not yet complete.
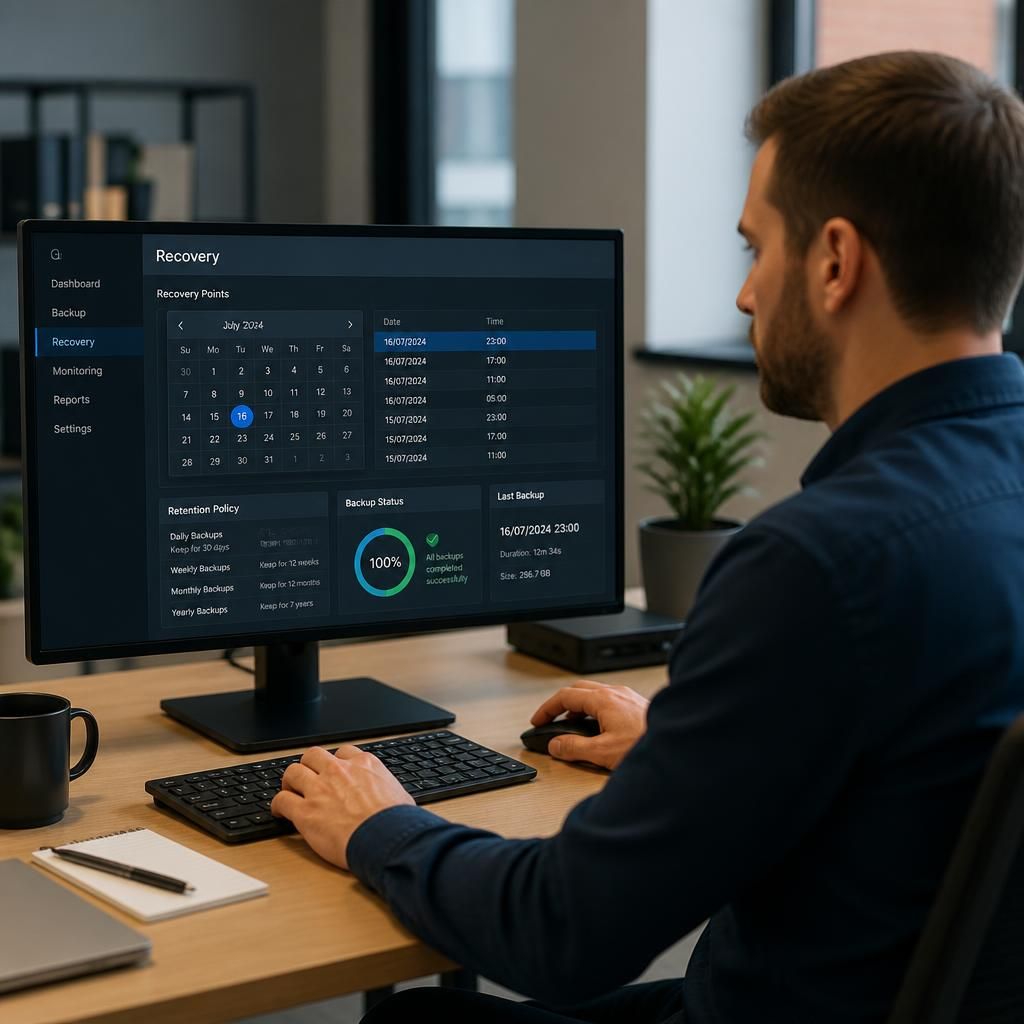
Retention rules are a core part of an offsite backup plan because they determine which recovery points remain available and when older copies can be deleted. The plan should specify retention periods for different data types rather than applying one rule to every system.
For example, frequently changing operational data may need several recent restore points, while financial records or project files may require longer-term retention. The policy should distinguish between backup copies used for operational recovery and records retained to meet legal, contractual or internal requirements. It should also explain who can approve deletion, how retention exceptions are recorded and what happens when a legal hold or investigation prevents normal deletion.
Retention should be reviewed against storage capacity, data sensitivity and the organisation’s record-keeping obligations. Clear rules reduce the risk of deleting a useful recovery point too soon or retaining unnecessary copies without proper oversight.