
How are backup restores prioritised during a major outage?
During a major outage, backup restores are prioritised according to business impact, recovery time objectives (RTOs), system dependencies and the integrity of the available restore point. Critical services and the infrastructure they rely on are restored first, followed by lower-priority systems, with the recovery sequence defined in the organisation’s disaster recovery plan.
Backup restore prioritisation is a controlled decision process that determines which data, applications and supporting infrastructure should be recovered first, in what order and under whose authority. During a major outage, the aim is not simply to restore the largest systems first; it is to restore a usable operating environment while preserving evidence, avoiding reinfection and making the best use of available recovery resources.
A practical prioritisation model normally begins with a pre-agreed service catalogue. Each business service is linked to its applications, databases, servers, identity systems, network components and key data sets. This mapping helps the recovery team understand what must be restored together and prevents an application being brought back before the systems it needs to function.
The recovery process commonly includes the following stages:
- Incident classification: confirm the scale and cause of the outage, such as hardware failure, accidental deletion, a cyber incident or loss of site access.
- Restore authorisation: appoint an incident lead who can approve the sequence, resolve competing requests and record important decisions.
- Recovery assessment: identify affected services, available backup copies, suitable restore points and any restrictions on the recovery environment.
- Dependency planning: establish whether identity, DNS, network access, databases, virtualisation or other shared components must be restored before individual applications.
- Controlled restoration: recover systems in an isolated or suitably protected environment, then release them for use only after validation.
Not every restore request has the same urgency. A service may support revenue-generating work, regulatory obligations, customer access, production, internal administration or future recovery activity. These factors can be recorded in a recovery matrix so that decisions are based on agreed business rules rather than whichever department raises the loudest request.
Data sensitivity also affects the order and method of recovery. If an outage may involve ransomware or unauthorised access, the team should establish that the selected copy predates the compromise and has not been altered. Restoring a clean backup into an unprotected environment can expose it to the same threat, so security controls, endpoint protection, access permissions and monitoring may need to be prepared before business applications are reconnected.
Restore points are selected using more than their timestamp. The recovery team may compare backup logs, application consistency, transaction records and known changes made shortly before the incident. In some cases, a slightly older but verified application-consistent copy is preferable to a newer copy with errors or signs of tampering. Where several copies are available, their separation, integrity and recoverability should be checked before assigning them to the restore queue.
Restoration can be carried out in parallel where sufficient infrastructure and staff are available, but parallel work is not always the fastest or safest option. Shared storage, authentication services, bandwidth and specialist personnel can become bottlenecks. A recovery plan should therefore identify which tasks can run concurrently and which must wait for a prerequisite, while avoiding competition for the same constrained resource.
Each restored service should pass technical and business validation before it is marked as usable. Technical checks may cover boot status, database integrity, network connectivity, permissions, backup agents and security controls. Business owners should then confirm that relevant transactions, documents, integrations and user workflows operate correctly. A system that is online but cannot process dependable business data should remain in recovery rather than being treated as complete.
Priorities may change as information develops. For example, a previously unavailable dependency may become recoverable, a suspected compromise may rule out a restore point, or a business service may become more important because another workaround has failed. The incident lead should document changes to the sequence, the reason for each change and any risks accepted as a result.
Good preparation makes these decisions faster and more consistent. A disaster recovery plan should define service owners, escalation authority, dependencies, approved restore sources, isolation requirements, validation steps and communication responsibilities. Restore exercises can reveal missing credentials, undocumented integrations, excessive manual work and recovery bottlenecks before a real outage exposes them.
S2 Technology Group helps businesses review backup and disaster recovery arrangements as part of wider managed IT and cyber security support. The objective is to turn backup copies into a tested recovery process, with clear priorities and controls that reflect how the organisation actually operates.
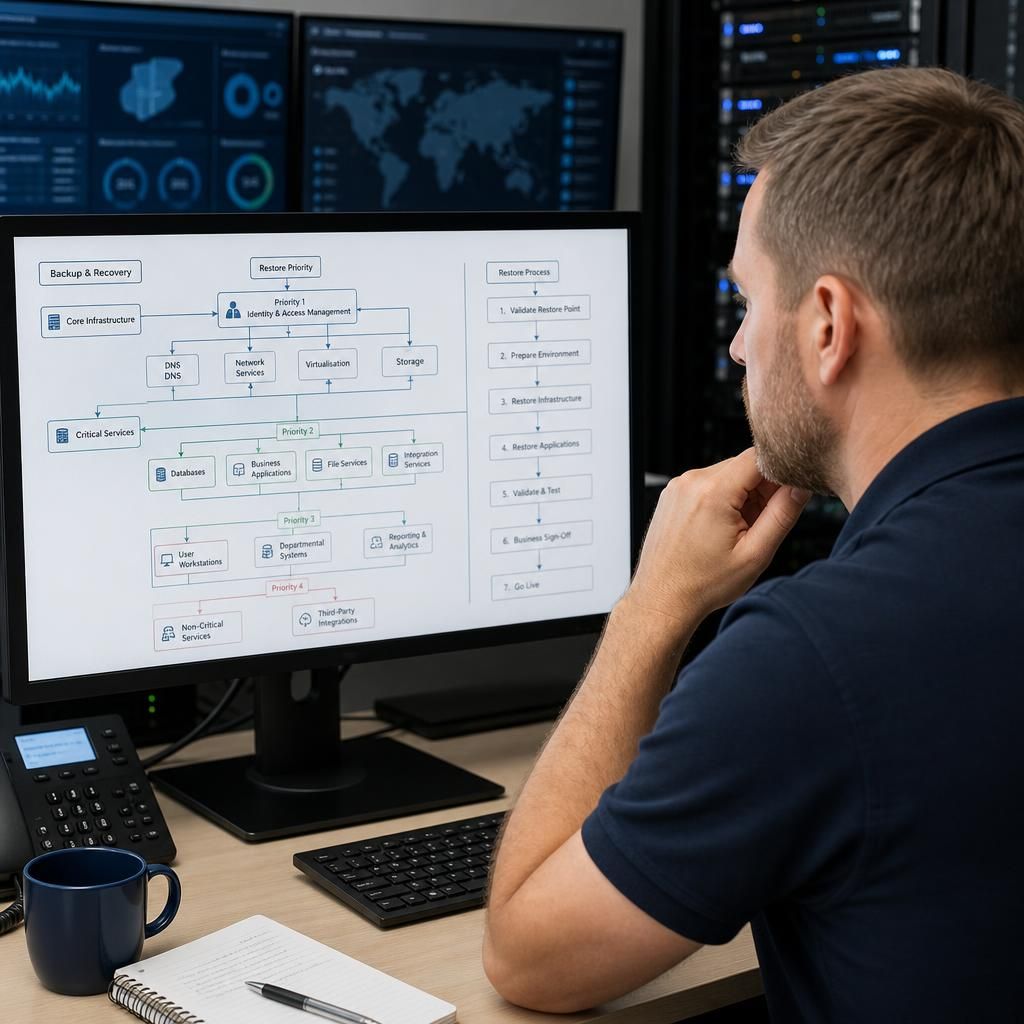
Backup restores should be managed as a controlled recovery queue, with clear entry and exit criteria for each item. A system should enter the queue only when its restore source, recovery environment and responsible owner have been confirmed. It should leave the queue only when the restore has been checked and the business owner has accepted its operational status.
- Entry criteria: confirm the approved restore point, required resources and any security prerequisites.
- Progress criteria: record which stage the restore has reached, including data recovery, application start-up and user access testing.
- Stop criteria: pause the restore if integrity checks fail, unexpected dependencies appear or the environment shows signs of compromise.
- Completion criteria: obtain technical evidence and business confirmation before releasing the service for normal use.
This approach prevents an incomplete or unreliable restore from being treated as a successful recovery. It also gives the incident lead a consistent basis for deciding whether to continue, investigate, or move resources to another item in the queue.